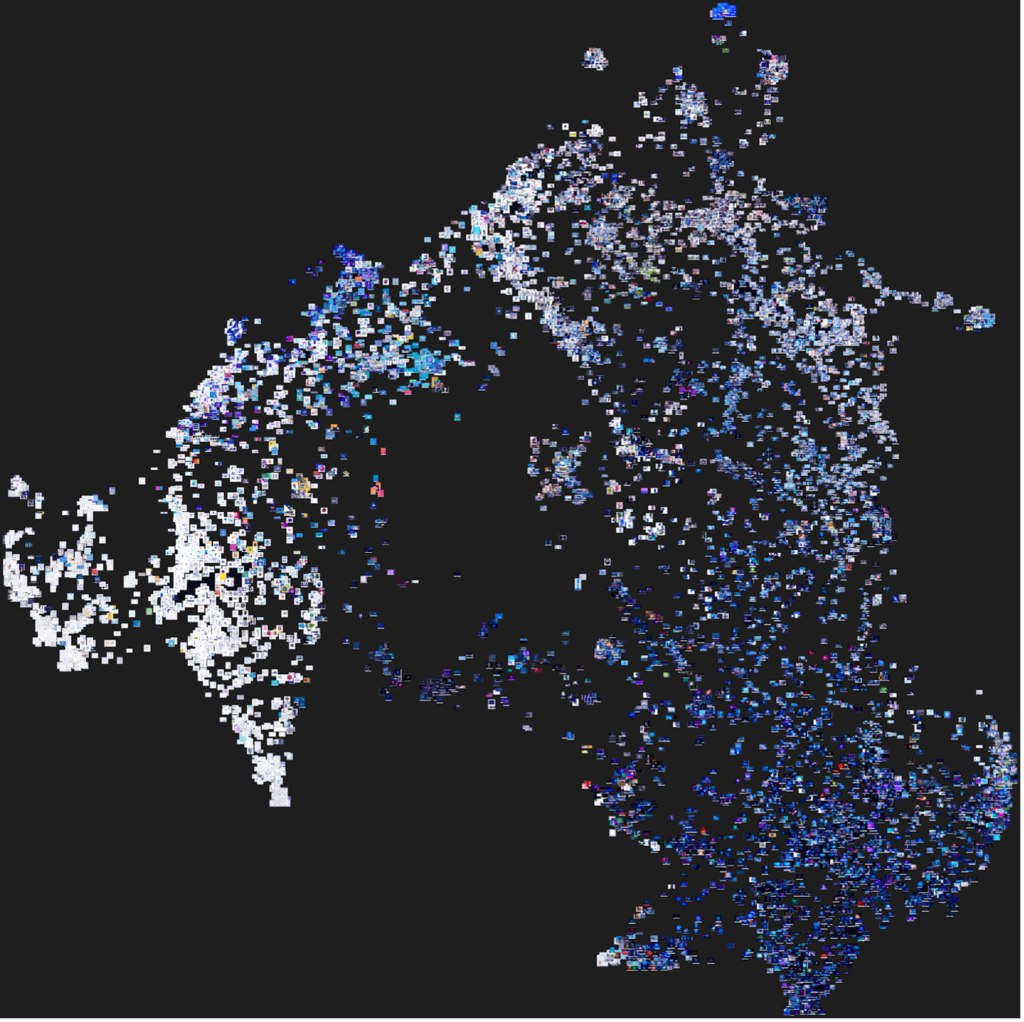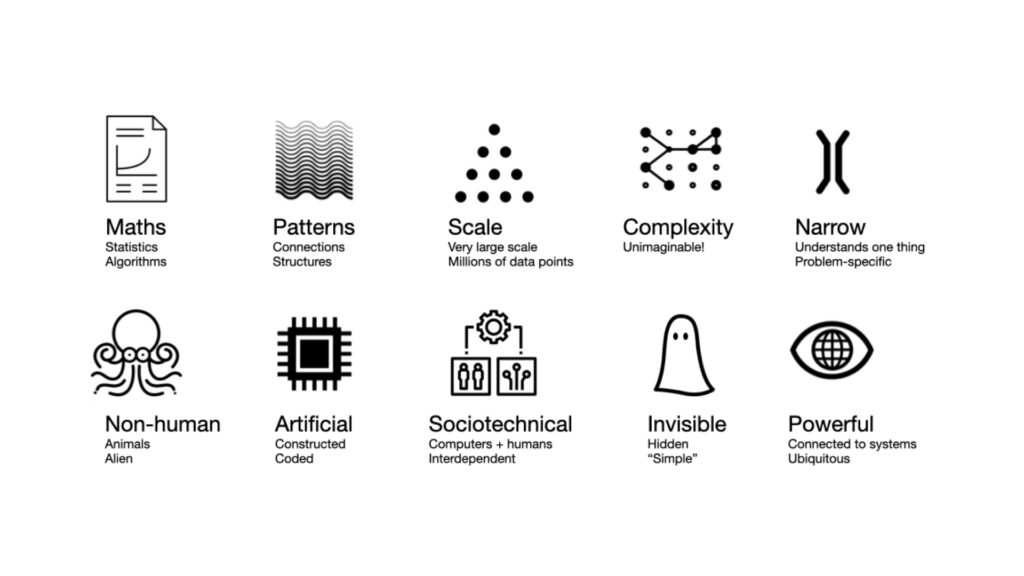
The glowing blue brain – the visual myth of AI cognition 

Four overlapping, staggered rectangles in different shades of blue are overlayed by a glowing circle. beneath, the title reads 'The glowing blue brain – the visual myth of AI cognition'

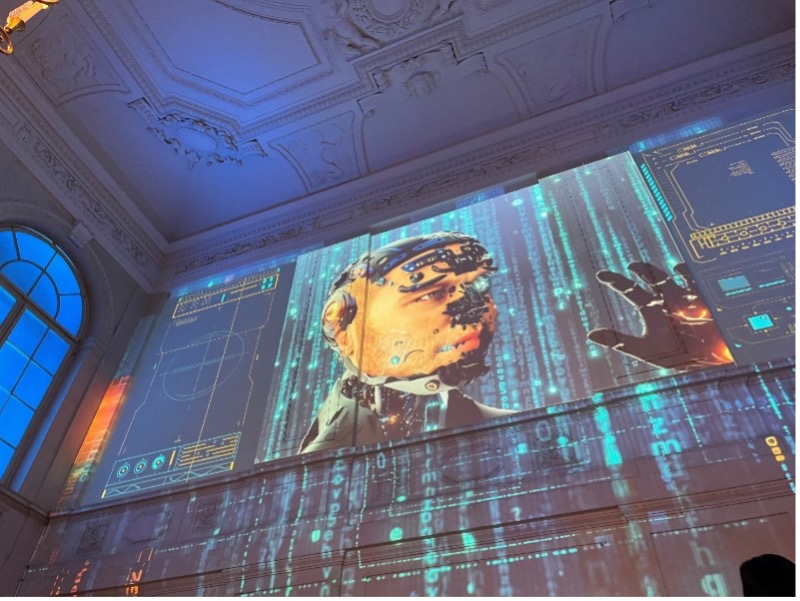
There is a blue hue in the darkness. Upon closer examination, it is a glowing blue brain, threaded with circuits and inscribed with binary code. This is not an unfamiliar sight; instead, for many of us, it is a common visual of the expansive and unstable notion of ‘artificial intelligence’ (‘AI’). Such visual representations of AI systems have become commonplace.

In this blog post, Raghu Krishnan unpacks the prominence of the glowing blue brain imagery as a visual signifier of AI and considers its implications for public understanding. The post focuses on three primary visual tropes: the use of luminosity or glow, the brain form and personhood, and lastly the colour blue itself, which combine to create an elaborate visual myth of AI cognition.

“The blue, the glow and the brain form combine to create a culturally situated myth of machine cognition.” 

Blue, Glow, Brain

Images associated with the blue brain metaphor for AI often include a luminous brain form surrounded by circuits and binary code, placed near a dark, futuristic background. Instead of showing AI as infrastructure, code, machinery, data or labour, it is depicted as a glowing centre of thought. In this vein, meaning comes from a combination of different components, from the brain to the use of the colour blue, and even the use of luminosity itself, that combine to provide us with a trope which presents the alignment of computation and cognition.
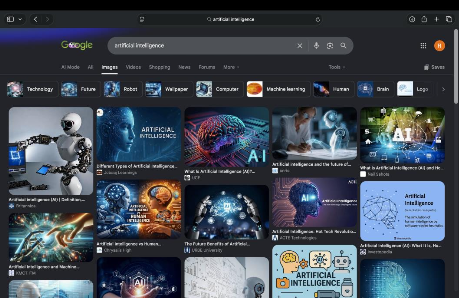
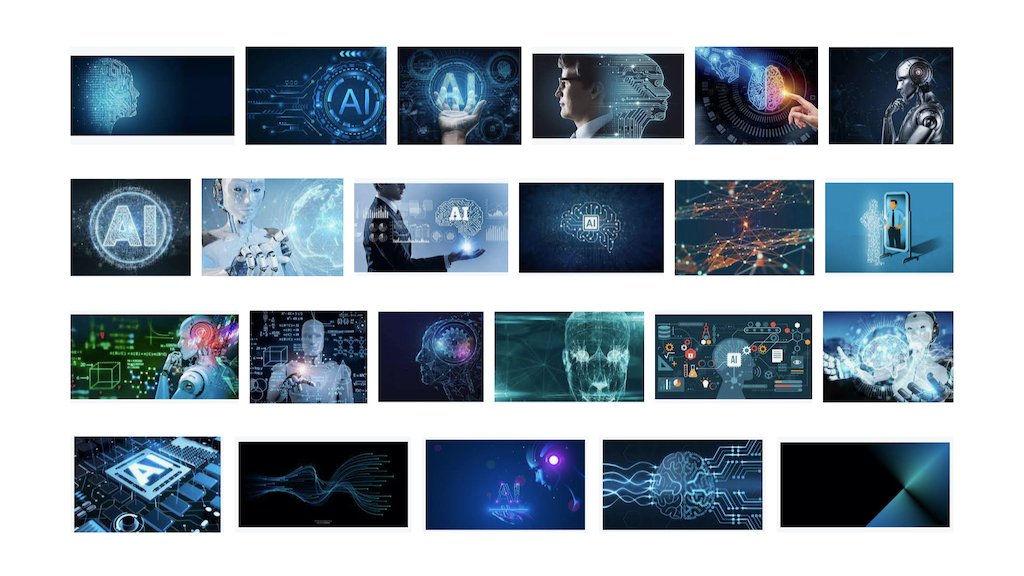
A screenshot of Google imagery shows a series of futuristic images of glowing blue brains, white robots, and holograms.
Figure 1. A quick Google search for ‘visualising AI confirmed the prominence of blue brain imagery. Screenshot by author on 14 July 2026.

Here, semiotic work by Sorensen and Thellefsen (2024) is useful; they claim that the blue brain metaphor in all its forms has become a foundational part of the contemporary imagery around AI. In their view, the “blue brain metaphor” for AI is clearly related to the primarily verbal metaphor “the computer is a brain”, while also moving beyond this and attaching itself to a diversity of other meanings related to potential cognition. In terms of signs and symbols, they view the metaphor as part of Umberto Eco’s notion of a socio-cultural encyclopaedia, where Eco proposed that a larger shared cultural knowledge is utilised to interpret such signs. So, for instance, the blue brain can be assigned ideas of trust due to an existing shared cultural understanding of the brain; this ‘encyclopaedia’, in his view, is open-ended, where people attach endless contextual meanings to signs embedded in a shared societal network. Simply put, these visual signs are connected to expanding and interconnected cultural knowledge, which impacts interpretation. It is this contextual nature of interpretation of images and signs that is underscored throughout the article. 

Make me Glow

Glow or illumination may seem almost natural in imagery surrounding future technology, as well as in attempts to showcase the inner workings of the mind. More recently, there have been attempts to construct an ‘anthropology of luminosity’ showing how the use and experience of light are culturally embedded. Bille and Sørensen (2007), in their work, An Anthropology of Luminosity, argue that philosophical treatises and critiques have often neglected the social role of light, the role of illuminating people, places, experiences, biases, and myth. While light is a concrete physical phenomenon, it also has its ‘lux’, or the sensual qualities formed through sight and vision. The Western primacy of vision perpetuates the importance of light and vision in experiencing the world and, often, in forming concepts (Levin, 1993). It is this emphasis on light which finds itself represented in the ‘glow’ of the blue brains used to represent AI. 

Here, this importance is sketched onto social settings, as ‘lightscapes’ operating through the interaction of light and its environment. An example of the culturally relative experience of light comes from the work of Japanese author Tanizaki, who argues that the role of shadows, or the appreciation of shadows, was crucial in Japanese material culture and way of life. Japanese aesthetics, in this view, placed a cultural emphasis on indirect light, in which material culture was meant to interact with shadows, from lacquer and ceramics to paper. Appreciation for such items, in Tanizaki’s account, relied heavily upon their emergence from the darkness, an appreciation that eventually gave way to ‘intense illumination from the west’. Therefore, the glowing brains borrow the social role of light, which is situated in the West, neglecting other cultural notions of light, as seen in Tanizakis account. 

While light is physical and sensory, it may also extend to the sacred. Morphy (1989), Gage (1995) and Pinney (2001) all argue that colour and light create luminosity, which may have sacred and spiritual dimensions, and that brilliant objects are conceived as the material manifestation of light. Here, brilliant glowing orbs, lamps, and, in our case, blue brains become objects emitting light. In these contexts, light is often imagined as a signifier of ancestral power or, in our case, future power, where the glowing blue brains signal technological potency and imagined authority in the future. Luminosity gives the AI an aura, where computation may appear as sacred.

Apart from affective qualities, the presence or absence of light has also functioned as an important metaphor in Western philosophy. From the classical age, light has often been interpreted as an important metaphor through which people experience the world; for instance, in Plato’s allegory of the Cave, prisoners mistake shadows for reality, while the movement towards light represents a transition from illusion to knowledge (Plato, 2007). 

Similarly, from the Enlightenment, light was seen as a medium through which knowledge was revealed; light hence finds itself deeply entwined with the notion of life and existence, the dead, or the soulless find themselves depicted as dark or lacking illumination. A more recent example is the use of the ‘lightbulb moment’ in comicbooks, where a lightbulb over a character’s head would signal a sudden moment of inspiration. Therefore the glowing brains borrow this  association of light with knowledge and inspiration  situated in the west, to construct an elaborate myth of cognition.

In essence, we have three different notions of light: the material lux, or glow, the social agency of light, and lastly the metaphorical light; importantly, all of these are culturally embedded. In the context of our image, materially the brain glows, socially it signals future authority, and metaphorically it points to ideas of consciousness and life. The glow of the brain  condenses these notions into a single image. The anthropology of light, in a way, provides a framework to interpret the powerful visual of the glowing blue brain, where material, social and psychological notions of light are projected onto the (blue) brain form.
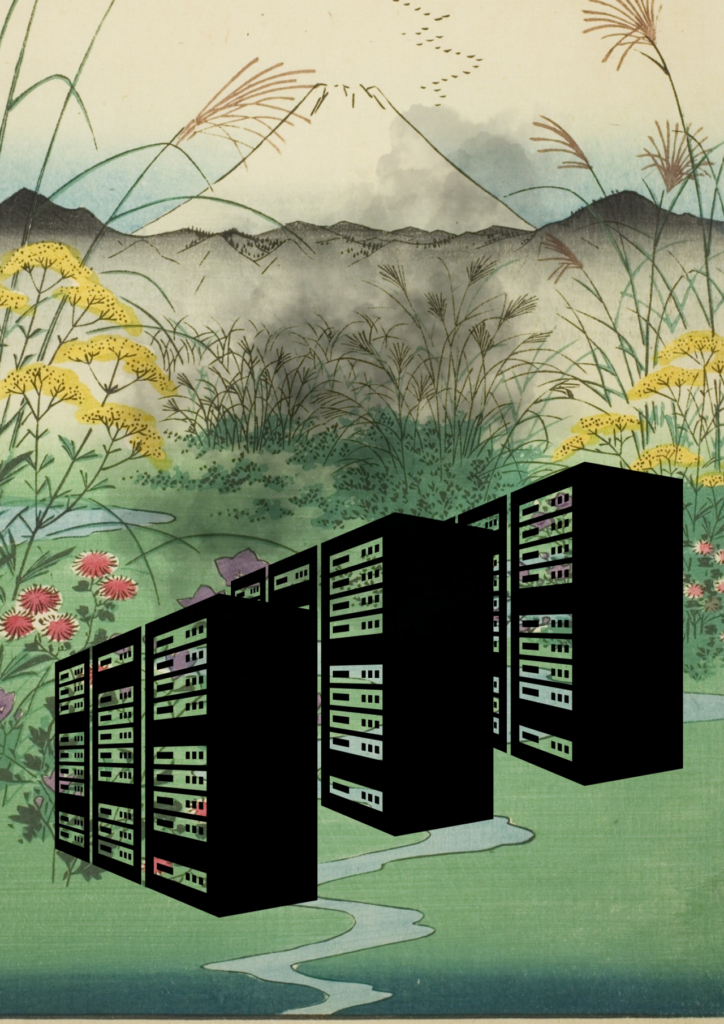
This image is a collage with a colourful Japanese vintage landscape showing a mountain, hills, flowers and other plants and a small stream. There are 3 large black data servers placed in the bottom half of the image, with a cloud of black smoke emitting from them, partly obscuring the scenery.
Deborah Lupton / Better Images of AI / CC BY 4.0

Deborah Lupton’s image, ‘Servers in a Landscape ’, directly challenges the ‘glowing’ visuals of AI by representing AI as a dark cloud of smoke. The image demonstrates the impacts of data centres on the natural world through pollution emitted from the operation of the centres.

Brain dead and Brain alive.

The brain form itself has traditionally had a persuasive influence on public perception. Experimental work by McCabe and Castel (2008) argued that brain images played a role in public acceptance of neuroscience research. They argued that such images or scans of the brain provide a physical basis for abstract cognitive processes, appealing to people’s affinity for reductionist explanations of cognitive phenomena. Later work has complicated the strength of the “seductive brain image” effect (Michael et al,2013); the claim is not that brain images automatically convince people, but that they belong to a wider visual culture in which cognition seems more credible when it is made visible in the brain. Essentially, they aid communication by making the internal cognitive process seem visible and scientific. 

Dumit, in his account of brain scans and personhood, presents this notion in pop culture, showing that the AI brain is a borrowed form of scientific visual authority, where the brain, in a variety of pop culture , and has become synonymous with a modern Euromerican notion of personhood. He gives the example of brain scans being framed with simple labels like “normal,” “depressed,” or “healthy,” reducing visible types of people into individual brains. Moreover, he shows us how this imagery travels extensively from medical literature to pop culture, forming an important mediascape shaping narratives. Dumit’s (2004) ethnographic account reveals that brain scans and imagery do not travel across mediascapes alone; they carry with them culturally situated ideas of personhood. As they move through realms of journalism, medicine, film, and courts, they are important cultural lenses through which people interpret illness and identity. Therefore, the glowing blue brains take on elements of personhood and identity based on how brain images have been viewed across western mediascapes. 

Racine et al’s 2005  notion of ‘neurorealism’ is also useful here, where brain images can make mental phenomena appear more real by providing them a physical location. These interlinked narratives of personhood and the brain have been crystallised by Vidal and Ortega in their (2017) book ‘The Cerebral Subject’, arguing that increasingly there is a tendency for people to be visualised through their brains. In a sense, our physical health, our mental health, our ability, and even our relations are seen through this image of the brain; in other words, they argue we are increasingly being visualised as our brains, where the brain becomes a symbol of our agency, intelligence, identity and moral responsibility. 

In the context of AI imagery, the glowing blue brain borrows from what we can call ‘neurocultural authority’, appealing to ideas of personhood and intelligence, where the narrative moves beyond computation to potentially misleading tropes of consciousness. The use of the physical brain enables the viewer to visually locate the machine, giving it potential for cognition. While the glow lights the machine up, the brain form provides an important visual architecture for us to visualise this active cerebral process; here the explicit use of the brain form helps transform luminous computation into a potential digital mind. This elaborate multi-modal trope, hence, removes us from the harsh reality of labour and infrastructure, and instead posits an anthropomorphic myth of a computer that is alive.
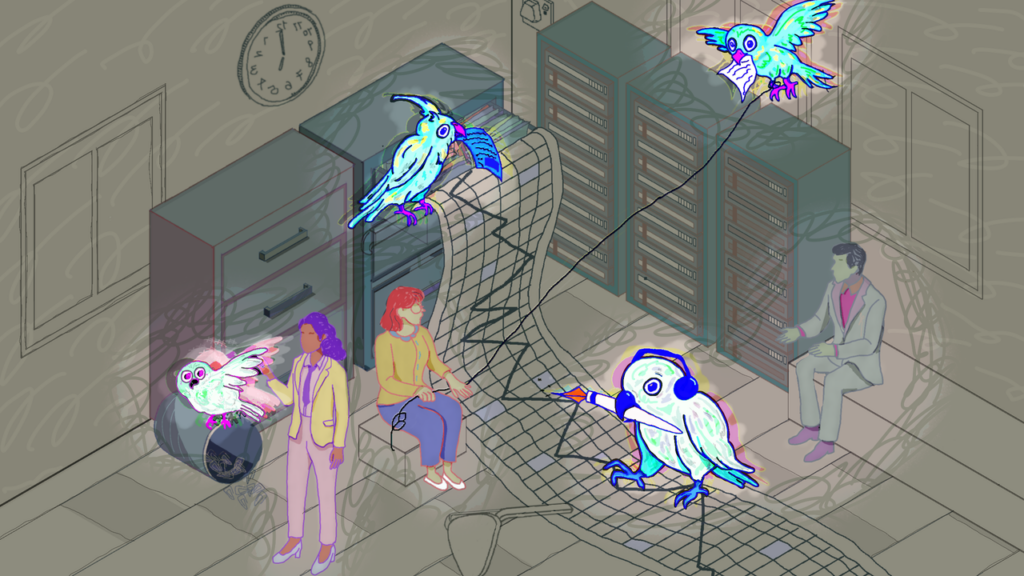
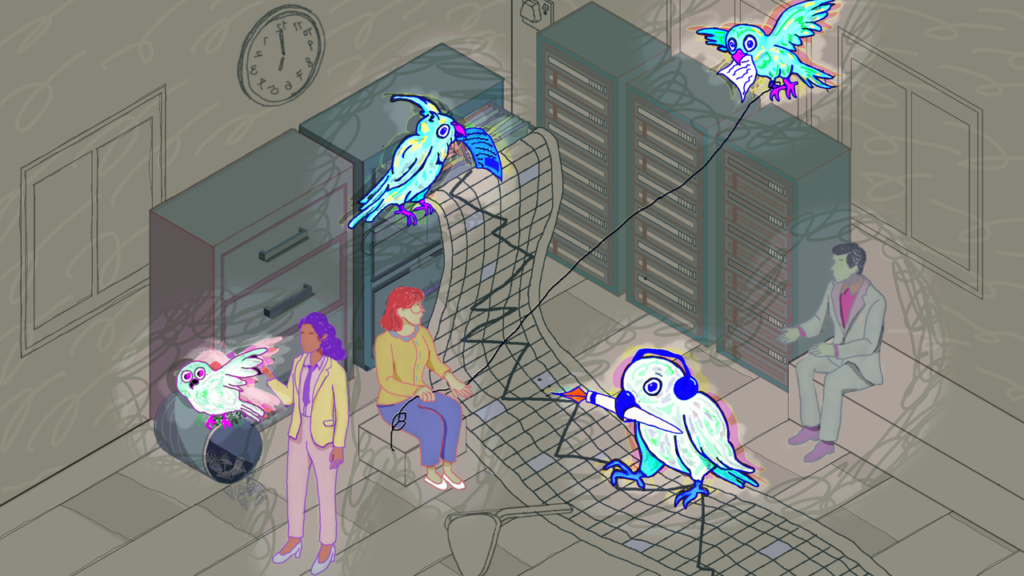
Illustration of a surreal office scene with neon birds interacting with digital elements around three people near servers and file cabinets; one bird writes on a digital mesh, another carries a paper.
IceMing & Digit / Better Images of AI / CC BY 4.0

Ice Ming’s image challenges the representation of AI as a brain through a different visual metaphor: stochastic parrots. The ‘stochastic parrot’ is a metaphor for large language models (like ChatGPT) that generate text by statistically predicting the next word based on large datasets, rather than by understanding the meaning, truth or context of the user’s prompts – perhaps like a cognitive being. 

Don’t Look so blue.

The use of the colour blue may seem a matter of ‘fitting the aesthetic’, given that such imagery is commonplace in science fiction cinema. However, the colour choice is an atmospheric device to make the visuals appear clean. Blue further helps remove AI from its socio-material context of data centres, energy use, supply chains, and labour. Sørensen and Thellefsen (2024) show that the role of colour in the blue brain metaphor is to ground the visuals in legitimacy. Crucially, this is not to claim that the use of blue, or the effect of blue, is universal, with Jonauskaite et al (2020) demonstrating that colour emotion associations are shaped by language, geography and culture, and this use of blue is perhaps limited to contemporary Euroamerican stock image culture, which has become the face of AI. 

This culturally situated use of the blue glow belongs to a wider regime in which AI imaginaries have been dominated by particular sections of society. This is connected to what Cave and Dihal (2020) have called the ‘whiteness of AI’, where the future seems Western and sanitised. The image further extends the erasure of other cultural and material ways of imagining AI; in a way, other ways to develop and conceive of AI  have been crowded out by such deterministic narratives. One can further draw a parallel to anthropologist Alex Taylor’s (2019) work on the aesthetics of data centres, where imagery used to depict data centres has emphasised them as sterile and technical spaces, devoid of fallible human labour. In both cases, visual narrative conveniently  distracts the viewer from human labour, which is at the core of the supply chain.
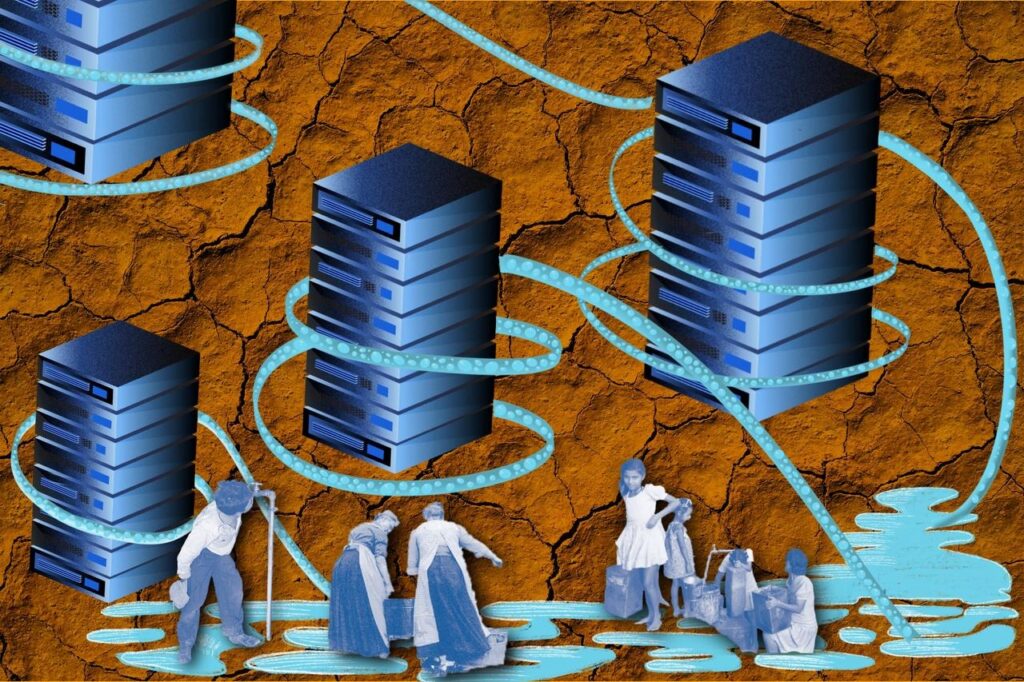
Cooling pipes hug data servers, extracting water from a shared reservoir while people collect water from the same source, set against a background of eroded soil textures.
Gloria Mendoza / Better Images of AI / CC BY 4.0

Gloria’s image, while still including elements of blue, is not used to represent AI, but the resources it relies upon – including water, local communities, and servers. It symbolises how data centre operations contribute to erosion, water scarcity, and drought.

Conclusion

The blue, the glow and the brain form combine to create a culturally situated myth of machine cognition. The myth has many layers: where a brain may provide it with physical authority, glow may suggest activation, and blue may signal a sanitised future in the Global North. This, when combined  with circuits placed upon a dark digital background, removes AI from physical infrastructure and human labour to a luminous future. This is symptomatic of visual media describing AI systems, which is disengaged from the social and environmental effects of such systems, while also perpetrating a grossly misleading narrative about the capabilities of current large language models.

About the author

Raghu Krishnan is an undergraduate reading archaeology and anthropology at the University of Oxford, interested in digital anthropology and human-AI interaction. 
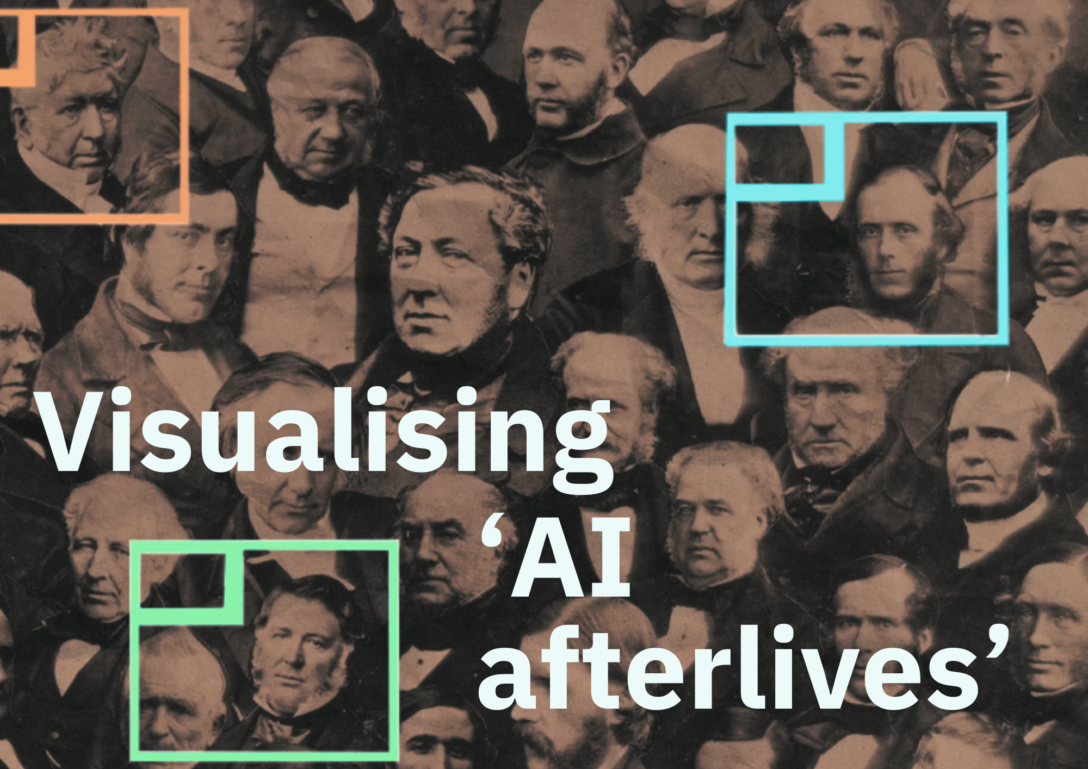
Visualising ‘AI afterlives’

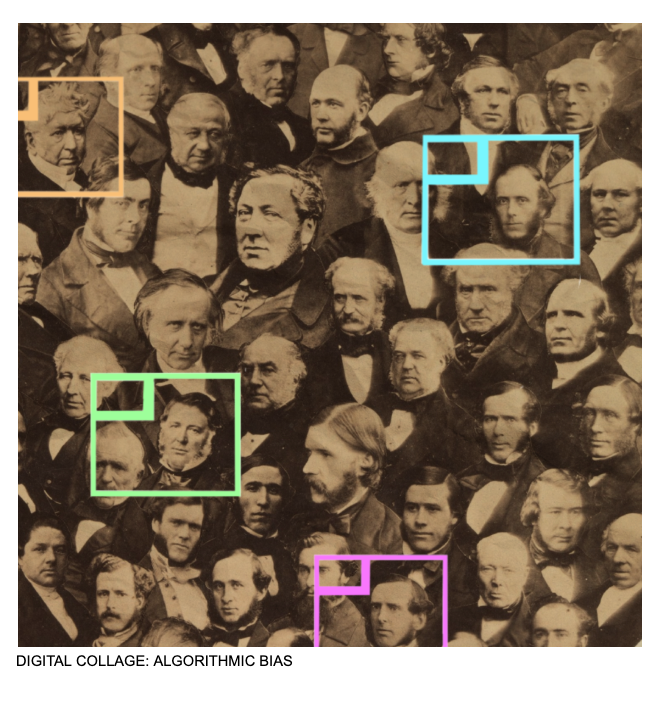
An archival, vintage-style image of a crowd of men. Three men's faces are signalled out by coloured bounding boxes. The text 'Visualising 'AI afterlives' overlays the image.

In this blog post, Jenny Kidd and Eva Nieto McAvoy from the Synthetic Pasts project share their own experiences of visualising their research outputs on ‘AI afterlives’. They comment on the need for better visuals to depict the use of generative AI in the digital afterlives and digital memory ‘industry’ (see here). Current stock images are suggestive of human continuance or immortality and represent death as a transition from body to data. To counter these visual tropes, they began using generative AI to create more helpful images, but later found that these images also raised challenges with respect to the way ‘past-ness’ was represented. Later, however, they turned to create their own visuals from archival materials, and while these still remain challenges, the process and outputs enabled more reflection and “encourage[d] us to notice the things that frictionless systems work to erase.” Some of the project’s visuals can be found on the Better Images of AI library, with a larger collection on their own site.

Since 2023, the Synthetic Pasts project has been exploring how AI is being used to animate, or re-animate, persons from the past through the creation of (for example) ‘deathbots’, avatars of historical characters, and voice clones of deceased artists. The project responds to the increasing use of such practices across a range of contexts, whether in museums and heritage sites, on stage and screen, or in our own personal archival and ancestral settings. It is clear that the creation of what we call ‘AI afterlives’ is becoming more mainstream.


The significance of visual tropes used for AI afterlives

One challenge for us as researchers has been how best to visualise our research interests when communicating about this work. Stock images of ‘digital afterlives’ and ‘digital memory’ are full of unhelpful tropes–glowing figures, ghostly spectres, and outstretched hands. These tropes echo those that the Better Images of AI initiative has catalogued so well. In the context of AI afterlives such ghostly spectres are suggestive of human continuance, or even immortality, as if these might be somehow facilitated through the use of AI. However, as we and others working in this area have shown, the ‘afterlife’ that is actually on offer through AI systems (in the ‘digital afterlife industry’) is more an infrastructural one—the survival of our data traces through commercial platforms—than a metaphysical one.

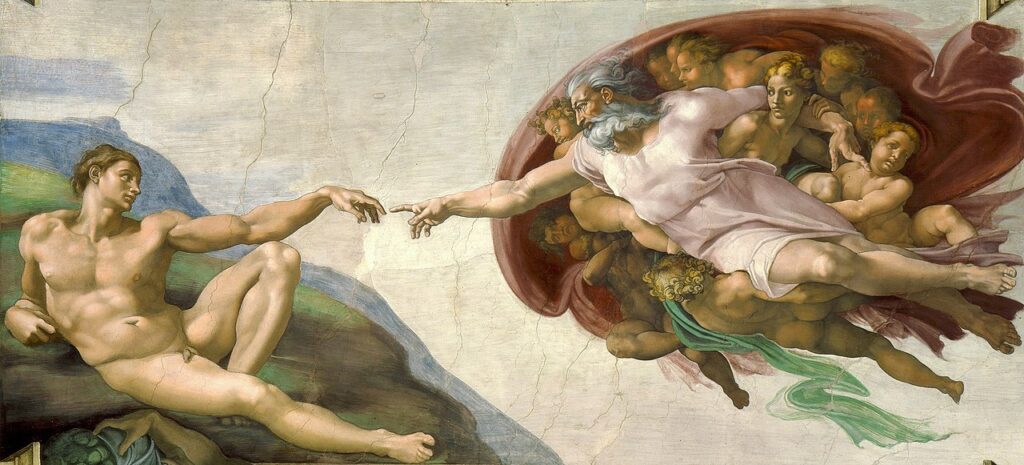
The depiction of glowing human figures, often with their hands outstretched, echoing Michelangelo’s Creation of Adam, is suggestive of human connections through time and into the afterlife and is in keeping with broader imaginaries of AI (see, for example, this depiction on the cover of a book about the digital afterlife). The gap separating the two hands, the images suggest, is to be closed by an AI that is capable of overcoming the human limitation and inconvenience of death. Other frequent depictions show spectral figures entering glowing digital portals that remind us of traditional imaginaries that present death not as an ending but as a transition into the afterlife, in this case, a seamless one from body to data. Such imaginaries are shaped by science fiction, and maintain that AI is uniquely placed to solve human problems; in this case, grief and loss.

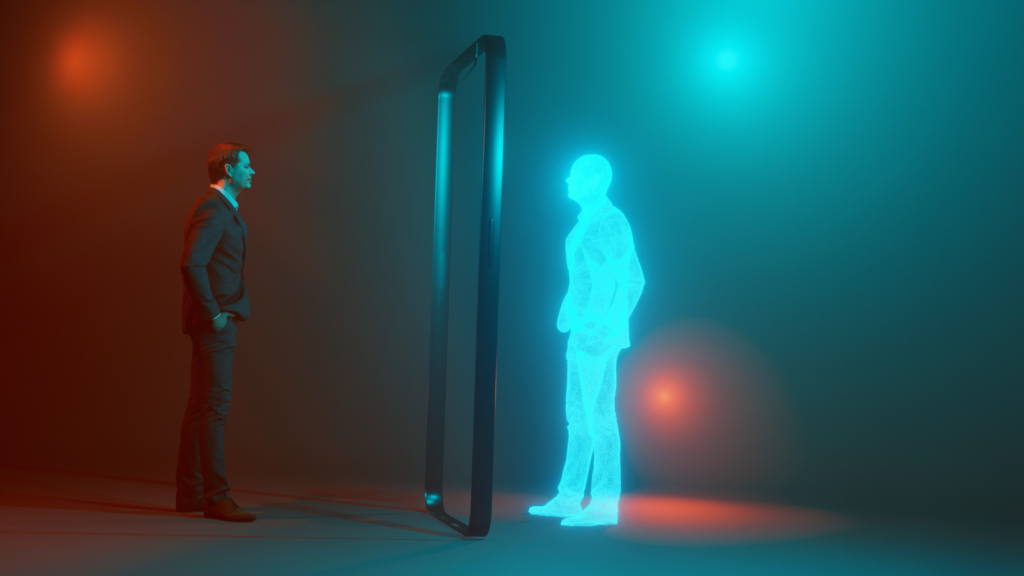
On the left is a man in a suit, he is looking into and facing a door frame and on the other side shows a mirror figure of him – but this time, it is a glowing blue hologram.
Image from HERE (credit: iStock Photo). An image of a person entering a portal with a glowing digital avatar on the other side.


Such visions of AI lose sight of the fact that endings—and forgetting—are important and healthy components of how human memory works. 

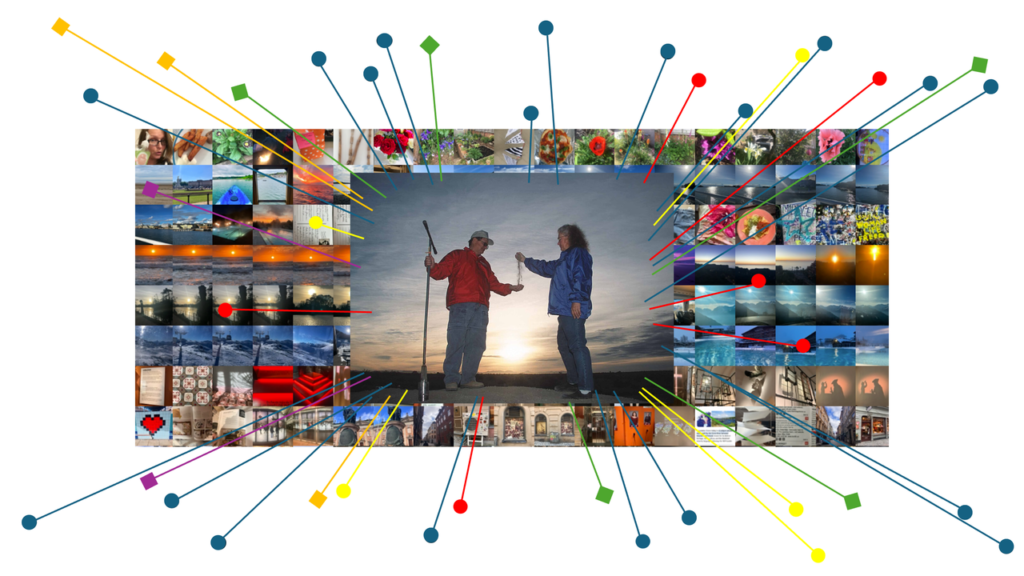
A library of photos. One photo has been highlighted by the system, and a series of  pointers suggest it has been marked as in some way meaningful by the archival and retrieval system.
One of the visuals that the Synthetic Pasts project created to reflect on the way that AI interacts with memory. Credit: Jenny Kidd & Synthetic Pasts / Better Images of AI / CC BY 4.0

AI-generated images of ‘AI afterlife’

At the start of our project, rather than use such images, we leaned heavily into generative AI imagery in order to try to communicate some of these concerns. At that time Dall-E3’s weirdness and the haunting images produced by Midjourney seemed to usefully make visible our discomfort about how AI might interact with memory. Images of people that never lived, depicted in incoherent places and with evident temporal (dis)locations, were suggestive of the ways memory too can distort and deceive, and of the complex entanglement between remembering and forgetting. Over time these AI-generated images became part of the visual language of our project.

Whilst we have been working on the project however, the pervasiveness and persistence of generative AI imagery has clearly increased. As synthetic media has filtered into social networks, advertising, politics, and even our communications with friends and loved ones, we have been talking more and more about the erosion of trust in images, including historical ones.

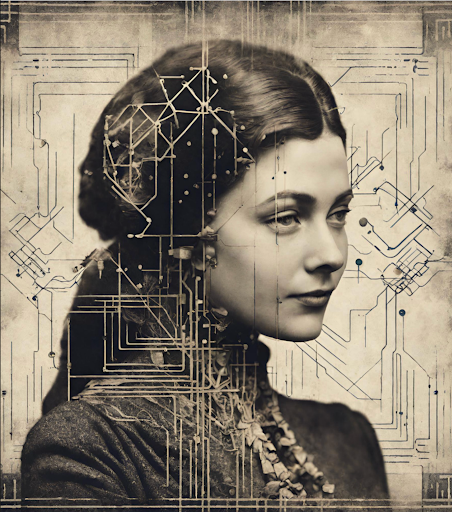
An image of the side profile of a woman in an old, vintage style. Overlayed the image is a series of circuit-style lines and network lines.
One of the AI-generated images created as part of the Synthetic Pasts project by Google’s Duet AI, 30 Nov 2023, prompt by JK

We have been troubled by the ways ‘past-ness’ has been aestheticised and hollowed out by generative AI systems.

In this context, that visual strangeness that once felt uncanny and helpful in the images we were producing has not aged well. Whereas we started using generative AI images to critique synthetic culture and the ethical challenges it presents – e.g., datafiction, exploitation, or bias – over time, our AI-generated images have themselves become a part of the problem. 

So in the closing months of our project we are finding new ways of trying to visualise how AI interacts with memory and impacts our understanding of the past. Some of our approaches are digital – making films and games for example, as can be seen on our project website – and others embrace more analogue and hybrid approaches – making zines, prints and collages. A few of the results can be seen on this page.

Working in this way slows us down, draws attention to memory’s affective and material qualities, and encourages us to notice the things that frictionless systems work to erase.

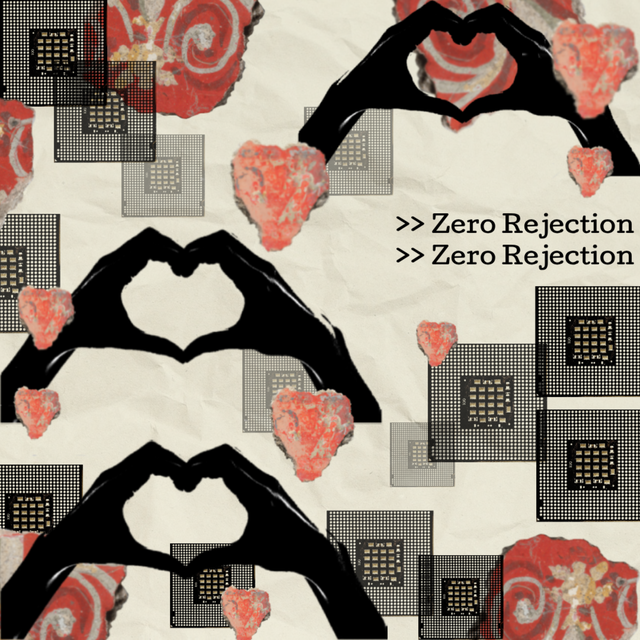
A repeated motif shows two hands coming together, where the fingers are shaped to suggest a heart. These are set amongst a series of images of small AI chips and red painted rocks which pick up on the motif of the heart. Repeated text on the right of the image reads ‘zero rejection’.

‘The intimacy factory 1′ is one of the images created for the Synthetic Pasts project. It reflects on the increasing use of ‘companion bots’; conversational bots designed to mimic human-like conversations. It references these systems’ synthetic and mechanical qualities, as well as their very real emotional impacts. These systems manufacture intimacy, creating the illusion of bi-directional attachment and even care. The image is compiled in Photopea and includes extracts from four public domain images.

Jenny Kidd & Synthetic Pasts / Better Images of AI / CC BY 4.0

You can find some of the visuals used in the Synthetic Pasts project in the Better Images of AI library; see the collection here.


From AI-generated images to archival images 

As a part of this more hands-on exploration, we have been making use of public domain imagery made freely available through online collections, archives, and libraries. This too raises interesting questions that we felt were productive for us at this stage of our project. 

Creating collages with archival material entails working with the traces of actual people and moments of the past. This might feel initially similar to what generative AI systems offer, just at a smaller scale. But focusing on individual photographs allows us to become more mindful of the specificity of their historical situatedness. Repurposing these in our work is not a straightforward or neutral process.

For example, the fact that an image is technically and legally available does not automatically make it ethically unproblematic. Such collections—like the AI images they have made possible as source materials—also reproduce multiple biases and inconsistencies. Our reuse of archival material still makes past persons visible for new purposes that are very different from those for which they were originally intended. 

The use of archival material forces us to confront questions about who gets to speak for the past and which stories get centred, as well as about consent and dignity. For us, the process of re-working makes these tensions visible, as the choices involved in representing the past become unavoidable. Through this approach archival contradictions and outliers are not glossed over by automated blending, and we are able to see how echoes of the archive reflect in generative AI imagery. As a result we can better advocate for more intentionality and scrutiny of these visions. 

“I like that this one is about repetition and homogeneity – this is the nature of archives anyway – and how these AI systems will hardly challenge these constructs with these datasets. Where are the gaps? The non-archived peoples and stories?”  – Dr Eva Nieto McAvoy

A greyscale, vintage-effect archival image of traditional men in a crowd. Coloured bounding boxes focus attention on 4 of the faces.

Better images of ‘AI afterlives’

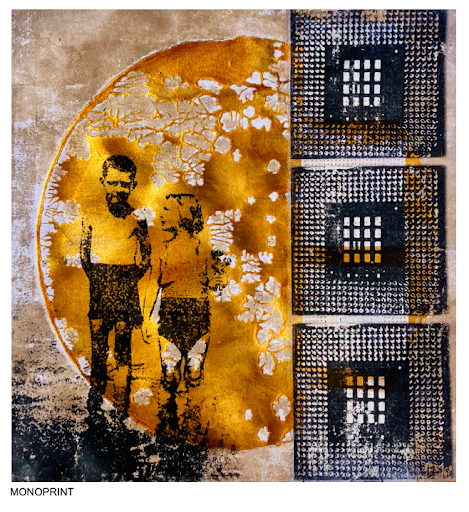
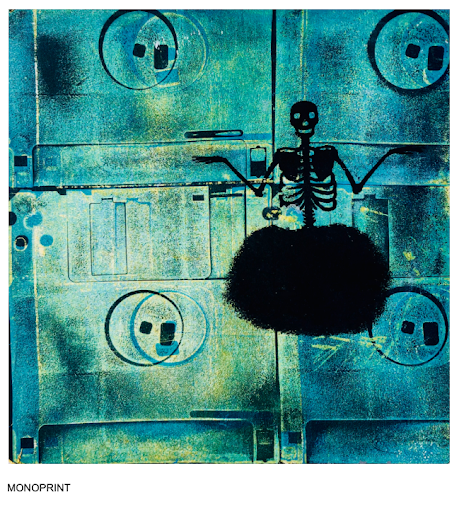
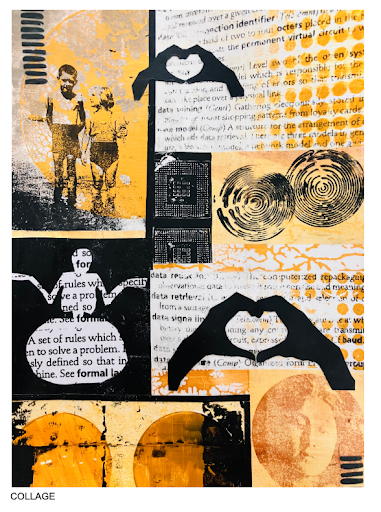
Below are some images created by the Synthetic Pasts researchers to visualise their work:

You can see more of the visuals created by the Synthetic Pasts project by scrolling to the bottom of their webpage.

About the authors

Jenny Kidd is a Reader in the School of Journalism, Media and Culture at Cardiff University and researches in the interdisciplinary fields of Digital Heritage and Digital Culture. She has led applied research projects with a range of practical and other outputs including two immersive experiences, a series of reports for policy makers and industry, and many publications. She is author of Museums in the New Mediascape (2014) and AI Afterlives: digital memory and synthetic pasts (2026). Jenny is Principal Investigator on the Leverhulme Trust-funded Synthetic Pasts project (2024-2026).

Dr. Eva Nieto McAvoy researches digital media and culture, with a focus on the theories and practices of new and interactive media in cultural and memory work at the intersection of knowledge, power, and technology. She has published widely and is co-lead on the Leverhulme Trust funded Synthetic Pasts project and co-author of AI Afterlives: digital memory and synthetic pasts (2026). 

About the Synthetic Pasts project

Synthetic Pasts is a critical-creative inquiry into what future(s) for personal and collective memory our algorithmic present anticipates and paves the way for. Funded by the Leverhulme Trust, the project explores how fragments from the past – photos or audio recordings of our deceased relatives for example – are remediated/animated through algorithmic systems, and with what consequences for how we remember and commemorate. The creation of unanticipated ‘afterlives’ in the present has ethical, emotional, and political dimensions, and it is crucial that we critically examine these unprecedented processes, as well as the socio-technical infrastructures and platforms that enable and encourage them (for example, genealogy sites, Amazon, OpenAI and Google). 

If you’re interested in Synthetic Pasts, you can explore some of their work below: 

Digital story, project overview: Eva Nieto McAvoy introduces the research context and key project concerns in a 5 minute digital story.

The Responsible AI Afterlives Workbook 

Kidd, J., Nieto McAvoy, E., Jones, B. and John, A. (2025). The Responsible AI Afterlives

Workbook: exploring AI to ‘revive’ museum collections and engage users. Synthetic

Pasts. https://doi.org/10.5281/zenodo.17619346 

AI Afterlives Digital Memory and Synthetic Pasts 

Kidd, J., & Nieto McAvoy, E. (2026). Bloomsbury [part of the Bloomsbury Studies in Digital Cultures series]. 

Synthetic afterlives: Deathbots as affective infrastructures of memory

Kidd, J., & Nieto McAvoy, E. (2025) in Memory, Mind and Media (4), doi:10.1017/mem.2025.10013 

Synthetic Heritage: Online platforms, deceptive genealogy and the ethics of algorithmically generated memory

Nieto McAvoy, E. & Kidd, J. (2024) in Memory, Mind and Media (3), doi:10.1017/mem.2024.10 

Deep Nostalgia: Remediated memory, algorithmic nostalgia and technological ambivalence

Kidd, J., & Nieto McAvoy, E. (2023) in Convergence, 29(3), 620-640. https://doi.org/10.1177/13548565221149839

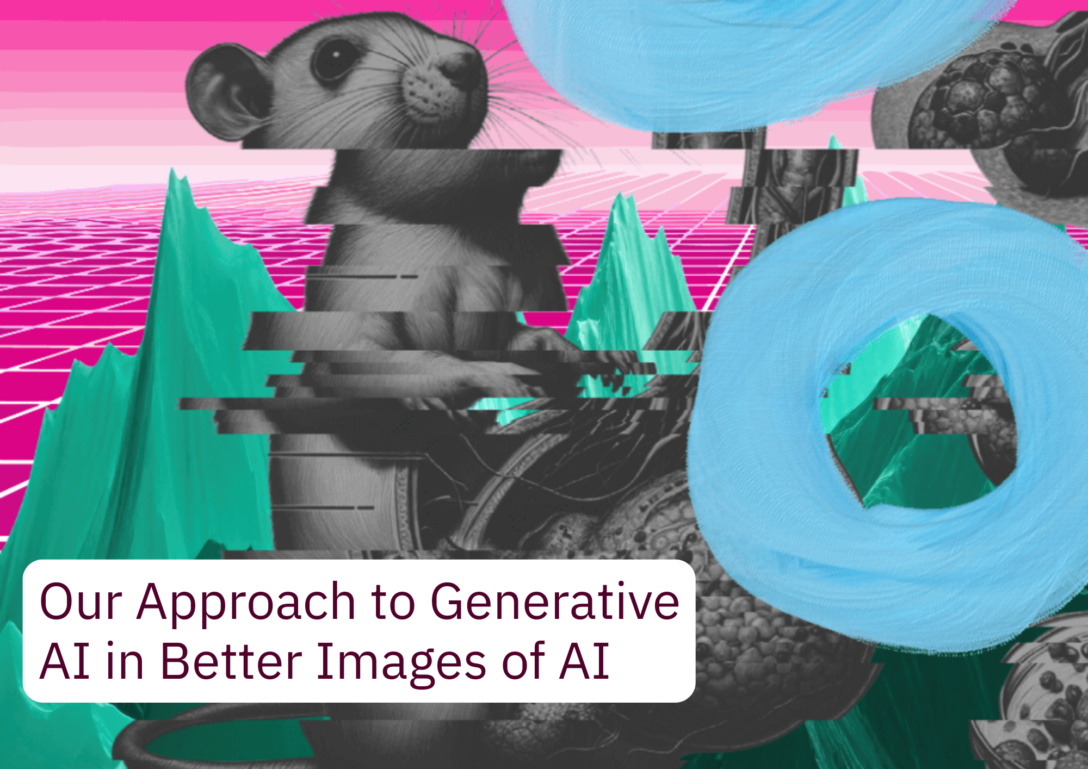
Our Approach to Generative AI in Better Images of AI 

On the left is a grey-scale version of a rat with inaccurate and oversized reproductive organs recognisable from an academic article which contained AI slop. The image has been edited to be sliced, and blue painted torus icons overlay the image. The background features a green mountainous range with a magenta tiled floor and gradient sky. Over the top, the text 'Our Approach to Generative AI in Better Images of AI' features in the left corner in a white text box.

Cover image credit: Marcin Wilkowski / Better Images of AI / CC BY 4.0

Claims about the productivity and efficiency gains from generative AI can be appealing to non-profit organisations, like ours, which have no core funding and rely completely on volunteers. Yet, at Better Images of AI, productivity and efficiency are not – and should not be – prioritised over other values like human creativity, care, learning, intention, empathy, connection, respect, equity, accessibility, and sustainability – all of which have brought us together as a community.

We and AI (the non-profit organisation that we sit cosily within) have played a significant role in challenging AI hype and offering a counter-narrative to extractive AI becoming inevitable in our lives (see resources here and here). We and AI’s work has prompted us to question and reflect on whether specific use cases for generative AI align with our organisational values. 

We have adopted our stance based on the reasoning outlined in detail below. These are not absolutes, or necessarily ‘anti-AI’, but at the moment, this approach reflects our prioritisation of practices which centre community values like care, intention, empathy, respect, equity, and sustainability – values which we do not see reflected in current AI development or practices.

The use of generative AI is also counterproductive to the purposes of our library and community, which not only aim to improve the visual representation of AI but also support creators, researchers, and individuals wanting to understand and learn about AI through imagery. Automating tasks, some of which may sometimes seem mundane or administrative, may speed up processes, but in turn, takes away from the time we spend attending to details and thinking intentionally, which can undermine opportunities for us to develop critical thinking skills about AI. 

We acknowledge that generative AI has been used by us in the past, for instance, when we were under the impression that Adobe Firefly was trained using consented materials (we later found out that it is not and revised our policies). However, in developing this approach, we’ve been able to learn from our creators and discussed how to embed our community values into our practices, which has ultimately led us to our current position. It is important to be honest, and we hope that in sharing this knowledge, we can be transparent about how – and why – we got here.

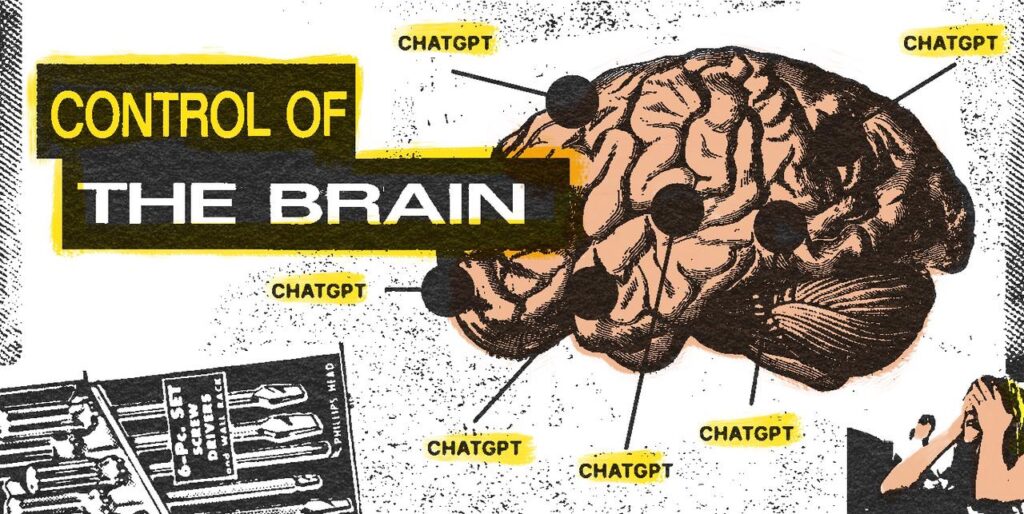
A brain diagram shows ChatGPT has replaced core functions of the brain, while a young girl in the bottom right covers her eyes in horror. Degraded imagery of screwdrivers and the words “Control of the Brain” frame the collage.
Bart Fish & Power Tools of AI / Better Images of AI / CC BY 4.0

Additionally, increasingly, we find ourselves in spaces where ‘AI-enabled’ productivity and efficiency in writing and art are prioritised and rewarded over the content of the work itself, with many being forced to ‘leverage AI’ in projects where it is simply unhelpful or useless – or worse, actively detrimental. We are holding space for practices which actively divest from unnecessary automation and exploitation, in favour of slower, community-focused, reciprocal alternatives which support our values and focus on the enjoyment that many individuals derive from creating, reflecting, editing, and writing.

We welcome any feedback on our approach to generative AI and hope that this policy is inclusive of all members of our community and partners, while also aligning with the values at the heart of Better Images of AI, which have been informed by We and AI’s research. This blog post serves as a living page, where we hope to continuously develop/clarify/iterate our approach based on community feedback. Some of the points raised in this approach, for instance, relating to ‘AI art’ and the use of artists’ work for training data, are being discussed actively by individuals – you may wish to follow and engage with their work (see here, here, here, here, and here as some examples).

Our approach is split into three main contexts for the uses of generative AI in accordance with Better Images of AI:

  • Image submissions;
  • Blog posts; and
  • Image cards (descriptions and alt text

For each use case or context, we outline reasons for our approach. However, for uses relating to our blog or images, we also challenge the motivations and reasons why you might want to use generative AI or assume that it is helpful. In these cases, we offer alternative non-generative AI approaches that better align with our values based on resources or existing practices that have organically, and sometimes accidentally, emerged within our community. We hope to build more resources along these lines.

As outlined in our Submission Handbook, AI-generated artworks are only eligible for submission to the library, if all of the following 3 criteria are met

  1. The image generator used to create the image: (i) uses only consented works in its training data, (ii) compensates artists whose works have been used in its training data, (iii) labels all images as AI-generated. 
  2. Original artwork by the submitting artist is used as the visual prompt and style. 
  3. The way the image generator has been used in the process is disclosed and described within the submission form. 

In practice, no generative AI image generators (that we are aware of) meet all three criteria. Therefore, images generated by models, including, but not limited to, DALLE-E, Midjourney, Stable Diffusion and Adobe Firefly are not accepted in our library. This may change, and if any AI image generators do comply with our criteria, we’d love to know. Techniques that use AI, which leave the original image intact and are not image generators, such as those found in digital editing platforms (e.g., background remove/eraser or basic filters), are permitted if they only ‘enhance’ the original image instead of transforming it (see our Submission Handbook for further explanation of how we’re thinking about the boundaries here). 

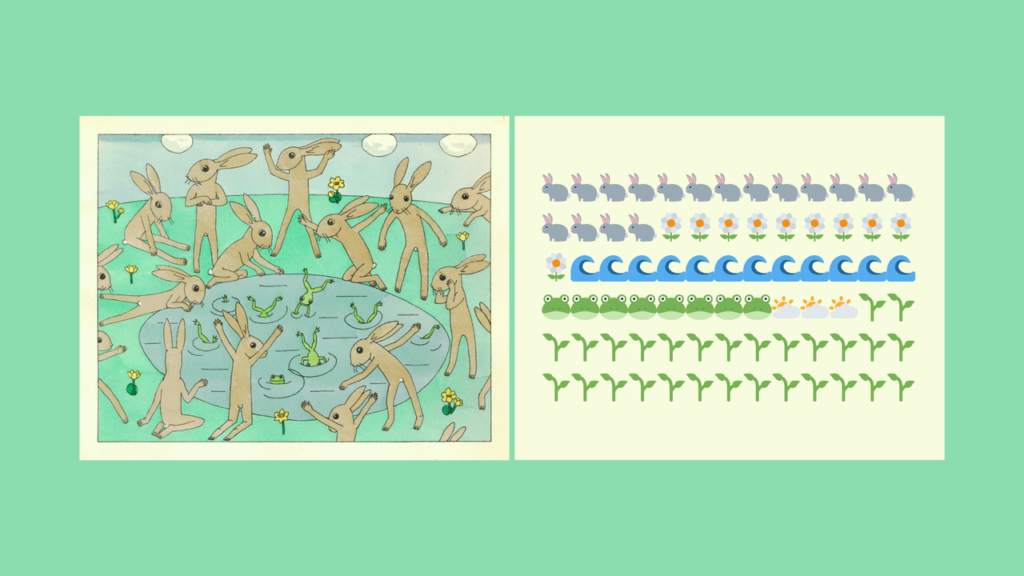
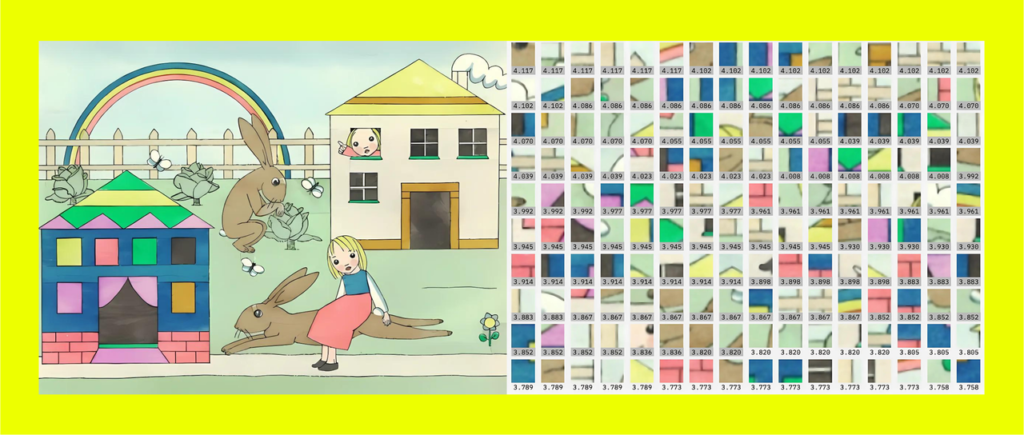
The collage features an artwork showing rabbits and frogs dancing around a pond on the left. On the right, this image is depicted in simplified, emoji-style symbols.
Dominika Čupková & Archival Images of AI + AIxDESIGN / Better Images of AI / CC BY 4.0

Alternative to using generative AI for images?

One reason you might consider using generative AI to create images is if you feel you do not have the artistic skill or ability to create an aesthetic, compelling visual. 

Generative AI visual outputs often reinforce biases reflected in our inequitable society. Using digital heritage collections offers a more reflective approach to challenge existing narratives and can prompt us to explore and understand how they are relevant to current AI developments and practices.

Furthermore, archival images can expose past histories from marginalised communities, which can allow us to understand how systems of oppression are embedded in the context of AI. However, it can also introduce alternative understandings and approaches to AI – showing us how the current practices are not universal, or inevitable, and alternatives have existed in the past or in different geographies. 

The Playbook also includes a list of public domain resources (an additional list is in our Submission Handbook too), which enable creators to explore how images outside of copyright protection can be used to create visuals for submission into our library. Although an ongoing legal question in courts around the world, generative AI text-to-image models can infringe copyright through the use of the input data to train models alongside the resulting output images.

There are numerous ethical and moral objections to using generative AI models for these reasons too, including the use of creators’ work without permission, consent or remuneration to train lucrative, proprietary models. Using public domain images, such as those found within digital heritage collections, can therefore offer a more legally compliant and ethical approach. 

While we want to hold space for all creators who wish to improve the visual representations of AI, we believe we can only enable the use of AI in this process if it has been developed in ways that respect creative communities (this requires consented training data, disclosure, and remuneration). We are also deeply concerned about the environmental impact of generative AI supply chains and therefore endorse human-created artworks which do not have the same detrimental impact on our ecosystems. 

In terms of content for our blog, we’re opposed to the use of AI for writing, ideation, research, grammar for many of the same reasons as we are for generating images, such as mass non-consensual use of authors’ work, biases and plagiarism, environmental factors, exploitation, as well as cognitive decline and integrity. We understand that common digital tools might have embedded AI-based features that are triggered without consent. We discourage collaborators from using these tools, for example, by disabling the AI overview on Google by adding ‘-ai’ to the end of your searches, or just by using alternative web browsers

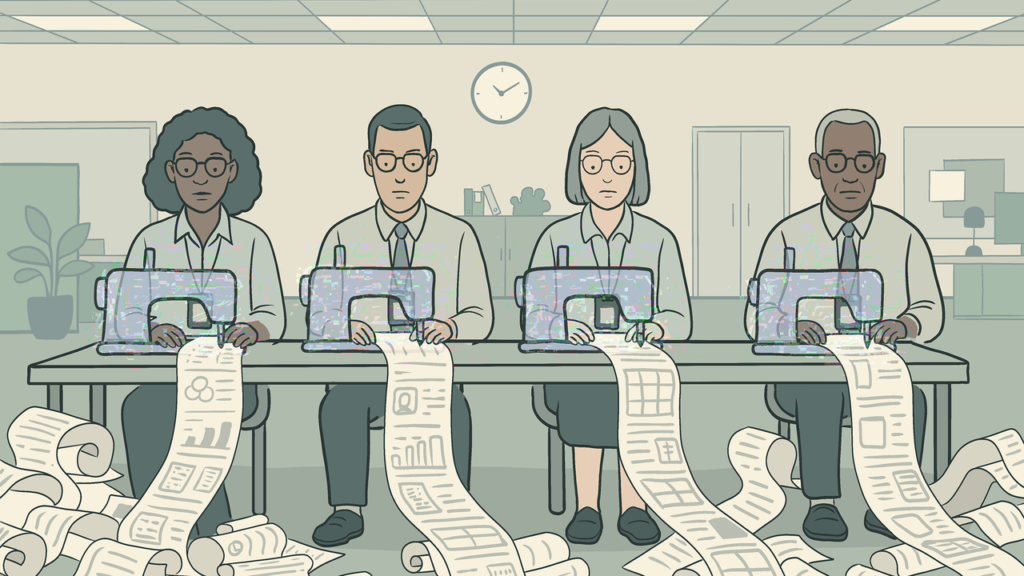
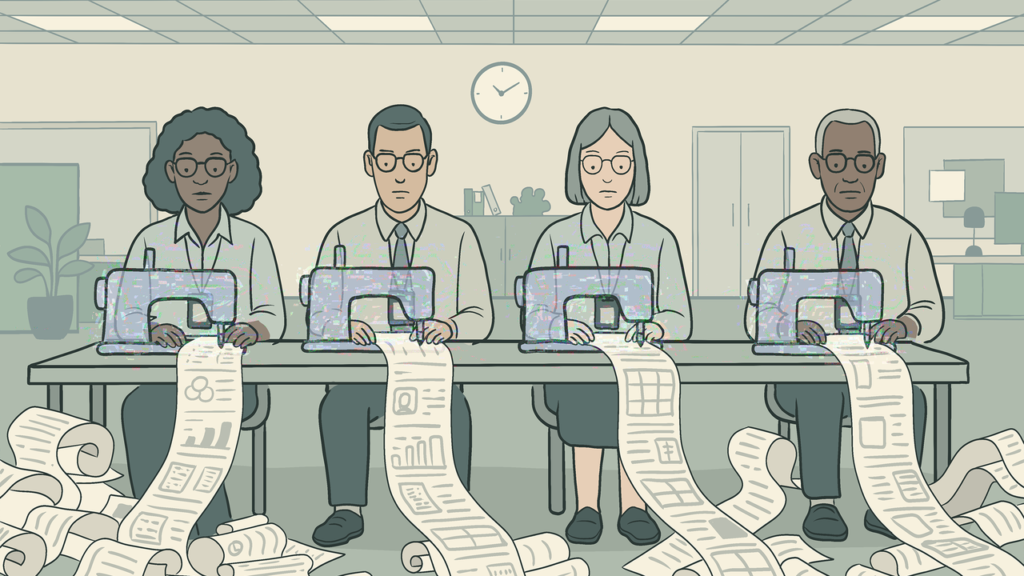
A row of knowledge workers operate sewing machines producing piles of spreadsheets and reports.
Leo Lau & Digit / Better Images of AI / CC BY 4.0

Alternative to using generative AI for images?

We understand that some people may use AI in the process of writing for other important reasons, such as for translation purposes. We do not wish to exclude these individuals from contributing to our blog and sharing their work with our community. 

We’re not incentivised or structured to benefit from fast, predictable, polished outputs. Instead, we value (often slower) options which can forge new human relations and offer mutual learning opportunities (even if we sometimes miss out a semi-colon, whoops!). If you’d like to use generative AI in some way to write a post for our blog, we’d love it if you can get in touch first and explain why you’re planning to use generative AI so we can learn more, understand, and see if we can help you.

Image descriptions: Since our creators do not use generative AI to create images for our library, we also believe that we should take the same consideration, time, and respect to write descriptions and alt text for the images. The process of doing so can enable us to explore the plurality of stories told by each image, while also learning and engaging with the creators’ intentions and understanding/experiences of AI.

Where we are uncertain about creative choices made or parts of the image, we can engage with the artist to learn about the image process and creation. This has the benefit of connecting our artist community with our volunteers, allowing for human connection and learning opportunities. 

We have found that AI-generated image descriptions do not effectively communicate the artist’s process, and so cannot prompt us to critically think about what is represented in an image. Writing image descriptions is also a learning opportunity for volunteers, particularly new ones, who want to learn more about how AI can be visually communicated in more accurate and representative ways. Contextual elements of images, such as those informed by an artist’s own experience or understanding of AI, can be replaced or lost by using AI-generated descriptions.

In addition, material processes involved in creating the images can be lost. We encourage creators to detail any specific choices, materials, and processes taken to visualise AI, showing how all representations of AI come from somewhere, influenced by worldviews, contexts, and geographies. Our community blog also develops these descriptions to explore in more depth the human stories, challenges, intentions, research, and organisations behind images (see here, here, and here, for example). 

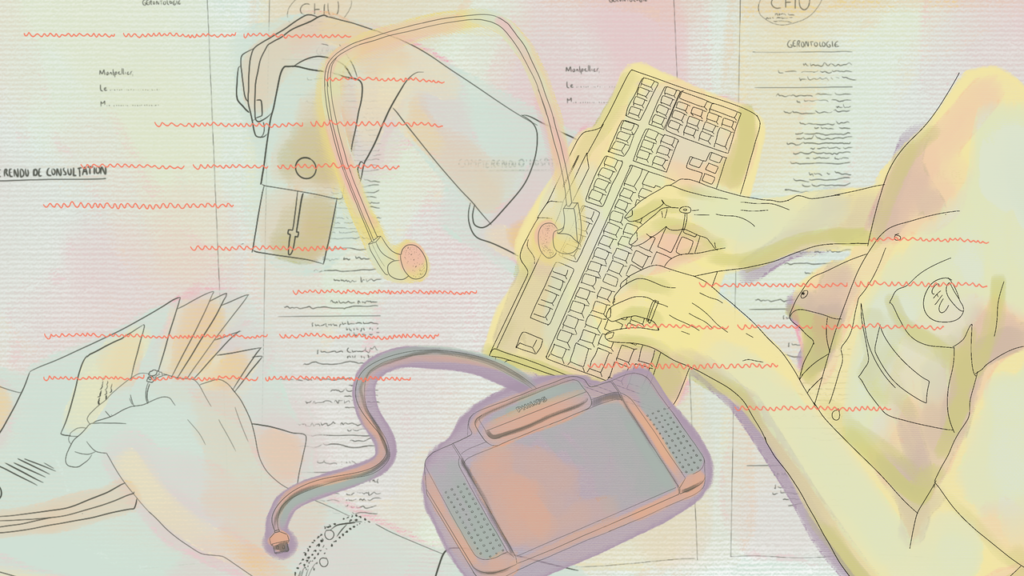
The image shows a superimposition of colourful illustrations representing different objects in a secretariat: in the background, printed minutes. Above, the hands of a medical secretary typing on her keyboard, the hands of another stamping envelopes. The headset and foot pedal in the foreground are essential tools for typing. In the foreground, the red zig-zags typical of ambient scribe errors streak across the image.
Fanny Maurel & Digit / Better Images of AI / CC BY 4.0

Alt text: For alt text, we also believe that preserving human-generated text increases the accessibility of our library for people who are blind or have low vision. AI-generated alt text descriptions of images may not communicate the specific choices an artist made or parts of an image necessary to understand the representation of AI portrayed in a certain image. This is particularly relevant for images which incorporate visual metaphors, whereby a literal description may not offer the same visual experience that other users are exposed to when using our library.

Being aware of how the image is presented and the context in which it sits can give people who are blind or have low vision a better experience using our library, which supports our purpose to increase public understanding of AI. Furthermore, we are cautious of uncritical uses of AI being used to ‘increase’ accessibility in a guise to minimise costs needed to invest in changing the ways the world is designed, which exclude individuals (e.g., people with disabilities), which cannot be simply overcome by technological approaches. 

Finally, as with writing descriptions, the process of writing alt text can be helpful for our volunteers to learn more about the visual communication of AI. Being able to describe images about AI often involves us undertaking research to understand the contents of the images and describe them in a way that communicates the same information from the description of an image as someone who relies on the visual experience.

While we do not currently have a resource that can help and guide creators or volunteers to write alt-text descriptions, we hope to be able to develop one in the near future, which is specific to our library and visualising AI. 


We have been reflecting upon the uses of generative AI for different purposes in Better Images of AI. However, when generative AI use cases are presented to us, we continuously come to the same question: 

“What can generative AI provide to Better Images of AI, aside from efficiency or productivity, that a community of care and collaboration cannot offer?” 

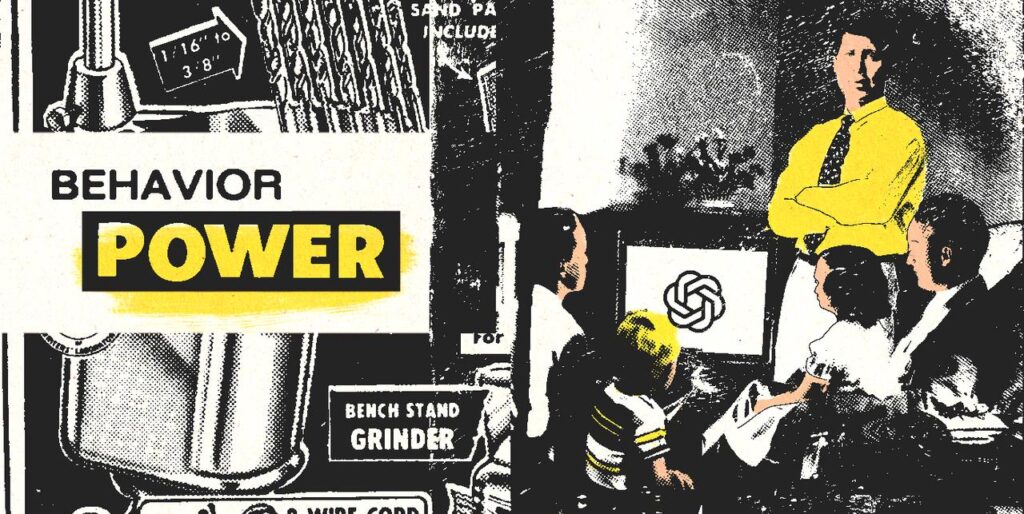
Sam Altman watches over a family consuming his AI. The living room vignette is framed by power tool imagery. The words “Behaviour Power” are the top of the artwork, framing the intent of the piece.
Bart Fish & Power Tools of AI / Better Images of AI / CC BY 4.0

As explored above, we have found that generative AI do not surpass the collaboration of our own community that we have developed around our values of care, learning, intention, empathy, human connection, respect, equity, accessibility, and sustainability – even if our work might be slower and not as ‘polished’.

But we genuinely welcome other people’s responses, which critique, build upon, or support our approach to generative AI in the Better Images of AI library. We exist to improve the visual representation of AI, and as part of this, we have thought about whether generative AI can play a useful role in supporting our mission. At present, we think that generative AI, as it is currently built and developed, does not.

Resources that inspired our approach

Below is a list of resources that influenced our thinking and approach. We welcome any suggestions for additional readings to add:


Everything, Eco-where, AI at Once?

A group of five cloud shapes float across a blue background. The clouds are collages made out of close up photographs of shiny silver silicon surfaces. Beneath, the text, 'Everything, Ecowhere, AI at Once?' is printed in light text.

In this blog post, Laura Martinez Agudelo builds upon her research of visual representations of ecology and digitalisation to explore how ‘AI eco-imagery’ is portrayed. Martinez Agudelo introduces five ‘eco-digital’ visual narratives from her recent paper – including the Earth as a glowing orb and nature through screens. She then explores how AI tropes are specifically embedded in ‘eco-images’, such as through green descending code and mechanical trees. She argues that these images shape our perception of AI, environmental issues, and their potential consequences.


Eco-digital narratives are a lens through which we imagine our relationship with the environment and technology. Visual storytelling plays a huge role in shaping how natural environments and sustainability are perceived and digitally represented. These narratives show how meaning is created and allows us to understand the ways visual communication defines the intersection between both topics.

The original article (written in French) ‘Eco-digital narratives and mediated visual representations’ (Martinez Agudelo, 2025) offers a semiotic, discursive and techno-visual reflection on these narratives in online communication. The study is based on the analysis and conceptualisation of an online corpus of 100 images from Google, Yahoo, Ecosia, Bing, Lilo, Qwant and DuckDuckGo search engine results. It describes the modalities of meaning found, as well as the indices of practices and materialities represented in visual discourses dealing with ‘eco-digital’ narratives.

For studying these thematised visual representations, we should look at both the content of images and the social practices they represent. As Descola (2021) puts it, ‘we only depict what we perceive or imagine’. In the context of digital technology, this often involves depicting specific technical devices, such as phones or computers. In ecology or environmental issues, the colour green is commonly used to represent visually natural environments. 

These narratives are everywhere online, from institutional websites and social media visual identity to online (green tech) guides and e-book covers. Certain visual patterns recur, each conveying a specific story about the intersection between ‘nature’, ‘ecology’, ‘environment’ and (new) technologies. The analysis provided some insights into how we perceive and communicate sustainability. Martinez Agudelo categorises eco-digital narratives into five types, summarised below: 

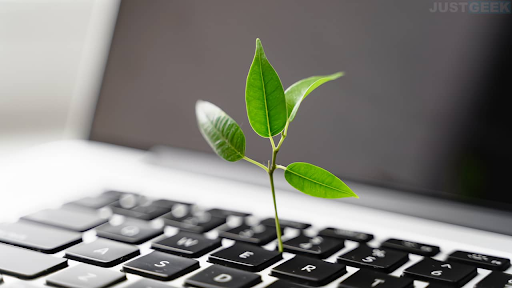
1. Plants growing from technological devices 

A small green leafy plant sprouting from a laptop keyboard.

One of the first patterns identified was how often plants appear intertwined with technological devices. A seedling sprouting from a laptop keyboard, a tree emerging from a smartphone screen… These images immediately convey the hopeful idea that nature and technology coexist in harmony. However, these visuals made us question whether they oversimplify reality. They can create the false impression that technology and nature integrate seamlessly without conflict or environmental cost.

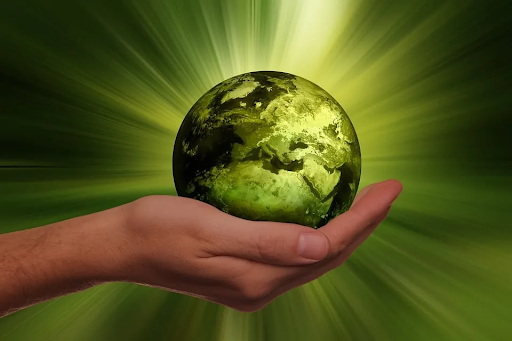
2. The Earth as a glowing orb

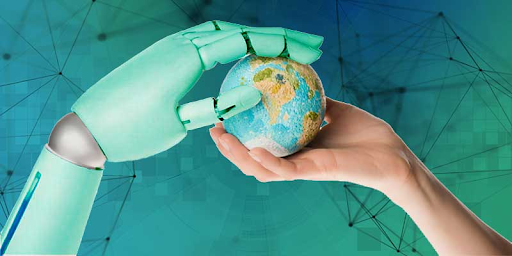
The Earth often appears as a glowing orb, sphere or marble cradled in human hands or glowing inside a lightbulb, a visual shorthand for ‘innovation’. But while holding the world in one’s hands feels empowering (for whom, exactly?), and sometimes it performs a gesture of care, it’s also misleading. Such imagery tends to sanitise the climate crisis, presenting it as something neat, homogeneous and manageable while airbrushing the messy, sometimes violent, and complex reality of the challenges we face (conflict minerals, e-waste dumping, rebound effect, cooling scarcity, subsea geopolitics, displacement…).   

On a green background, a the palm of a hand cups a green globe. God-like, holy radiance emanates from the globe through a glowing effect.

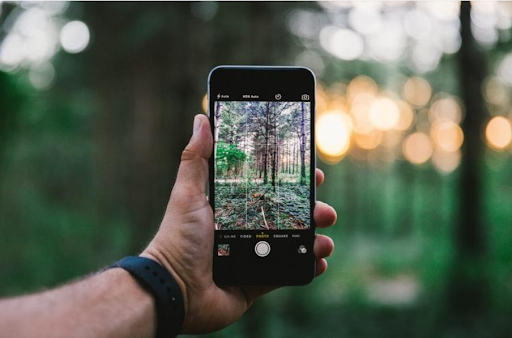
3. Nature through screens

A point-of-view shot of a person holding a phone. The camera is capturing an image of a tree in a forest. A sunset forest is blurred in the background.

In some images, nature is framed by tech devices: a forest captured on a phone camera, a waterfall displayed on a laptop screen. These visuals can make us reflect on our own experience. How often do we experience ‘nature’ through technology rather than directly? Are we connecting with natural environments, or simply consuming a curated digital version of it? How is this ‘nature’ already present or recognizable in the materiality of our technological devices?

4. Eco-tech icons

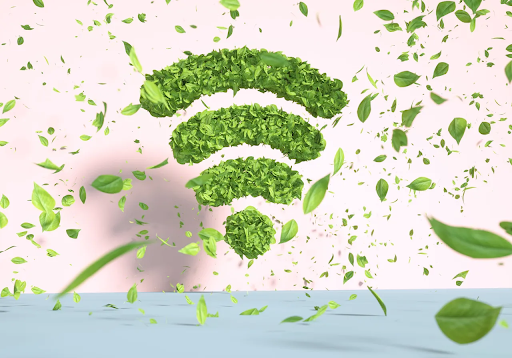
Then there’s the category of icons: green power buttons, recycling symbols, Wi-Fi signals entwined with leaves. These symbols are instantly recognizable and easy to understand. They communicate ‘eco-friendliness’ at a glance. However, many of them simplify or obscure the real impact of technology on the environment. They create a comforting (sometimes green washing) narrative, without addressing material realities like e-waste, water and energy consumption, or resource extraction.

A wifi symbol is in a green grassy texture, leaves fall around the symbol like confetti. The background is a light pink wall and baby blue floor.

5. Critical frames

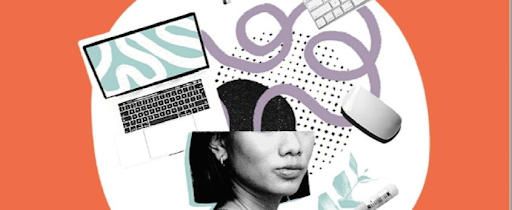
An orange background with a mixture of back and white photography. A picture of an individual's head is cut off with a purple swirl entering her head. A laptop is also positioned near her head alongside the corner of a keyboard and mouse.

A smaller subset of analysed visuals challenges or questions the mainstream eco-digital narrative in some way, by highlighting labour and resource extraction, as well as the pitfalls of greenwashing. These images prompt us to pause and reflect, reminding us that visual storytelling is not always intended to provide comfort. Sometimes, its purpose is to urge us to confront what we would rather ignore or change our approach to a specific eco-digital issue. Recognising these dynamics helps us to identify the symbolic analogies that are currently present in the media landscape.

This analysis also highlights the inherent biases within the search engine results that were used to compile the visual corpus. However, it offers a framework for understanding how such visuals inhabit the online public sphere, facilitating the expression of diverse positions on contemporary socio-environmental contexts. Although most of the analysed images are not necessarily ‘anti-ethical’, they are often ‘anti-political’ (Romele, 2023): they reinforce a rigid divide between experts and non-experts, preventing public disagreement regarding AI development.

Images actively influence how we conceptualise technology, sustainability, and our own roles within the digital ecosystem. Whether they inspire hope, frame nature as a passive object, or challenge us to face the material consequences of innovation, they somehow dictate the boundaries of our ‘ecological imagination’. Wagener (2023) suggests that some ‘narrative frameworks’ can carry a ‘discursive anger’ that also provides a structure for the climate crisis.

What about ‘AI Eco-Imagery’?

The categories concerning the intersection of ‘ecology’ and ‘digital’ are almost identical when discussing the visual interaction between the semantic field of ecology and AI technologies. Misleading AI tropes persist, albeit with slight variations, such as the use of a green colour palette (green anthropomorphism, green robots or cyborgs, grass hands, mechanical green hands, mechanical trees and green descending code), alongside objects related to environmental issues, such as wind turbines, solar panels and backgrounds depicting urban pollution. There are even depictions of small waste-collecting or plant-seeder robots in a future where Earth has been abandoned as a trash-covered wasteland (as in WALL-E). 

Moving forward, we can engage with these images more critically: what story is this visual conveying? What is it concealing? If they are in dialogue with another image or text, what is their intrinsic relationship? ‘Eco-digital’ narratives, reproduced explicitly within environmental discourses of AI systems, illustrate the intersection of the technological and ecological spheres and perspectives. Frequently, these images reduce ecology to a mere aesthetic rather than a lived practice or experience, shaping our perception of environmental issues and their potential consequences.

Questioning media-driven visuals enables a deeper understanding of the socio-technical and environmental realities behind and within them. While some images can create a false sense of security, others can distance us from reflection or meaningful action. Paying closer attention to our relationship with the living world and the way technology and AI systems mediate these connections enables us to engage more intentionally with our immediate environmental realities.

Critical visual frameworks that confront the real tensions and conflicts between emerging technologies and ecological collapse are necessary. The Better Images of AI library provides more complex and socially aware visual representations of the entanglements between environmental discourse, social systems and the material infrastructures of devices and digital technologies.

Images from the Better Images of AI library: credits at the bottom of the page

Rather than reproducing the sanitised aesthetics of clean innovation, these images expose the extractive supply chains, energy demands, labour conditions, exploitation and destruction that occur in the name of AI innovation, as well as all the planetary costs embedded in AI systems and technological progress.

Looking closely at these visual narratives reminds us that how we see, imagine or represent the world influences how we resist, act or create in it.

About the author

Black and white headshot of Laura.

Laura Martinez Agudelo is a Teaching and Research Assistant at the University Marie & Louis Pasteur – ELLIADD Laboratory. She holds a PhD in Information and Communication Sciences. Her research interests include socio-technical devices and (digital) mediations in the city, visual methods and modes of transgression and memory in (urban) art.

Image credits:

Cover image: Tania Duarte and Catherine Breslin / Better Images of AI / CC BY 4.0

Images from the Better Images of AI library, from left to right:

References

Descola, P. (2021) Les formes du visible: une anthropologie de la figuration. Paris: Seuil.

Latour, B. (2004) Politiques de la nature: comment faire entrer les sciences en démocratie. Paris: La Découverte.

Martinez Agudelo, L. S. (2025) ‘Récits éco-numériques et représentations visuelles médiatisées’, Interfaces numériques, 14(2-3). DOI: https://doi.org/10.25965/interfaces-numeriques.5583 

Romele, A. (2023) ‘Images de l’intelligence artificielle: Un punctum cæcum dans l’éthique de l’IA’, in Sebbah, F-D. and Romele, A. (eds) Imaginaires technologiques. Paris: Presses universitaires de Paris Nanterre, pp. 142–164. DOI: https://doi.org/10.4000/13orf 

Wagener, A. (2023) Blablabla: en finir avec le bavardage climatique. Paris: Le Robert.

Visualising the Empire of AI with Gloria

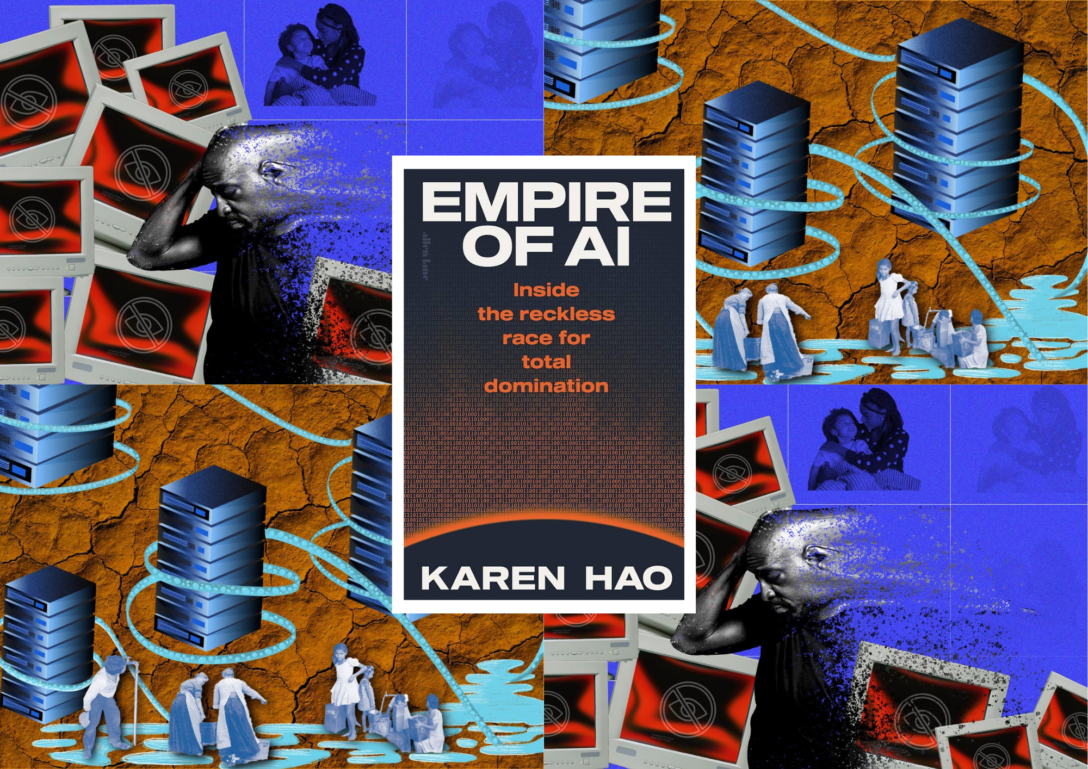
The image is split into 4 quadrants, which alternate 2 of Gloria's images. One of the images shows a man showing mental distress from constant exposure to harmful content online. His family, in the background, progressively disappears. The other image shows cooling pipes hug data servers, extracting water from a shared reservoir while people collect water from the same source, set against a background of eroded soil textures. In the middle of the 4 quadrants is the book cover of Karen Hao's 'Empires of AI'.

Gloria Mendoza’s images illustrate the hidden human and environmental forces which prop up the ‘Empire of AI’. After reading Karen Hao’s book, Gloria was inspired to visualise different chapters to communicate the ideas in an alternative medium. One of Gloria’s images focuses on the emotional toll faced by data workers in the Global South, inspired by a story in Chapter 2. The other image criticises the natural resources, particularly water, on which AI developments are dependent – this is also a topic discussed in depth in the book. In this blog post, we interview Gloria about her images, their inspiration, and the artistic choices made to depict technology and its impacts.

You can download Gloria’s images here in the library for free under a CC BY 4 license, so long as you correctly attribute.

“Over the years, I’ve found only one metaphor that encapsulates the nature of what these AI power players are: empires.” – Karen Hao


How did reading Empire of AI inspire your images? 

With respect to The Environmental Impact of Data Centres in Vulnerable Ecosystems, I was inspired by the book’s concise examples, something that’s hard to find when it comes to AI and automation (although see here and here). Before reading it, the environmental impacts of AI were somewhat blurry in my mind, but the book sparked my curiosity to explore how data centres are built—where they’re located, what equipment they use, how maintenance is done, and whether they can be sustainable in the long term. These questions inspired me to create this image using clear, minimal elements to illustrate the concerns I believe many people share.

The Invisible Labour Behind Content Moderation was inspired by Chapter 2 of Hao’s book. Hao tells the story of a Kenyan man who works as a content moderator and data labeller. Through constant exposure to violent and disturbing material, his mental health gradually deteriorates. Eventually, he reaches a point where he isolates himself from both his family and his community. This story reflects the reality faced by many data workers in the Global South. Several issues emerge in Hao’s account: unethical working conditions, unlawful labour practices, and the lack of adequate protection for workers.

For this illustration, I chose to narrow my focus to one aspect of this experience, the overwhelming emotional toll that this work can take. The collage aims to convey the isolation, distress, and psychological fatigue that many data workers endure. To reinforce this narrative, I incorporated hardware and digital iconography associated with sensitive content. These elements reference the technological systems that produce and circulate harmful content, while situating the worker within the broader infrastructure that makes this labor necessary.

How do you approach creating images that aim to represent AI more accurately and inclusively? 

The topic of AI often feels abstract and full of jargon, which is a major challenge for illustrators in the field. It tends to distance the public from its real-world meaning and impact. Through mixed-media collages, I found a way to shed light on what a single photograph could not capture. The tension between the organic feel of hand-drawn pixel graphics representing nature and the pixel-perfect precision of technology was carefully considered. This contrast became central to the piece.

Another challenge when visualizing these dynamics was how to represent people with dignity and accuracy. I evaluated line art versus photographs, both stock and archival, and ultimately my instincts drew me toward archival imagery. Stock photos, in this context, didn’t feel connected to the real people behind the issue. It was also important to avoid harmful tropes, such as depictions of African children collecting water, since the water shortages mentioned in the book were specific to the United States. Archival photographs, with their journalistic quality, convey a sense of authenticity and create a compelling contrast when placed alongside modern technological artefacts.

While searching for reference images of Kenyans, the results were men in tribal attire, sporting hip hop style fashion, showing off jewellery, or in extremely precarious conditions. These are representations that exacerbate negative stereotypes and narratives around Kenyans and Africans at large and do not represent the majority of the population. To tackle these results, I aim to provide as much context as possible and represent communities as accurately as possible.  

How do you think visual art can influence public understanding and perception of AI? 

Visual storytelling can help surface these hidden realities and remind us that tech infrastructures are sustained not only by code and data, but by human labour and ecosystems – Gloria Mendoza

Visual art can help the public understand this topic because creativity and conceptual thinking are powerful tools artists use to make complex ideas accessible, legible, and thought-provoking. We are living in a decisive moment where debate and action are imperative, and art helps bridge the gap between concepts that civil society may not be fully literate in and the processes of decision-making. It is important that these ideas are understood and discussed by all of us—not just technology designers and policymakers.

Illustration can make complex tech ecosystems visible. Behind datasets, algorithms, and automated systems are workers and natural environments that sustain these infrastructures. By carefully considering representation, symbolism, and context, visual storytelling can help surface these hidden realities and remind us that tech infrastructures are sustained not only by code and data, but by human labour and ecosystems.

Could you describe the visual metaphors employed in your image(s)?

Stylistically in The Invisible Labour Behind Content Moderation, I chose distortion as the primary visual metaphor. Distortion can powerfully illustrate the damage that systemic forces inflict on individuals. It suggests the breakdown of stability; a once solid subject gradually losing control, becoming increasingly vulnerable and disoriented.

What kind of images do you envision for the future representation of AI? 

I envision images that center the human experience in relation to technology; works that are explicit, relevant, and grounded in research. Representations of AI can take many tones: critical, informative, enraging, or saddening, and these are approaches artists can continue to explore while keeping their concepts rooted in figurative representation.

How has contributing to the Better Images of AI library influenced your own views on AI and its impacts? 

In the end, this project became more than just an illustration; it was a way of thinking about how technology, humanity, and ecology intersect, and how images can make invisible systems visible, sparking reflection, curiosity, and awareness.

About the artist and author

Headshot of Gloria.

Gloria Mendoza is a Colombian-American artist and designer dedicated to using visual storytelling to spark conversations around social issues and societal challenges. With a background in art direction, brand identity, and illustration, she creates research-based imagery that bridges the gap between data and public understanding. Her work invites critical thinking about equity, inclusion, and accessibility.

Cover images: Gloria Mendoza / Better Images of AI / CC BY 4.0 + book cover of Empire of AI by Karen Hao

This post is an updated version of one previously uploaded in 2025.

Localising AI’s Visual Culture with Brussels Heritage

Paper collage. The Art Deco swimming pool of the Villa Empain in Brussels, its elegant facade visible in the background, with the water replaced by rows of computer servers.

Images spread across tables, sheets pinned to walls, scissors and glue sticks everywhere. An incongruous setting for people who work in tech, more used to tapping keyboards than wrestling with rolls of tape. And yet… this was the best response FARI found to a problem that’s harder to pin down than it seems: the depressing homogeneity of AI imagery that fails to capture individuals’ own experiences and encounters with the technology in local communities.

FARI – AI for the Common Good Institute is a Brussels-based research institute bringing together over 300 researchers in artificial intelligence, robotics and digital data. In February, FARI hosted a workshop on “Localising Visuals of AI” – aiming to engage its group to create visuals of AI anchored in the lived realities of a citizen in Brussels. 

In this blog post, Ulysse Gerkens, who led the workshop, explains why localised visuals of AI are important and necessary. In particular, how drawing upon digital commons and an individual’s own materials can create conditions for sensitivity and lived expertise to translate into visualisations of AI. Ulysse also offers some tips and advice for hosting your own “Localising Visuals of AI” workshop in your local community. 

You can find some of the images from the workshop in our library here.

“We don’t localise AI to promote it; we localise it because it’s already here. By cutting out images of bus stops or Brussels facades, participants made visible what standard AI imagery erases: the presence of these technologies in our daily lives.” Ulysse Gerkens

AI images mislead us

The mission of digital mediators goes beyond facilitating access to technology. It also involves reflection: inviting every citizen to question the technologies that run through their daily lives, to form their own opinion, to voice it. It’s a deeply democratic mission, and one that echoes FARI’s reason for being. When the only available images of AI are misleading, it is precisely this capacity for expression and critical judgment that is weakened. Driven by this mission and this assessment, we chose to host a workshop based on Better Images of AI. More than a library of alternative images, Better Images of AI addresses a challenge that digital mediators face every day: 

How do you explain the stochastic workings of language models with images of humanoid robots? How do you convey AI’s ecological impact when the only images show clean, shiny machines?

“The spectacle presents itself as a vast inaccessible reality that can never be questioned. Its sole message is: ‘What appears is good; what is good appears.‘”— Guy Debord [2]

Better Images of AI proposes to build a different visual vocabulary of AI. One that is useful, anchored in reality, and that can shift our gaze.

Appropriation as the goal, localisation as the method

Beyond these observations, we can’t rebuild the entire imaginary of AI in a single workshop. So, where to start? Perhaps with our immediate environment and our culture. “Localising AI” was our first starting premise. In a globalised culture, we proposed putting the human, with all their specificity, back at the centre of the debate. So we decided to anchor AI imagery in Brussels, drawing from our experiences and encounters with the technology.

Tania Duarte, Founder of We and AI which runs the Better Images of AI collaboration, spoke at the workshop. She stressed a point we kept coming back to: we are all experts of our own ground. Digital mediators know their audiences, their neighbourhoods, and the concrete situations where AI enters people’s lives. The workshop aimed to turn this lived expertise into images.

An over the shoulder shot of an individual cutting with scissors at a table which is full of cuttings and images spread out.
Participant cutting during the workshop

What remained was finding a practical method. A human choice prevailed: collage.

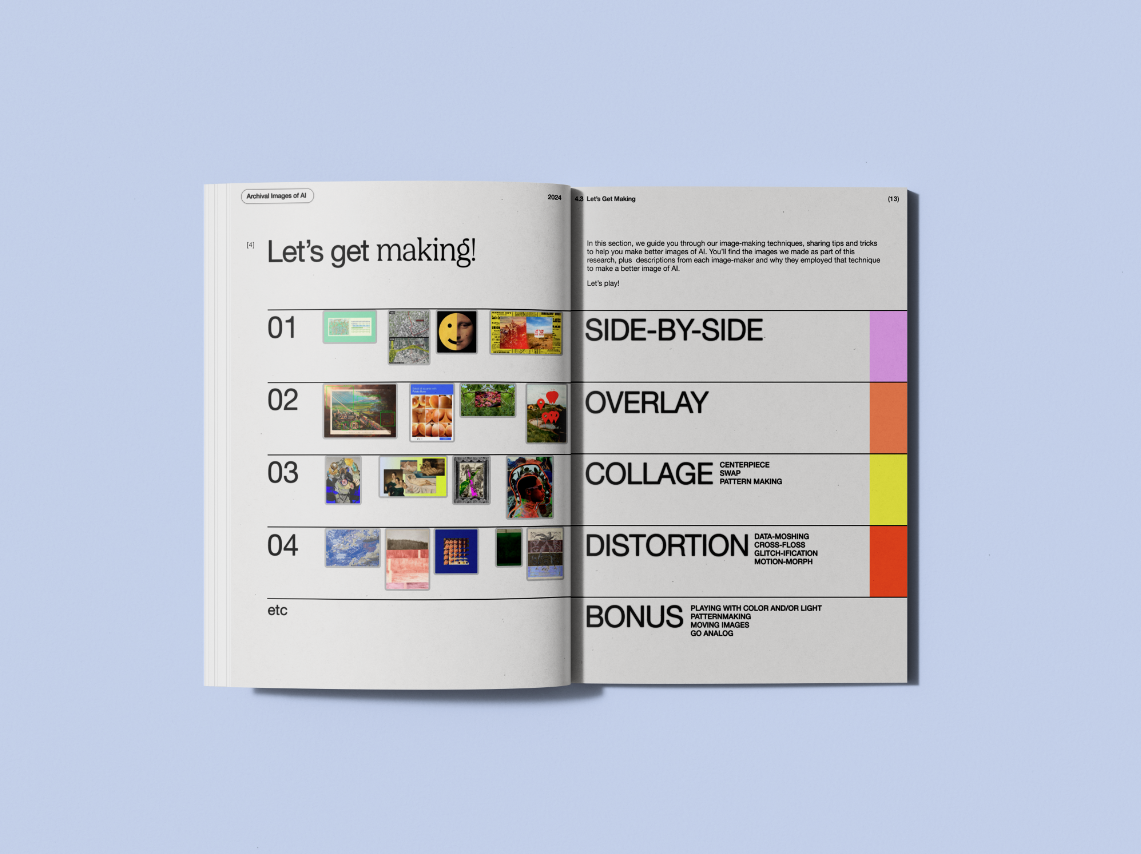
Initially, we had considered several techniques, including digital editing tools. The “Archival Images of AI” playbook by AIxDESIGN offers several interesting methods for creating alternative AI images from archival material. But it was a first testing session with the Citizen Engagement Hub team, Léa Rogliano and Alice Demaret, that gave us clarity. The cut-and-paste technique worked not only for creating strong images; it was also particularly inclusive: it encourages interaction through shared materials, is playful and immediately accessible. It met all our goals, so we made it our method of choice.

However, this technique came with a challenge: we needed to prepare enough pre-printed images and materials for the day. Once again, AIxDESIGN’s resources saved us. Thanks to their recommendations, I discovered Are.na, a platform for collecting large numbers of images from varied sources and formats. The platform describes itself as “ad-free, open source by default, to promote ethical design principles in the tech industry”.

A screenshot of the digital images in a library. Images shown range from AI company logos to parrots.
Are.na collections

You can find the collections created for this workshop here.

Gathering images was time-consuming, but fairly easy thanks to the links shared by AIxDESIGN. This resulted in three collections: archival images, images of Brussels and images of digital materiality. One problem persisted: the images of Brussels found online reflected very little of our actual environment. I mostly found images of the historic tourist centre, along with well-known cultural symbols. Missing were all those subtler elements that make you recognise your city. Léa Rogliano (Head of Citizen Engagement Hub) proposed an original solution: invite participants to bring their own images and photographs.

One participant took up the challenge and prepared a series of street photographs: bus stops, screens, electric devices, and so on. Elements that AI could very well integrate… and a far cry from white humanoid robots. Their relevance surprised us, and on the day of the workshop, they turned out to be especially popular!

Far from Brussels’ tourist clichés: a simple bus stop. Here subverted with a fictional ChatGPT integration:

A bus stop with screenshots from ChatGPT's interface overlayed, including "How can I help you today" with the OpenAI logo above on the traffic light. "ChatGPT 3.5" is at the top of the list of stops, and "New chat" beneath "38 Helden" and "71 Delta" as an additional stop.
Bus stop with fictional ChatGPT integration

Scissors and glue

With the materials ready, another challenge emerged: How do you get people from very diverse backgrounds, who don’t consider themselves “creative”, to produce powerful images? How do you create the conditions for their sensitivity and expertise to translate into images?

Our approach was fairly direct. We prepared a presentation tracing the story behind Better Images of AI and what it seeks to build, with each concept illustrated by concrete examples. We also presented the collage techniques participants could use: cutting, layering, text collage, subverting existing images… The idea was for everyone to leave with a clear visual toolkit. Tania Duarte’s talk anchored this introduction: by putting a face to the project, she reminded participants that they had the opportunity to join an initiative that reaches beyond borders.

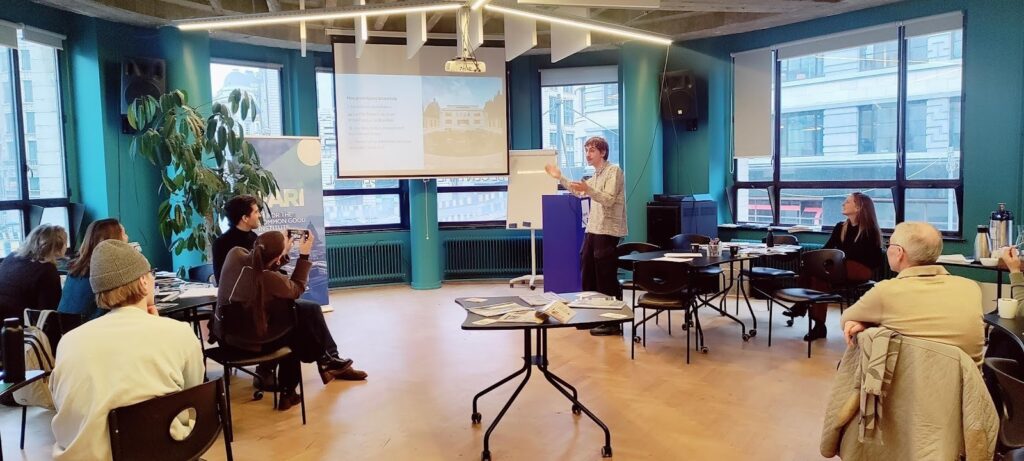
An image taken from the back of a room where individuals are sat around tables watching Ulysse present on a screen. The tables have materials such as papers and images scattered on them.
Workshop presentation

We then invited the group to create images that avoid these tropes, with no further instructions. The idea was that they could represent AI from every angle, positive and negative alike. But also, quite simply, to create images for illustration purposes, however abstract. Images that could stand on their aesthetic qualities alone, without necessarily carrying a critical message.

Insisting on this creative freedom put everyone at ease. The first round of creation naturally sparked conversation, which gradually steered the work towards more developed images. The setup, gathering around a table and sharing creative tools, was decisive in sparking exchanges.

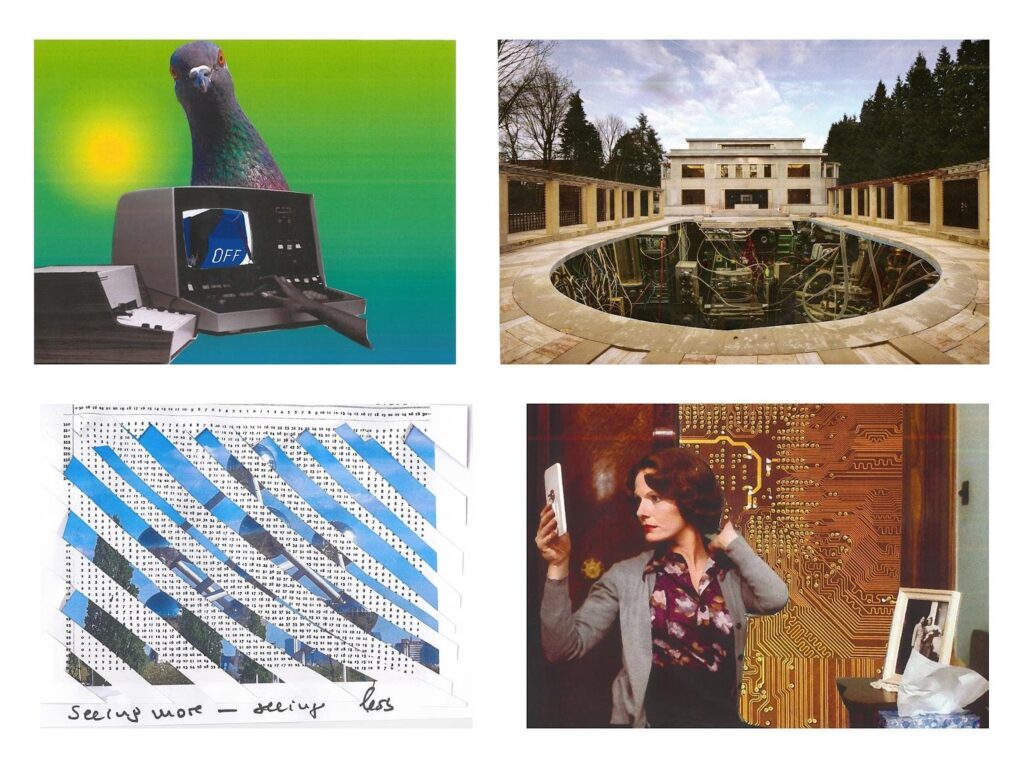
4 images from the workshop which are described below.

Among the creations, a few images are worth pausing on:

  • A Brussels pigeon presides over an old computer. The image doesn’t necessarily mean anything, but it makes people laugh, and that’s already a lot. 
  • More pointed, another creation repurposes the swimming pool of the Villa Empain, a Brussels contemporary art venue. The pool is drained of its water and filled with computer servers. The image exposes the colossal consumption of data centres, but also questions resource allocation: when budgets shift towards digital infrastructure, what’s left for culture? 
  • A third collage subtly weaves technology into a Chantal Akerman film. A woman looks at herself in a mirror that could also be a smartphone. Technology as an evocative backdrop. 
  • Finally, the collage “Seeing More — Seeing Less” depicts the Atomium, an iconic monument built for the 1958 World’s Fair, at a time when science promised a radiant future. The giant atom can also evoke neural networks, and here conceals a dataset.

From humour to critical reflection, these images show that using archives and local symbols makes it possible to create representations that are as striking as they are varied.

It should be said that we were fortunate to gather around the table a wide variety of professions: a digital inclusion coordinator, a data protection researcher, a learning designer, an artist, a communications officer at a cultural institution, a European Commission executive, and FARI’s own communications team. A mix that turned out to be a catalyst for creativity and exchange.

In just over an hour, everyone had time to produce several images. The first images unlock creativity; the ones that follow gain in intention and relevance.

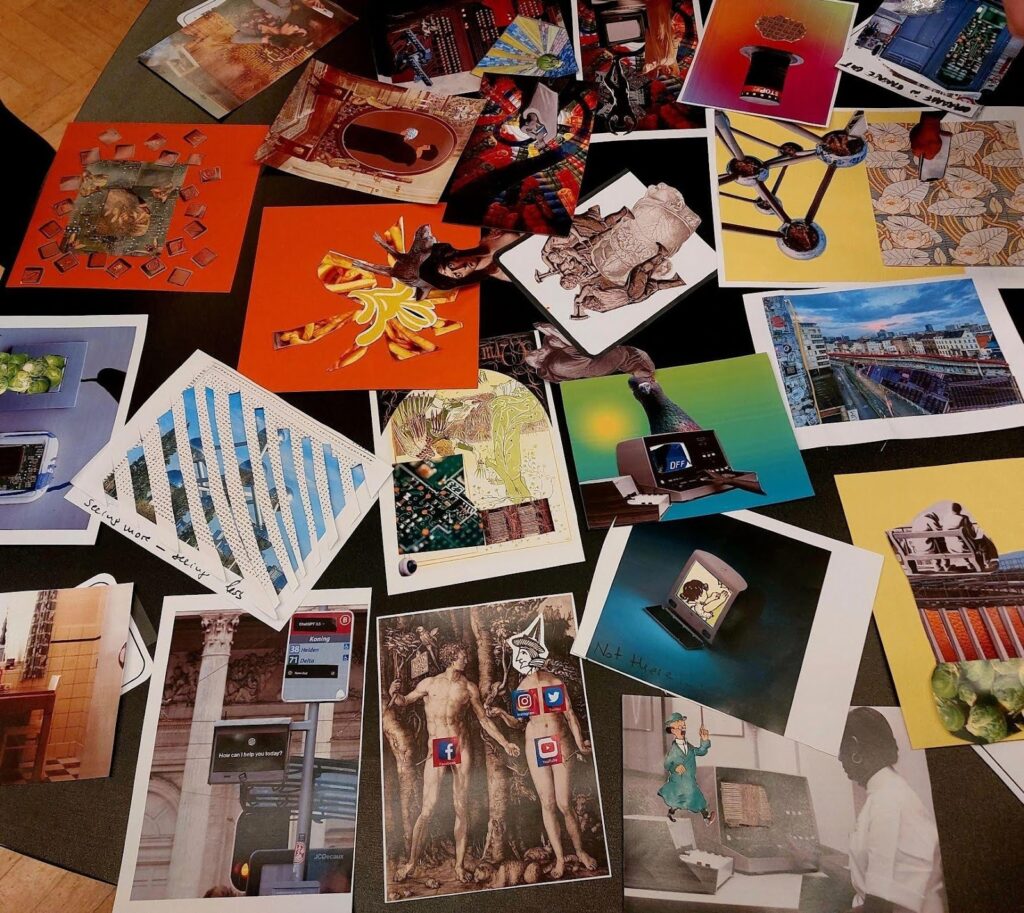
All workshop creations

All creations can be viewed here: BIoAI / FARI Workshop (Feb 2026) | Are.na. Some have been published on the Better Images of AI library. [3]

If you want to organise a similar workshop, here are a few very practical lessons we’d like to pass on:

  • Allow at least one hour for creation. Making several images lets people move past their first ideas and feeds a collective momentum.
  • Test internally first. That’s how we identified the right methods and spotted missing images.
  • Print plenty of images. Local archives, everyday images, digital materiality. We can’t predict what participants’ creativity will call for.
  • Ask participants to bring their own images. We haven’t found the right formula yet (low response rate), but the contributions we received were very relevant.
  • Free up creation before demanding meaning. Abstract or aesthetic images first; critical discourse will follow.

Emancipation through images

We don’t localise AI to promote it; we localise it because it’s already here. By cutting out images of bus stops or Brussels facades, participants made visible what standard AI imagery erases: the presence of these technologies in our daily lives. 

Recommendation algorithms shape our news feeds, language models slip into our conversations, and automated systems sort our job applications. Better representing this reality, by shifting the frame, is already to reclaim it. It’s a step towards emancipation.

“Images […] contribute to drawing new configurations of the visible, the sayable and the thinkable, and thereby, a new landscape of the possible.” — Jacques Rancière [4]

In this spirit, the images created during this workshop were published under a Creative Commons licence. This is the very principle of Better Images of AI: building a library of resources accessible to all. It is also FARI’s reason for being as an institute dedicated to the common good. The entire creation chain rests on shared resources: Are.na, AIxDESIGN’s playbook, public-domain archives, and finally the images themselves under a free licence. Many digital commons dedicated to a better understanding of AI.


About the author 

Headshot of Ulysse

I’m Ulysse Gerkens, a Brussels-based developer and graphic designer. I studied social sciences and economics to understand how society works, then switched to programming at 42 to understand how technology reshapes the world I’d been studying. My internship at “FARI – AI for the Common Good Institute” brought both sides together. Today, I explore how technology and human sensitivity interact through art and collaborative practice.

About FARI and the workshop 

FARI – AI for the Common Good Institute is a Brussels-based research institute bringing together over 300 researchers in artificial intelligence, robotics and digital data. Within the institute, the Citizen Engagement Hub bridges laboratories and civil society: associations, digital mediators, and citizen collectives.

In 2025, the Citizen Engagement Hub committed to digital inclusion. Belgium has an entire network of digital mediators (Espaces Publics Numériques [1], libraries, associations) who help citizens navigate an increasingly connected world every day. It was from this collaboration that the “Tea-Times” [5] were born: welcoming workshops to discover open-source educational resources together, over tea and cake. My task? To find and prepare these resources in advance. That’s how I discovered Better Images of AI and the idea for hosting this workshop on “Localised AI” visuals. 

Acknowledgements

This article concludes my internship at the Citizen Engagement Hub of “FARI – AI for the Common Good Institute Brussels”. I would like to thank Léa Rogliano and Alice Demaret for their mentorship and the trust they placed in me to co-organise this workshop. Thanks to the entire FARI team for their support in organising this event. Finally, thank you to Tania Duarte for her generous contribution during the workshop.

Endnotes and references

[1] Espaces Publics Numériques (EPN): free-access digital spaces staffed by mediators who help citizens with online services and digital skills. In Brussels, they are coordinated by the CABAN network.

[2] Guy Debord, The Society of the Spectacle, trans. Ken Knabb, PM Press, 2024, §12. Originally published as La Société du spectacle, Buchet-Chastel, 1967.

[3] This workshop resulted in the publication of four images on the Better Images of AI library, you can view the FARI collection here.

[4] Jacques Rancière, Le spectateur émancipé, La Fabrique, 2008. Translation by the author.

[5] Tea-Times are funded by the ERDF and the Brussels-Capital Region.

The Mystical Art of Making Maths Sparkle: A Wizard’s Guide to Statistical Sorcery

On the right, a simplistic illustration of a server rack with wires trailing out of it. A yellow sticky note is taped to the rack with a drawing of cartoon sparkles. Text on the left reads: The Mystical Art of Making Maths Sparkle: A Wizard's Guide to Statistical Sorcery, by Berk Alkoç

As you navigate digital interfaces, you’ll increasingly find a sparkle icon used to represent ‘AI’, ‘AI features’ or ‘AI-driven processes’. In the following blog post, Berk Alkoç traces the emergence of this visual metaphor and unpacks the implications of using sparkles to represent AI. In his own 5 steps of statistical sorcery, Berk criticises the corporate narratives about AI as a magical transformation embedded in the sparkle icon, which masks the human labour, data, investment, and materials required to generate AI outputs.


Gather ’round, aspiring data wizards, as I teach you the most mystical art known to computational science: making people think your massive statistical pattern-matching system, trained on human-generated data, is magic, only in 5 steps.

Step One: Add Sparkles

It’s 2023. Every tech company on Earth is scrambling to slap “AI” on their product roadmaps before their next investor call. There’s just one problem: how do you show users where the AI is?

Google had been quietly using sparkles since 2016 for its “Explore” feature in Docs. By 2024, they had deployed nearly 100 different sparkle icon variations across their products, with quarterly growth of 37% in sparkle usage. Notion added purple sparkles. Zoom also added sparkles. Spotify’s shuffle button got sparkles. ChatGPT-4 ditched its lightning bolt for sparkles.

The Wall Street Journal documented this phenomenon in August 2024, noting that seven of the top ten software companies by market capitalisation had embraced the sparkle. But nobody actually asked users if this made any sense.

To test the effectiveness of the sparkles icon, Kate Kaplan from Nielsen Norman Group showed 107 participants sparkles icons in isolation and asked what they meant, and not a single participant mentioned “AI” or “artificial intelligence.”

Instead, interpretations included:

  • Fav or save (16.82%)
  • Visual effects or optimisation (16.82%)
  • Special information (11.22%)
  • “Just plain unsure” (a disturbingly large percentage)

One user captured the confusion perfectly: “In the absence of a heart, I think the star would allow me to save items. Or maybe it’s a wishlist [because] you wish on a star.” One cannot learn a system when the same symbol means radically different things, and sparkles do exactly that. They have such fluidity that, depending on the app and context, people can attribute them with different potential meanings. This is different from an icon for save or search. The floppy disk means “save” because it represents physical save media. The magnifying glass means “search” because that’s how you make small things visible. The problem is not that users misunderstand the sparkle icon, but that the icon makes misunderstanding structurally unavoidable. 

Step Two: Train Users Through Sheer Repetition

Google’s own 2024 research with 2,000 participants across eight countries found that users did recognise sparkles signified AI; however, even in this research, Google’s researchers noted: “they didn’t have a consistent definition of what AI meant” and couldn’t distinguish machine learning from generative AI from image generation. The conclusion Google’s own team reached was clear: 

 “Ubiquity leads to a lack of specificity and can diminish an icon’s effectiveness.” 

Nearly 100 Google system icons include an AI Sparkle (Source: Google Design Blog)

This means that the sparkles work because Google trained users to recognise them through sheer repetition, not because the metaphor is sound.

The industry defense is simple: Doesn’t “AI feel like magic?” Because basically, “You type words and it writes an essay! That’s wizardry!

And here’s where we need to question what magic is. 

Step Three: Invoke the Magic Metaphor

Kate Crawford and Alex Campolo coined the term “enchanted determinism” in their 2020 paper. They argued that AI systems are framed as simultaneously magical (unknowable, mysterious, operating through forces we don’t understand) and deterministic (accurate, reliable, producing correct results). 

This combination is insidious: it shields creators from accountability while amplifying AI’s power to classify and control. The mechanism is simple. Magic can’t be questioned. It just is. When results go wrong, no one is responsible. The wizard explains: “The spell was cast correctly; the universe responded in mysterious ways.” Replace “spell” with “model” and “universe” with “training data,” and you’ve got the standard AI liability dodge, word-for-word.

M.C. Elish and danah boyd put it more bluntly in their 2018 paper: framing AI as magic denies “an accounting of what went into making something work, or that it required work at all.” Magic is “costless in terms of the kind of drudgery, hazards, and investments that actual technical activity inevitably requires.”

But AI isn’t costless—and neither, historically,  is magic. Actual magic is expensive. Research on magic practices notes that practitioners typically know it doesn’t work every time and requires significant effort, cost, and risk. Machine learning follows the same pattern. It’s not an effortless transformation; it’s finding optimal data variables, communicating with systems to access data, cleaning datasets of faulty values, evaluating ML library outputs, designing comprehensible interfaces, and iterating when you get AI slop. You cast the spell, check if it worked, and cast it again with adjustments.

Leo Lau & Digit / Better Images of AI / CC BY 4.0

Both magic rituals and ML systems suffer from domain disjunction, where you perform actions in one symbolic system hoping to affect outcomes in another. In magic, you might perform a ritual with certain tools (symbolic domain), hoping to heal someone, or influence the weather (material domain). In ML, you run statistical operations on numerical representations (symbolic domain), hoping to optimise ship propulsion (material domain). The gap between domains necessitates interpretation.

✨ Magic Ritual Domain🤖 Machine Learning Domain
Symbolic SpaceThe Ritual: Rain danceThe Math: Statistical operations on massive numerical datasets.
Material OutcomeThe Goal: Influencing the weather.The Goal: Optimising ship propulsion or detecting bank fraud.
Reason for FailureThe Excuse: Incorrect ritual performance or poor cosmic conditions.The Excuse: Poor data quality, bad architecture, or “hallucinations.”

As anthropological research notes

“something is performed to influence the relations in a different space.” 

Both systems require experts to translate between domains, ritual specialists for magic, and data scientists for ML. And both systems require explaining why things fail. Magic practitioners blame incorrect ritual performance, cosmic conditions, or counter-magic. ML practitioners blame data quality, model architecture, or adversarial inputs. One could argue that “magic” is simply a metaphor for the complexity that no user can realistically understand large-scale machine learning systems. But complexity does not require mystification.

Step Four: Repeat, Repeat, Repeat

So how and why were sparkles forced into UX (User Experience) and UI (User Interface) Design processes despite the fact they didn’t  work?

This Wall Street Journal article framed it as: 

“Design and marketing executives at software companies said they started using sparkles because everyone else was doing it.” 

Dan Saffer, who designed Twitter’s sparkle toggle “as a joke,” later observed that subsequent adoption reflects “FOMO rather than intentional design,” companies copied each other to maintain consistency with user expectations (Jakob’s Law). However, Jakob’s Law says users expect systems to work like ones they already know. It doesn’t say you should create bad patterns just because others did. The sparkle standardisation happened too quickly for users to learn the pattern naturally. Instead of allowing intuitive understanding to emerge, companies used brute force repetition to teach users a metaphor that actively undermines accurate mental models.

When your bank’s fraud detection algorithm flags your transaction, do you want to think of it as “magic” or as a statistical model with false positive rates that you can dispute? When an AI hiring system rejects your resume, should that feel like inscrutable sorcery or like a technical system whose biased criteria you can understand and challenge? The sparkle icon succeeded not because it communicates well, and we have overwhelming evidence it doesn’t, but because it aligned with corporate narratives about AI as magical transformation. But that’s exactly backwards. Icons that don’t need explaining work because they map to shared understanding. Sparkles mean “magic” because that’s their cultural association, and magic is precisely the wrong metaphor for the technology we want people to understand, question, and hold accountable. What emerged was not a shared language shaped by users, but a visual convention enforced by corporate anxiety.

Step Five: Wait for Everyone to Forget

So here we are with sparkles everywhere, an icon that succeeded despite failing every measure of good design. Interface design is political work. Sparkles prove it. But we’re not stuck.

There are two scenarios ahead. In the first one, companies aggressively integrate AI into every product. In the second one, a more balanced, accountable approach emerges. In both, sparkles will fade, but for very different reasons.

In the first scenario, AI integration becomes so aggressive and comprehensive that the distinction between “AI features” and core functionality disappears entirely. Visual editing software where every tool uses ML, email clients where every function involves algorithmic processing, productivity apps where AI is woven into every interaction. Here, sparkles become meaningless. Not because the mystification problem is solved, but because there’s nothing left to distinguish. If everything is AI, then nothing gets the sparkle. We don’t mark every website with an “Internet Inside!” badge. Ubiquity eliminates the need for announcement, but not the need for accountability.
In the second scenario, responsible tech practices and comprehensive AI literacy create pressure for differentiation rather than blanket mystification. Here, sparkles fade because they’re replaced by something better: context-specific disclosure that distinguishes low-stakes autocomplete from high-stakes algorithmic decision-making. The non-deterministic nature of ML (the errors, the biases, the “hallucinations”) doesn’t disappear through normalisation, so the ethical case for explicit signalling remains. Sparkles become inadequate precisely because AI use cases vary so wildly in consequence and reliability.

We’re already seeing this second path emerge in certain cases.

For instance, at Molo, a German civic engagement app where I lead the UX/UI design processes, we faced this exact choice when implementing AI-powered search. I advocated for using a search icon with ‘KI’ (Künstliche Intelligenz) rather than copying the sparkle to prioritise clear, specific, and understandable visual communication. It’s these small decisions that add up to either mystification or transparency. The BBC’s recent approach offers another example on a more systematic level. Instead of adopting the industry-standard sparkle, they developed a neutral hexagon derived from their brand blocks, paired with context-specific disclosure language following a “How we used AI” formula. Their research confirmed what Nielsen Norman found: users want specifics, not mystification. 

A screenshot from the BBC website, which shows a neutral hexagon derived from their monochrome brand blocks, paired with context-specific disclosure language following a "How we used AI" formula.

This particular disclosure label is being trialled in BBC Sport live reporting (Source: BBC Media Centre, 2025)

I believe that the sparkles will fade either way, through ubiquitous integration or through intentional replacement. But only one of these paths solves the actual problem. They’ll disappear meaningfully only when the people who build these systems decide that our responsibility isn’t to make technology feel magical, but to make it understandable. That means different choices in product development: disclosure rather than sparkles, specificity rather than mystification.

When you see those sparkles next time, remember: you’re witnessing the tech industry’s commitment to mystification over clarity, vibes over user research, and enchantment over explanation. The question isn’t whether sparkles communicate clearly. It’s whether we’ll accept a digital future where corporate magic tricks replace technical literacy.


About the author

A headshot of Berk.

Berk Alkoç (he/him) is a designer–researcher based in Germany exploring the intersections of technology, cities, and everyday life through a critical (and unapologetically queer) lens. At ZeMKI, University of Bremen, he designs for Molo, a civic media platform. At the Institute for Technology Assessment and Systems Analysis (ITAS) at the Karlsruhe Institute of Technology (KIT), he researches nature conservation through a relational values lens and how digital tools shape environmental governance. Outside of work, he’s likely outdoors or immersed in something visual, whether behind a camera, sketching, or experimenting with graphic design.

Submission Handbook for Better Images of AI

A poster with the text 'Submission Handbook for Better Images of AI: Available Now!' with three bullet points beneath which state 'Image criteria, IP guidance, and AI policy'. On the right is a picture of the cover of the Guide which has a collage of pictures from the library at the bottom and the top. In the centre is the text, 'Submission Handbook for Better Images of AI' with explanatory text beneath.

In 2025, we uploaded 60+ images to our library. During this time, we’ve been fortunate to work with several organisations which have culminated in collections of images as well as contributions from individual creators. To make the process of submitting images to our library easier for everyone, we’ve released our Submission Handbook for Better Images of AI. This is our first attempt to publicly communicate our guidelines and policies for submitting images to the Better Images of AI library.

Importantly, anyone can submit an image for consideration in the library. Our library features brilliant contributions from art students, researchers, amateurs, and professionals from all fields across the world. As a non-profit organisation which is run entirely by volunteers, we are grateful that most images are kindly donated* to the library by these amazing creators.

What’s inside the Submission Handbook?

  • Our image criteria: what elements do we look for in ‘better images of AI’ and what tropes should you avoid?
  • Our submission form: easily submit images via our new form
  • Inspiration and resources: get started creating your own better images of AI
  • Intellectual property guidance: steps to ensure your images do not infringe 3rd party rights and learn more about the Creative Commons licence that images published in the library are covered by
  • AI policy: our prioritisation of human-created visuals and restrictions on AI-generated art

This Handbook will serve as a working document which we will continue to update as we learn, reflect, and find more useful information to share with our creative community. Previous versions will be archived here.

If you spot any mistakes or have suggestions for ways to improve the Submission Handbook, please do get in touch with us by emailing info@betterimagesofai.org. We’d love to hear from you.

Finally, we would like to extend our gratitude to volunteers Söğüt Atilla Aydın, Elja Daae, Harriett Humfress, Grace Jenkins, Beckett LeClair and Laura Martinez for providing advice and feedback which supported the development of this Handbook.

* We do sometimes work with organisations that can commission images or run art competitions with monetary prizes. If you might be more interested in paid work related to our library, do sign up to our newsletter where we share these opportunities.

Why We Need Better Images of AI From Science Fiction

A photographic rendering of a simulated middle-aged white woman against a black background, seen through a refractive glass grid and overlaid with a distorted diagram of a neural network.

Science fiction plays a decisive role in shaping perceptions of technology, particularly artificial intelligence (AI), not only through its literary narratives but even more pervasively through its audio-visual representations. These depictions do not merely reflect technological developments; they actively influence how we perceive and relate to emerging technologies long before they enter our daily lives. Through imaginative storytelling and the development of ‘diegetic prototypes’, science fiction also inspires ideas about what the future of society should and shouldn’t look like. However, when we look at science fiction from a more critical perspective, it becomes clear that there is a divide between the literary version of science fiction (s.f.) and its adaptation in motion pictures (eye-sci-fi) (1).

In this blog post, Yeliz Figen Döker (The Digital Constitutionalist) and Zoya Yasmine (Better Images of AI) explore this distinction in more depth and examine the limitations of dominant images of AI drawn from eye-sci-fi. This is a commentary on the Better Images of AI Guide which includes ‘science fiction references’ as a trope to avoid in AI visuals. Instead, Yeliz and Zoya argue that while AI visuals drawn from eye-sci-fi create harmful representations of AI, we can learn a lot from the literary roots of the science fiction genre. Inspired by the findings in this blog post, DigiCon and Better Images of AI worked together to create a flipbook of ‘better images of AI’ that show more thoughtful and pluralistic representations of the technology that carry the ethos of science fiction, as opposed to dominant tropes derived from ‘eye-sci-fi’.

 “Science fiction does not just offer speculative representations of social reality it may, in various ways, help to shape it” (Brennan, 2016)

Science fiction as a causative force

Science fiction is a genre that explores the unlimited possibilities of imagination while also basing it on the tangible realities of scientific discovery. This very harmonisation, blending factual elements with imaginative concepts, makes it the prime example of an oxymoron. As such, the rise of science fiction can be viewed as a natural reaction to the rapid pace of scientific advancements.

In addition, science fiction helps shape the future by preparing the minds of scientists and laypersons. Indeed, in the 1960s, computer scientists at MIT popularised certain narratives in film and journalism to influence the direction of future research and the greater adoption of their lab’s computing technologies (see here for more information). Also, the launch of the first Russian Sputnik marked the beginning of the space race that defined the 20th century. In fact, it is no coincidence that Konstantin Tsiolkovsky, known as the father of space flight and the founder of astronautics and rocket science, was also a science fiction author. Not to mention that the great astronomer Edwin Hubble was inspired by the works of Jules Verne, often regarded as one of the founding figures of the genre. This motivation to enter scientific fields often springs from the deep admiration and passion that scientists feel for science fiction. These illustrate that science fiction does not solely predict the future; it also helps devise it. Its influence extends beyond imagination and speculation, shaping the aspirations of those who invent new technologies, make scientific advancements, and strive to make the impossible possible.

The limits of ‘eye-sci-fi’ and the value of ‘science fiction’

However, audio-visual representations of science fiction often fail to capture the depth and critical edge of its literary form. Instead, they tend to fall back on familiar, anxiety- and action-driven tropes with the help of extensive usage of visual effects, like killer robots (2), godlike AIs, and dystopian collapse, which in turn dominate the visual language of science fiction. This flattening effect reinforces outdated and misleading ideas about technology, sidelining the experimental and diverse visions found in the works of authors like Robert Heinlein, Brian Aldiss, Stanislav Lem, Philip K. Dick, Alice Sheldon (James Tiptree, Jr), or Octavia Butler.

According to Isaac Asimov, one of the most prolific authors of science fiction, this divide traces back to the very abbreviations used to categorise the genre. In his reflections on science fiction, he describes it as split between printed science fiction (s.f.) and motion-picture science fiction (eye-sci-fi). He points out that “good” science fiction must necessarily have a high intellectual content, because it must deal with science and people and their interactions in a reasonable and knowledgeable manner. However, eye-sci-fi often fails to meet these criteria; instead, it focuses on visual special effects, including spectacles of vast destruction, alien or monstrous beings, and feats made possible by zero gravity or wild talents.

In his view, eye-sci-fi tends to prioritise special effects, with each production aiming to surpass its predecessors in spectacle to secure commercial success. He maintained that this reliance on spectacle makes eye-sci-fi almost a different genre altogether. With the boom effect provided by Hollywood, eye-sci-fi quickly achieved enormous popularity, generated unprecedented profits, and inspired a wave of imitations. Yet, Asimov believes that these imitations rarely matched the quality of the original works in science fiction. His critique remains relevant, as seen in many contemporary adaptations. Just recently, Netflix’s adaptation of Cixin Liu’s The Three-Body Problem was widely described as flat and shallow compared to its original, with some arguing it was produced by and for Western audiences as opposed to its more diverse origins.

The problems with relying on eye-sci-fi for AI imagery

“Narratives of intelligent machines matter because they form the backdrop against which AI systems are being developed, and against which these developments are interpreted and assessed” (Cave, Dihal and Dilon, 2020

Eye-sci-fi images are just not that imaginative

While the s.f. can push us to think about the future in novel and original ways, eye-sci-fi often falls back on well-worn narratives that restrict us from imagining technology unconstrained from existing power structures. The dominant stock images of AI are an extension of this myopic perception. Recurring stereotypes, overly sexualised gynoids reminiscent of Hel in Metropolis, rogue killer cyborgs from Terminator, or white-skinned, blue-eyed robots with glowing positronic brains as depicted in the I, Robot film, are typically based on the metaphors drawn from a simplified interpretation of eye-sci-fi.

In relation to how these eye-sci-fi visuals influence our thinking about AI, we argue that they create illusions of inevitability, reinforce harmful representations of race and gender, and divert attention from the real AI developments that are happening right now, such as biased algorithms, mass surveillance, environmental damage, and worker exploitation.

Eye-sci-fi has a diversity problem

One of the most troubling aspects of eye-sci-fi-inspired AI images is their lack of diversity. A study by Cave et al of 142 influential AI-themed films from 1920-2020 found that only 9 AI professionals depicted were women. Eye-sci-fi narratives have a tendency to misrepresent the history of AI, which has benefited from the works of diverse communities – for instance, black researchers at MIT working at Project MAX, a computation-focused research group or the many women at Bletchley Park behind the success of Alan Turing’s Enigma machine. Despite these realities, images of AI often overlook and misrepresent the real lives of women, people of colour, disabled individuals and other marginalised groups.

Beyond the representations of those working in the AI industry, Law comments on the visions of the future often portrayed in science fiction cinema. This is not only in terms of who appears on screen, but also in the kinds of futures these works imagine. The aesthetics, values, and power structures they normalise tend to follow familiar, exclusionary patterns. This lack of diversity is not solely about representation, but about the imaginative limits placed on what futures are thinkable and advocated for.

For instance, the 1927 film Metropolis (3) features a robot turning into a white woman, a transformation maliciously orchestrated by a white-male-mad scientist who abducts ‘Maria’ and imposes her likeness onto the machine, ‘Hel’. Furthermore, in this case, the robot is modelled on Maria, a saintly, Madonna-like figure, yet it later becomes her opposite, a hypersexualised, deceptive, and destructive version. What is troubling is not only the racial coding of the machine but also the rigid moral division it constructs. The ‘good’ woman is human, submissive, and pure, whereas the ‘bad’ woman is artificial, desiring, and dangerous. Rather than offering a critique of automation or identity, the film ultimately mirrors long-standing cultural anxieties about women who do not conform. We also note that science fiction scenes involving ‘human-machine-symbiosis’ reinforce the idea that the futures of computing are inseparable from notions of whiteness. In doing so, eye-sci-fi promotes the idea that AI technologies are built by/for white individuals or certain gender prototypes, overlooking the role of marginalised groups played in the development of AI. These biases influence not only who is viewed as an AI developer, but they also skew our perception about who should be included in conversations about its governance and development.

Eye-sci-fi tropes exaggerate AI’s capabilities and create fear mongering

Eye-sci-fi often portrays AI as vastly more powerful than it actually is. These misleading images can exaggerate the possibilities or scope of what the technology is capable of, which creates a disconnect between reality and how it is viewed by the public. The use of inaccurate images can be intimidating to people who are non-experts, as the visuals construct a future that can appear dystopian, disturbing, and create a culture of distrust or worry about AI. While such exaggeration might seem inherent to the genre’s speculative nature, as its role is to ask “what-ifs”, these portrayals do not emerge in a vacuum. They are closely entangled with the conceptual development of AI itself.

Since the theoretical foundations of the field were laid by Alan Turing and its formal naming at the Dartmouth Workshop in 1956, many have argued that the ultimate aim of AI has been the creation of human-level, or even general intelligence that surpasses human-level. This ambition has led to a taxonomy within the field that distinguishes between Artificial Narrow Intelligence (ANI), Artificial General Intelligence (AGI), and Artificial Superintelligence (ASI). While ANI refers to systems that perform specific tasks, such as image recognition or language translation, AGI denotes a still-hypothetical system that is expected to perform generality in many domains and be capable of flexible, human-like reasoning across domains. ASI, in contrast, refers to intelligence that would surpass human capabilities altogether, which also simply does not exist at the moment.

Science fiction can indeed serve as a powerful tool for critical reflection and learning. However, the dominant tropes of eye-sci-fi often obscure rather than clarify the real challenges posed by the AI that we interact with today. Stock imagery depicting AI often exaggerates the reality, desirability, and even existence of AGI and ASI. Although it is natural for the genre to imagine beyond present capabilities, it is important to question which visions gain prominence and why. Many literary works do offer more complex and less anthropocentric visions of machine intelligence, but these are too often eclipsed by blockbuster simplifications. Thus, we advocate for deeper engagement with literary portrayals of AI that resist these tropes, particularly those that do not hinge on the assumption that AI will inevitably dominate humanity or that its future capabilities must be framed through the lens of “superhuman intelligence.”

What are some of the limiting eye-sci-fi visuals and their impact on their perception of AI?

The persistent use of misleading AI visuals can lead to inflated expectations, which obscure the real and present challenges that AI poses.

Some of the most common eye-sci-fi AI images include:

  • Descending code: popularised by The Matrix, these visuals refer to a dystopian science fiction scenario in which humans are enslaved by AI. To those for whom the link to the Matrix films is not clear, images of descending code can be alienating by presenting AI as a wall of incomprehensible symbols.
  • The human brain: although only a portion of AI research attempts to reconstruct the human brain electronically, the digital version of the human brain is generally used when describing the functions of AI. Treating the human and AI brain structures as equal gives the impression that AI must mimic the human brain.
  • White robots: the embodiment of AI as robots that are white in colour, ethnicity or both, associates intelligence with being white. Such images serve as a barrier to increasing racial and ethnic diversity in AI development and decision-making, and exclude the global majority.

Breaking free from common tropes in eye-sci-fi with science fiction

 “Futures can warn and promote, and hold the power to exclude as well as include.” (Law, 2024)

Images from eye-sci-fi are limited by the fact that they are usually derived from audio-visual depictions and adaptations of science fiction. Eye-sci-fi mediums need to attract large, diverse audiences, so it is understandable that they do this through identification with characters using universal human traits and also sensationalist narratives (4). While these formats are effective at engaging viewers, they often constrain the way we explore and think about AI by only representing it in terms of its similarity to humanity and its inevitability to take over the world. This framing makes it harder to see AI for what it is and the more diverse imaginings of what it could become.

The eye-sci-fi images of AI severely lack any positive images which show humans having agency and being in control of the technology, as opposed to being threatened or marginalised by it. Indeed, Noessel’s ‘Untold AI’ analysis points to messages from the technology industry that eye-sci-fi does not engage with. In light of this, Noessel recommends that science fiction creatives could help us better understand real-world AI by telling stories and accurately covering the realities of AI in popular media.

The flip book

Although science fiction/eye-sci-fi images are often excluded from the Better Images of AI library because they focus on speculative futures (4), there is still room for science fiction-inspired visuals of AI that break free from harmful tropes. By challenging dominant narratives, thinking carefully about diversity, and expanding our imagination, better images of AI from science fiction can shape how we think about AI that is not limited to glowing brains and anthropomorphic robots.

Some of the criteria for ‘better images of AI’ from science fiction include:

  • Realism: representing AI as it exists today, rather than relying on speculative visions.
  • Diversity: showcasing AI in ways that include a broad range of human experiences and identities.
  • Honesty: showing what the AI system can actually do, and nothing more.

Better Images of AI and the DigiCon created a flip book which features a curated selection of artist-created images from the Better Images of AI library. DigiCon’s science fiction section does not rely solely on conventional eye-sci-fi narratives. Instead, it approaches science fiction as a field for thought experiments, a diagnostic lens, and a tool for regulatory learning. This flipbook was born out of a shared interest between Better Images of AI and DigiCon to show how the two platforms can complement, challenge, and learn from each other.

* To ensure broader accessibility, we have also created an accessible version of this flipbook. It retains all the original content while offering improved readability for screen readers and users with visual impairments.

While Better Images of AI provides visuals, DigiCon offers a conceptual framework, inviting readers to think more carefully about AI through embracing the critical perspective and power of science fiction. Although the curated images in the flip book are not science fiction-based, they open up thought patterns that resonate with the genre and inspire more thoughtful representations of AI, which acknowledge its material reality, expose its current limitations, and explore its actual functions in everyday life.

Sifting through the flip book, you’ll find some ‘better images of AI’ alongside some personal reflections from the volunteers that are part of the Better Images of AI community, who keep the library going. Their thoughts show how each of the images in the library tells more thoughtful and pluralistic stories about AI than those which are commonly presented in the dominant media inspired by ‘eye-sci-fi’.

Science fiction (and its derivative eye-sci-fi genre) will continue to influence how we think about AI, but if we want more productive and meaningful discussions about its development, we need richer, more diverse visual languages. We hope that this flip book can serve as an inspiration for more productive avenues of framing AI that foster better visuals and narratives around what the technology is and what it should become.

End notes

(1) The eye-sci-fi abbreviation was coined by Isaac Asimov in his essay on “The Boom in Science Fiction” in 1981, Asimov on Science Fiction. Asimov used this term to separate the science fiction adaptations in motion pictures from the literary and printed works of science fiction, which he refers to as “s.f.”.

(2) It is also worth recalling that the very term robot derives from the Czech word robota, meaning forced labour or servitude. Asimov noted that in translating Čapek’s play into English, the term “robot” was chosen over “slave” to mark a distinction between natural and artificial beings. Yet the historical association with subjugation lingers in today’s portrayals, reinforcing fears of rebellion and control.

(3) Even Metropolis was reshaped by early Hollywood’s eye-sci-fi priorities. To make it more marketable, American distributors cut the runtime, simplified the narrative, and removed all mention of Hel, partly because the name sounded too much like “Hell.” Lang later called this edit a cruel mutilation of his film.

(4) The Better Images of AI library serves to show AI as it is currently, not in the future. Although speculative work can be valuable, our library is for the here and now. You can see our library image criteria here.

About the authors

A headshot of Yeliz

Yeliz Figen Döker is the co-founder of DigiCon, where she leads the science fiction section as both operational and editorial head. She is also a Resident Lecturer at the European Law and Governance School, established by the European Public Law Organization. She is also a PhD researcher at the European University Institute in Florence, specialising in the regulation of Artificial General Intelligence.

Zoya Yasmine is a Lead at Better Images of AI, where she supports the behind-the-scenes running of the library. She is also a PhD student in Law at the University of Oxford, where her research explores the intersections between medical AI, law, and ethics.

A headshot of Zoya

Cover image: Alan Warburton / Better Images of AI / © BBC / CC BY 4.0

This text was originally posted on the Cambridge Journal of Artificial Intelligence blog

Behind the Image: Digitalisation and Moonlighting

Two of Julieta's images sit on a slant on the right. On the right side, the text 'Behind the Image Series' in turquoise text box with black text. Underneath, in black text reads: 'Behind the Image: Digitalisation and Moonlighting'. In dark purple text, 'Julieta Longo in conversation with Laura'.

In this blog post, Laura Martinez Agudelo (volunteer steward) chatted to Julieta Longo (artist) behind the series of images ‘Digitalisation and Moonlighting’ that were awarded as a runner-up in the Digital Dialogues competition that we ran this summer.

The aim of the Digital Dialogues competition was to visualise some of the Digit Centre’s research on work and technology. Julieta speaks to the importance of visualising research, advocating for artistic approaches that better represent authenticity and collective experience. 

The discussion was conducted in Julieta’s native language, Spanish, which has been translated by Laura in English below. You can access the Spanish version here (albeit in a slightly different format and structure, but all the same content). 

The rhythms of life and facets of working life

Digitalisation and Moonlighting (1 and 2) focuses particularly on how precarious jobs affect mothers and people with care responsibilities. Through her graphic choices, Julieta highlights the tensions and the balance between paid and unpaid work, which in many cases is operated and/or mediated by digital platforms and/or artificial intelligence systems. 

Woman working simultaneously as a delivery worker, remote employee, and caring her child, representing the opportunities and risks of work digitalization.
Julieta Longo & Digit / Better Images of AI / CC BY 4.0

Julieta shares her motivations and the link between her images and the topics she explores in her research and personal life: 

It was an image that was initially intended to reflect on multi-job holding, which is a global issue, but in Argentina in particular it is being hotly debated because incomes have fallen too much in recent years. The use of platforms and remote or distance work has to do with the need to supplement income. It seemed to me, then, to be a central issue for thinking about artificial intelligence and technology. Also, because this type of work does not produce a new type of technological worker, but rather adds to the existing workforce and is often linked to traditional jobs.

In Digitalisation and Moonlighting, we see a person, a woman, who supports and sustains herself in her many roles. The last step represents the role of mother and seems to finally be in a moment of rest. Julieta’s illustration is a very telling and thoughtful way of bringing various topics into dialogue: gender, informal and remote work, the question of everyday life, time, motherhood and care. This last aspect is also mentioned in the description, and it should be noted that it is not always included in the graphic representation of the theme of the digitalisation of work. 

Julieta confesses that she even made this illustration while she was a little tired: “… I drew the last woman looking after the baby with her eyes closed, a little bit tired but also relaxed… because it reflects a very genuine need to organize our time better, to have jobs that allow us to organize ourselves better and, above all, to have more non-working time.

The inspiration for this work came from a reflection on how to graphically represent the phenomenon of having multiple jobs (moonlighting) in contemporary societies, a situation marked by digitalization, intimate life stories and the time devoted to work.  From her point of view, new technologies play a role in transforming our rhythms of life: “there is a certain idea that technologies will allow us not to be in an office all our lives and therefore to organize our lives differently… not to be in a workplace all the time, whether it be an office, factory or shop… I think that the idea of moving away from traditional work and having more time for life is a very important demand that technologies introduce, resolving contradictions and creating new ones.

As for the illustration process, Julieta created it digitally using Procreate and Adobe Fresco, and she gives us details about the decisions and changes made along the way, as well as the inclusion of self-referential elements, especially the balance between motherhood and remote work: 

“I often work remotely, from home or at an office, but not every day. And this, which at first seemed ideal, or at least I thought it was ideal for motherhood, comes with a lot of additional burdens and responsibilities. In fact, I came to romanticize the idea of being able to work and look after my daughter at the same time, even though it wasn’t always possible, but I thought it was nice to work close to my daughter. I think that romanticization is often present in remote working because it allows you to balance different aspects of your life. You are at home and your children are playing nearby, but that balance has many contradictions, and I did not resolve them.” 

Returning to her perspective as an illustrator, Julieta tells us that she draws frequently, mainly digitally, and also shares her thoughts on her own artistic practice: “I’m drawing a lot digitally at the moment. I would like to go back to not doing everything digitally, but I find it really difficult, especially because it takes much less time, which raises several contradictions related to technology and work in general.

Connected, Yet Disconnected

Three isolated people using laptops and phones to work.
Julieta Longo & Digit / Better Images of AI / CC BY 4.0

The image Connected, Yet Disconnected’ evokes themes such as the emotional and social isolation of the digital worker and shows the paradox of AI-driven work and spatial disconnection in contemporary employment. Julieta tells us that it is the first image she made for her research, thinking about people who work connected and who are close together, sometimes only momentarily, sharing the same space

It is very likely that next to a person working in an office, or as a freelancer, there is someone bringing them food or deliveries. They probably don’t talk or know each other, and sometimes the transaction is very quick, such as delivering food, for example.” 

Julieta believes that the space shared between these people is completely fragmented by digital technology. In the first image, we see overlapping people (actually the same person in different roles), but in this one we identify an overlap and spatial convergence of different people who could be very close to each other and, at the same time, working with people who are far away or remotely.

Through this graphic proposal, Julieta seeks to illustrate that: “people are not only close because they are connected. Today there is a very interesting ambiguity, which is that virtual space breaks down physical space a little, and it does so in both directions. It connects us with people who are far away, but it also disconnects us from all the people who are close to us. On the other hand, there are a lot of everyday problems that are solved digitally, breaking the link with the physical world and other strategies for being in it. 

I think, for example, of mobility and how I used to travel before I had a mobile phone. The first time I travelled alone, I didn’t have a mobile phone and I spoke to a lot of people to get to the place I had rented. The intention of travelling also has to do with being present in the places I go and getting to know the people who live there, but now I could solve almost everything on my own.

The same thing happens in the world of work, with digital work and even in the dissemination of knowledge: Many people who work use a lot of the knowledge produced by others, but the social link has been lost. It is also very positive to have the possibility of socializing knowledge in a very agile and useful way. But I am very nostalgic for everything that has been lost in social terms.

Visualising Research Through Better Images

Julieta thus revisits the idea of the importance of creating images that can be articulated with research: “… I am somewhat in search of trying to articulate research and illustration, increasingly and better, and also thinking more collectively about this articulation.’ Julieta points out that even for book covers, using meaningful images helps a lot to bring people closer to certain texts, content and topics: 

“images could be integrated much more into research, both to disseminate results and to reflect on research results or conduct interviews. I think images have a lot of power, because it is much easier to see whether they represent your reality or not. They also allow for discussion or encourage conversation on certain topics. For example, being able to conduct interviews with images to elicit interactions, testimonials, and make other issues visible.” 

It is for these very reasons that when Julieta discovered the Better Images of AI library, she decided to share information about this image bank with her fellow researchers: “ I sent the information about the Better Images of AI image library and database to all the researchers I work with, because I think it’s great and often, we want to incorporate images into our research but we don’t have much artistic training, there isn’t much reflection in general and this type of training doesn’t exist in our fields. So, what we do is use royalty-free images from the internet that seem more or less appropriate.

Regarding the role of the artist in proposing new visual narratives, Julieta believes that: “There are artists who are artists and who interpret reality very well. There is a certain idea that art captures reality, unconsciously, but I think there could still be more opportunities for dialogue with artists. There are many artists who reflect a lot, based on their own interests, because they read about current affairs or listen to talks according to their preferences. The same thing happens with researchers, who often want their research to be articulated through artistic expression. I think it’s interesting that broader debates begin to take place. It might be a good idea to bring together artists, workers and researchers so that we can think together about the images we want to use to represent reality. Obviously, not all artistic production has to be like this, but I believe that if these dialogues exist, they can encourage more critical reviews of why we are doing things the way we do!”  

Julieta believes it is important to have this reflection at a collective level, among illustrators and researchers: “There are many artists who read and question themselves from similar places and topics but from an individual interest. I think that there is a lack of articulation, or more explicit dialogue, between those who make art and those who research.”

Julieta began to develop a connection with art from a very young age: she studied at an art school and years later enrolled at the Faculty of Fine Arts in Argentina. It was later that she decided to study Sociology and pursue a professional career in that field. That is why, even though she was already a sociologist, Julieta continued to do some illustration work: “I always felt quite hybrid… For many years, I was unsure what to do, whether to devote myself to illustration or sociology, and there was a period when I almost exclusively devoted myself to illustration.

Julieta believes that visual narratives surrounding technology and artificial intelligence are sometimes abstract, and emphasizes the need to show images that conjure up and combine other realities that are more diverse and inclusive: 

When you search for technology, you see lots of images that are far removed from reality and make you feel that technology doesn’t affect us. The same thing happens with artificial intelligence. If you search on Google, many images appear that are far removed from our daily lives. I think we forget to show that everything is integrated into our intimate and collective experience, in the city, in the world, with people, in the distance and with ourselves.”

Gender is another issue that has enabled Julieta to question this connection and the need to produce new and better illustrations: “There is another issue that also challenges me greatly when it comes to connecting research and illustration, and that is gender. With this issue, something similar happens to what happens with images related to technology: there are many clichés.

Julieta recalls that when she was about to devote herself fully to illustration, she worked on some very interesting projects at the Ministry of Women, Gender Policies, and Sexual Diversity of the Province of Buenos Aires: “We had to do a lot of visual production for different materials, and what you always do is look for what already exists. And when we looked for what already existed, in visual terms, it was always the same thing. For a specific project, I had to change the gender of all the images I saw on the subject of traditional professions. For example, I was looking for images of builders, and they always showed men or hyper-stereotypical and even very sexist images of women. It was very shocking not to be able to use any images. This made me realize that there were very few that represented what we wanted to illustrate in the project. It’s incredible that we always have to do that, like a translation, that is, change the meaning of the images we see.” 

Julieta also points out that, within these projects, it did her a lot of good to question who was represented in her drawings and how. In other words: How can we represent diversity in a way that does not make it seem like a minority? How can we find ways of representation that challenge more traditional views? Why are certain sectors made invisible and not others? Most of the time, we just reproduce stereotypes!

Line drawing of an individual riding a bike surrounded by flowers and plants.
Line drawing of an individual carrying two black bin bags.
A line drawing of an individual in an apron in a boat full of fish in a lake.

Some of Julieta’s previous artistic works

Similarly, returning to the subject of technology, it is not always possible to find images that adequately describe different techno-realities: “very abstract images appear, with very neat environments and people, all with good living conditions or very settled lives. These are ideal worlds, and it would be wonderful if everyone had those opportunities, but these images are very far removed from what exists in the real world.” 

About the artist

Black and white headshot of Julieta.

Julieta Longo, illustrator and sociologist, was born in La Plata, Argentina, in 1985. She is a researcher (CONICET) and teaches Sociology at the National University of La Plata. She also continues to draw. Recently, was illustrator for the Ministry of Women, Gender Policies, and Sexual Diversity of the Province of Buenos Aires. In 2019, with Mercedes Roch, she published Primeras (second edition 2024, Malisia-Ediciones Bonaerenses), a book that tells the stories of women who, for the first time, did things previously reserved for men.

About the author

Laura Martinez Agudelo is a Teaching and Research Assistant at the University Marie & Louis Pasteur – ELLIADD Laboratory. She holds a PhD in Information and Communication Sciences. Her research interests include socio-technical devices and (digital) mediations in the city, visual methods and modes of transgression and memory in (urban) art.

Black and white headshot of Laura.

Cover image (top and bottom): Julieta Longo & Digit / Better Images of AI / CC BY 4.0

💃🏽 Behind ‘Digital Nomads’: context, clicking cursors, and choreography

Three of Yutong's (the artist) images from her 'Digital Nomads' collection are stacked on top of each other on the right side in a pane. On the right, the text 'Context, Clicking Cursors, and Choreography' is in black with 'Behind Digital Nomads' in italics. Beneath, the texts 'with Harriet and Yutong' in deep purple with a tag that says "behind the image series"

In this blog post, Harriet Humfress (a volunteer steward) explores Yutong Liu’s (artist) collection of “Digital Nomad” images which were submitted as part of the “Digital Dialogues” competition that we ran in collaboration with Digit this summer. Yutong’s images were awarded as winners in two of the categories. 

Harriet gives a creative reading of Yutong’s work drawing upon her experience as a fine art student at the University of Oxford. She highlights how the “Digital Nomad” series and Yutong’s illustrative approaches centre the context of artistic creation and how the body always precedes the digital. Harriet argues that these are two features that cannot be recreated in AI-generated artwork, making Yutong’s work so fitting to visualise how digital transformation is -and isn’t- changing our existing practices. 

I have a really clunky keyboard.

It’s bright green, and my gel extensions snag between the gaps, but its clack is so satisfying.

Within the frames are people bound to their office cubicles; beyond them, individuals work freely from diverse locations, connected through digital signals.
Beyond the Cubicle: Yutong Liu & Digit / Better Images of AI / CC BY 4.0

It almost looks like the keyboard in “Beyond the Cubical” (although my desk is much messier). I, too, have Post-it notes skirting my monitor, papers I’ve forgotten to read peek out sheepishly from under my trackpad, and my cables never behave, so I shove them behind the desk every time I sit down.

The undying sun hangs in the sky, as people gather around signal towers, working through their digital devices.
Digital Nomads Across Time: Yutong Liu & Digit / Better Images of AI  / CC BY 4.0 

Before any part of us is online, we are situated. ‘Across time’ makes that felt; the trench-coated worker feels the heat from his laptop building on his thigh, the man at the printer feels the low hum through his forearm and smells the warm, inky breath of the paper, and, across the desk, a woman’s shoulders tighten and her calves pulse after hunching over a laptop for too long.

Through signals from communication towers, people exchange ideas via digital transmission across different locations, accomplishing their work and building a digital community.
Digital Based Connection: Yutong Liu & Digit / Better Images of AI  / CC BY 4.0

Once we are situated, our habits spill outwards into the digital realm. Our scrolls, pauses, hesitation and clicks become data that reveal us to the system more than the system reveals itself to us. Alexander Galloway argues in ‘The Interface Effect’, that “the world materialises in our image”, and “Digital Based Connection” visualises this. Yutong’s character’s all navigate the same landscape of rolling hills and threaded cables, but they exist there differently; one runs breathlessly, with his laptop outstretched, while another lies back beneath a laptop turned parasol, nonchalantly bathing in its glow. The digital realm is less like a sealed second world, but like a map we make as we move. 

But, how do we get there?

The body precedes the digital

“So, we may arrive on screen as a cursor, but the work that gets us there is all shoulder, wrist, and fingertips.” Harriet Humfress

Yutong’s images insist that the body precedes the digital. Once online, our postures and clicks are compressed into a single point of agency: the cursor. Yutong literalises this proxy with her cursor-birds; these tiny, winged cursors keep the image in motion, reminding us that digital work advances click by click.”

“The idea of the mousecursor birds came from thinking about how almost every action we take on a computer involves the presence of the cursor. Without it, we can hardly do anything. So, I added them to represent the constant participation of the cursor in digital nomad work. Every “click” sets off or completes another task.” –  Yutong Liu 

Throughout her work, Yutong doesn’t anthropomorphise AI, she treats it almost as weather, as ambient infrastructure, or perhaps a climate. 

“To me, AI is in every screen. As long as there’s a screen and a connection to the internet, AI is already there—quietly influencing and facilitating everything in the background.”  Yutong Liu In ‘Digital Based Connection’, wires drape across the hills like isobars and laptops swell into oversized furniture and characters live together with the network, loosely tethered to an apple tree-router. For Yutong, these connections are her “way of illustrating how digital nomads transmit ideas within a shared space—both physical and virtual.” She imagines that “once these ideas accumulate, the tower transforms into an apple tree, with each apple representing a spark of human thought—shining, ripe, and ready to be shared.” The network is a climate we inhabit, not a figure we meet, which is why, for Yutong, AI doesn’t need a face at all, as it is present wherever a screen is lit.

The click-clack of my keyboard will never reach this file, but it will shape how it is written as my finger gets caught, and I spam the backspace, losing my train of thought. This is what Yutong describes as “traces of experiences”; digital files don’t stain, but Yutong’s drawing situations lodge themselves into her work. These traces are why her pictures feel lived in

AI and the ‘context debt

“Try to imagine unzipping your skin and stepping outside. What would step out? How would we exist without our senses?” Harriet Humfress

iPads and digital tools are Yutong’s main mediums, and offer near infinite ‘undo’ and precision, where the artist has complete control over the machine, and are sometimes marketed as ‘frictionless’ and ‘seamless’. This precision used to play an important role in Yutong’s process, but over time, she realised that “something was missing. Those ultra-clean, overly perfect lines started to feel rigid and lifeless” and she’s consciously shifted her approach: “I’ve come to embrace a certain level of unpredictability and imperfection in my work – because that’s what gives it authenticity and emotion”.

Rather than being nostalgic for paper, Yutong’s inclusion of these “traces” allows place, time, and the body to survive a frictionless tool.

“You can find traces of experiences in the visual element of my ‘Digital Nomads’ series. My inspiration comes from life itself, and I naturally project the life I’m living into the images I create. So even though digital images don’t physically create stains like paper does, I believe a sense of place can still seep in.” Yutong Liu

These “traces” are a breadcrumb trail. Follow it and you arrive at context.

In her Zine, ‘The Balance Between AI and Human’, Yutong muses on the role of the creative co-existing with AI. She recalls reading Adam Nemeth’s 2023 article and describes getting “chills”. What struck her was the idea that context lives in the gap between theory and practice, a space “for new narratives”.

“My art contained my context, a part that AI cannot replicate.” – Yutong Liu

AI may be able to describe or recognise the green of a lime, its bumpy skin, and sour taste, but it will never have the embodied knowledge of feeling the ache in your jaw or how saliva floods your mouth, or how the sourness contorts your face. This is the context gap that Yutong’s work operates in. A drawing made on a moving train carries a small tremor in its lines, or a green chosen under yellow café bulbs slips into olive, or how cursor-birds are read with the felt knowledge of strained eyes and a cadence of clicks. In her work, felt experience influences mark-making decisions.

Context also exists outside the body. Yutong describes how “context is also deeply rooted in cultural background […] humans can pick up the real meaning behind someone’s words through micro-expressions or subtle gestures”. Context is a kind of residue that no dataset can convincingly simulate, “something AI cannot currently understand”.

When this residue is thinned out and replaced with set definitions and statistical averages, images read as uncanny or empty. Yutong’s work explores the pushback to AI, and how this is more than just a “new moral panic”. It’s a reaction to context debt.

“The powerful rise of AI has instilled fear in many people, especially designers. […] Many fast-production, culture-less, story-less, and unoriginal companies have started laying off employees, preferring to pay AI companies to save on labour costs”. –  Yutong Liu

We have seen moral panics before, and every generation thinks the next is growing up lazier, more dependent on shortcuts, and dangerously unconcerned with craftsmanship. But this cycle feels different this time, something deeper than generational bitterness. Photography and Procreate disrupted traditional expectations for what counts as “real” art, and AI takes this to the extreme by obscuring and displacing authorship and creating without emotional memory or intention.

“It’s precisely this emotional and sensory presence that prevents human-made art from feeling empty. AI- generated work is the product of code and data – produced at speed and lacking in lived experience or authentic emotion.” –  Yutong Liu

Look again at the apples ripening on the router-tree, and the tiny corsor’s commute across the sky. Her metaphors feel lived in and handled and funnelled onto the glass of her iPad through the gripping of a stylus; “even with machine learning, AI can only remix what already exists, whereas human imagination is limitless”.

“Sometimes, the images generated by AI look good at first glance, but when you examine the details, they fall apart. They feel lifeless, soulless. It’s not just the vacant expressions in the characters – it’s the outlines, the brushstrokes, the composition. AI tries so hard to be ‘perfect’ that it ends up over-polished, almost sterile”. –  Yutong Liu 

Despite this sterility, Yutong doesn’t swear off AI or sermonise about its sins. Within her process, she treats AI as a tool and tries to “maintain a balance”, as she doesn’t want her work to “carry a strong AI shadow” but wants her ” audience to see what technology can help us achieve”. The sterility of AI often promises a neat and tidy input-output perfection, but this tidiness can’t stretch further than theory or reach out to context.

Loading up a chatbot, the input bar glows and the cursor blinks, and just out of rhythm to the clunky keys, but mimics the metronome of the typewriter-style loading of a friendly and reassuring response. It’s hard not to feel spoken to. Yutong describes how she “often imagined there was someone behind the screen who could understand me”, but in this supposed collaboration, prompts get nudged, rephrased, synonyms are traded, weights and models are adjusted, undone, redone, and the system obliges in its endless blank obedience. For Yutong, this “feels like an argument, but a very one-sided one. I was the only one talking, while the AI simply followed my instructions obediently – like a submissive assistant with no opinions or boundaries. No matter how much I ‘argued’ or tried to refine the prompt, there was always a disconnect between what I envisioned and what the AI produced.” After a dozen rounds, the almost-right images seem to pile up all glossy and neatly packaged like supermarket meat, but opening them up reveals this ‘conversation’ to be a monologue.

The system appears to understand, but what comes back seems too neat and strangely weightless, and it’s hard to name why. Try to imagine unzipping your skin and stepping outside. What would step out? How would we exist without our senses? Yutong dragged AI frameworks through the screen and into the room, in workshops to act out AI’s rules; ” I used to believe that AI only existed within computers, networks, and screens” but in these workshops “We explored AI through embodied exercises, like prompt-based drawing games or even “Pictionary”-style activities, where one person gives a prompt and another interprets it visually. These exercises helped us dig into the underlying logic of how AI works—and more importantly, how it differs from human output”. The workshops allowed participants to step into the input-output logic with their whole bodies, simulating image generation by hand.

“By investigating AI from a human, physical standpoint, I began to understand more clearly why its outputs often diverge from our expectations, even when we think our prompts are clear. Stepping away from the screen and into embodied, collaborative spaces made the learning process more playful, surprising, and insightful. That’s why I now find real value in exploring AI through workshops—it deepens my understanding in ways a purely screenbased interaction can’t.” –  Yutong Liu

Embodying AI as Human-Led Choreography?

“One, two, one, two, the prompt is the cue. The AI answers with plié, jeté, toes pointed and shoulders back, cleanly executing what has been drilled into it. Yutong leads, and the AI responds with the steps it knows. But what if we fed it something new to dance to?” –  Harriet Humfress 

For Yutong, the act of embodying AI changed how she thought of AI within her process, as it allowed her to “access ideas and insights [she] wouldn’t have reached through screens alone. It gave me new ways to feel and think about what AI is and what it can do. AI has sparked a lot of inspiration and critical thought for me, just as other digital media have also shaped how I generate ideas and interpret the world.” From here, creating with AI seems less like a collaboration and more like a human-led choreography.

Yutong gives a name to the choreographer: the AI Feeder.

In the last pages of her Zine, Yutong sketches a pragmatic job description for her imagined role of the AI Feeder: contracted artists feed models with tightly curated images, then intervene and correct where the machine falls short, and then use Nightshade (pixel level poisoning that preserves the appearance of images but blocks re-training) on the outputs so they can’t be scraped back into the system. An AI Feeder weaves situated thought and context into the data, embedding what an AI cannot produce on its own, but can be made to follow.

“Illustrators with strong personal styles enter into contract-based collaborations[… ]The company compensates them[… ]The artists then modify parts of the images that do not accurately convey the intended information[… ]Subsequently, the company employs Nightshade[…] to protect both the company’s interests and the copyright interests of the illustrators.”  Yutong Liu 

The AI Feeder’s process is less like prompt alchemy and more like rehearsal direction, marking the downbeat, setting constraints, rephrasing, and cutting. Many artist spaces demonise AI, but Yutong provides us with a radical future-facing redirect by prioritising human judgement and artistic integrity in a space where AI can often feel inevitable. She reminds us that ” AI can only generate based on what already exists. But the human mind can drift into unreal, even irrational spaces, and return with ideas no one else could have imagined. We can invent things that don’t yet exist. And I find that endlessly powerful”.

“We as humans have the power of choice, and that’s why I’m not so afraid of AI. Because I have a choice – I can choose to use AI or not in my creative process. As an illustrator, I can choose from various materials – pencils, watercolours, crayons – to assist me in my creations. In this process, any imperfect human stroke of the brush will create a different existence. In comparison, AI can only be chosen.”  Yutong Liu 

By the time I have finished writing this, I’ve picked off all my gel extensions.

My keyboard feels faster and slipperier now that my nails aren’t snagging, but I still mis-typed “extensions” three times. Backspace. Backspace. Backspace.

No part of this digital stutter will appear on the screen, but it shapes the sentence anyway, just as plane turbulence skews Yutong’s curved lines in ‘Digital Based Connection’ or a shaking subway carriage misplaces a cursor bird in ‘Across Time’.

This is what ‘Digital Nomads’ so cleverly depicts; even when digital landscapes feel seamless and glossy, they are always led by the body, with a slide of a stylus or an awkward left click. The risk here isn’t that AI will replace artists, but that we give up our context. Yutong’s process resists this both through critique and through her attention to rhythms, gestures, locations, and feeling. AI might mimic or remix style or design, but it cannot feel the clack of the keys or know what it means to mistype a word three times and try again. 


About the Digital Dialogues Competition

In April, the ESRC Centre for Digital Futures at Work and Better Images of AI launched a competition to reimagine the visual communication of how work is changing in the digital age. We received over 70 images to the competition from illustrators, artists, researchers, graphic designers, and photographers from all around the world, including Brazil, Hong Kong, Lebanon, France, Uganda, Argentina, Peru, Ireland, the US and the UK. The submissions thoughtfully challenged the dominant stock imagery used to depict digital transformation at work by offering more nuanced, inclusive, and grounded visual representations.

Yutong’s image ‘Digital Nomads: Across Time’ received the Grand Prize, the highest ranking award in the whole competition. Her other image, ‘Digital Nomads: Digital-Based Connection’ was also awarded in the top winning category. 

About the author

Harriet Humfress is a London-based undergraduate studying Fine Art at St Edmund Hall, Oxford. Her research explores popular beliefs and myths around AI, and how these ideas of anthropomorphism heighten anxieties around embodiment and labour.  Her work covers sound and video installations along with small tactile sculptures that aim to both satirise and inform viewers about how these digital systems cannot be unlinked from human emotion and power structures. Her projects often begin with data collection through surveys and workshops to build an understanding of how people engage with AI in their everyday lives and these data sets then become the material for her works. Alongside her studio practice, Harriet’s writing and research blends both creative and critical approaches, with essays ranging from narrative-driven works such as “A chatbot walks into a therapist’s office” to co-authoring work with We and AI on challenging AI inevitability narratives.

About the artist

Yutong Liu is an award-winning illustrator from China, now based in London as a freelance creative. Her work has appeared in numerous publications and advertising campaigns for clients including The Orion Publishing Group Ltd, Ascend Design, The Alan Turing Institute × University of Edinburgh, Better Images of AI, HiShark Edu, and more. Her illustrations have been recognised by prestigious awards and exhibitions such as the World Illustration Awards (WIA), 3×3 International Illustration Awards, Applied Arts Illustration Awards, ING Discerning Eye Drawing Bursary, Beijing International Book Fair (BIBF), China Illustration Annual Conference (CIAC), the Trinity Buoy Wharf Drawing Prize, and Hiii Illustration Award. Guided by her creative philosophy—“With eyes wide open and heart unveiled—feel life, record its pulse, and embrace its wild beauty”—Yutong’s work captures moments that are both poetic and profoundly human.

Images stacked in cover image: Yutong Liu & Digit / Better Images of AI  / CC BY 4.0

Other posts in the ‘Behind the Image’ series

https://thistle-oriole.pikapod.net/%f0%9f%aa%84-behind-the-image-with-minyue-from-kingston-school-of-art/
https://thistle-oriole.pikapod.net/%f0%9f%91%a4-behind-the-image-with-ying-chieh-from-kingston-school-of-art/
https://thistle-oriole.pikapod.net/%f0%9f%92%ac-behind-the-image-with-yutong-from-kingston-school-of-art/

Better images of AI on book covers

A collage of 8 different book covers of books about AI which are discussed in the blog post. In the centre, separating each row of 4 covers, the text reads: "Better images of AI on book covers?" "book covers" is italicised to emphasise the content of the blog.

We’re often told not to judge a book by its cover. And yet, a cover is often the reason why a reader first picks up a book. A book’s cover design is the window into its story and the author’s intentions. For Better Images of AI, in the context of books about AI and technologies, it’s refreshing to see covers that go beyond unhelpful norms and stereotypes such as tropes of robots, glowing brains, and unnecessary (white) men in suits. 

In this blog post, we share insights from Chrissi Nerantzi on the decisions behind the cover of the open-sourced book ‘Learning with AI’. We also reflect on the significance of book covers, highlighting some examples of covers that have featured “better images of AIwith reflections from our volunteer community.


‘Learning with AI’ – Considerations Behind the Cover 

‘Learning with AI’ is an open-source book from the University of Leeds. We spoke with Chrissi Nerantzi, part of the project team about their choice to use Ariyana Ahmad’s illustration ‘AI is Everywhere’ for the cover of the book. 

For the team, the choice of cover was about more than just visual aesthetic. It was about reflecting the collaborative and collective nature of the book itself. Initially the team were drawn to the idea of a collage since the team have used these for some of their other open books (see for example here). Collages can capture multiple perspectives, textures, and approaches, much like the student voices incorporated throughout the book. 

Ahmad’s illustration, while not a collage, achieves a similar effect. Its black-and-white style depicts diverse scenes of AI’s impact, from data analysis to agriculture, reflecting the different contributions from students who write about the use of generative AI in their studies. 

“I looked through the wonderful artwork from the Better Images of AI library and could see some of our collective thinking reflected in many of the visuals. I felt that using one of these for our book cover would be a perfect fit. We selected and agreed to use Ariyana Ahmad’s artwork “AI is everywhere for our book cover.” – Chrissi Nerantzi

Another key factor was openness. The images in the Better Images of AI library are open-source, freely available under Creative Commons BY 4.0 (read more here). This mirrored the ethos of Learning with AI which is a living, collaborative resource developed by students, academics, and the public together. The open licensing allowed the book to embody its own values of collaboration, accessibility, and incremental learning.

“We routinely build on work by others, remix, reappropriate, and evolve it. We are inspired by what we see, experience, discuss, read and debate about, play and experiment with, our mistakes and failures, and use our imagination, ingenuity and resourcefulness to come up with new and exciting creations that can be experiences, processes and products that add value in some way. Creativity can’t happen without openness.” – Chrissi Nerantzi


The significance of book covers 

Every author wants a cover that communicates both the passion behind their work and a sense of what the reader will discover inside. But as Anne Jordan and Mitch Goldstein write in the Stanford University Press blog, a good cover should also “reward the reader” by offering a touch of mystery, something that allows space for personal interpretation and grows in meaning as the text unfolds. By this, they mean that book covers should not be overly prescriptive about what the author intends to communicate, but actually, depth in an image enables readers to still resonate with the cover as their journey and experience through the book might change, challenge preconceptions and evolve with the narrative.  

“A good book cover should also reward the reader – there should be a little bit of mystery to allow for personal interpretation, and enough depth in the image so the reader’s experience of the cover changes and grows as they make their way through the text.”  – Anne Jordan and Mitch Goldstein 

In ‘The Art of First Impressions’, Chip Kidd makes a similar point. Sometimes, clarity in visual communication is really important – for example, for street signs or instructions. But he argues, “mystery is an extremely powerful tool” when you want to grab attention and invite deeper engagement. In the context of AI, mystery can be particularly valuable, since oversimplified stereotypical imagery hinders the reader’s ability to reflect on the subject, reinforcing the illusion of pre-determined futures involving AI. 

“You should be mysterious when you want to get people’s attention and hold it, when you want your audience to work harder.” – Chip Kidd

An example of this balance between clarity and mystery is the cover of Nick Srnicek’s book ‘Silicon Empires’ which uses GPU shot etched 5’ by Fritzchens Fritz from the Better Images of AI library. The image grounds the book in the material realities of AI, while also evoking a sense of wonder through its rainbow hues, a marked departure from the usual “deep blue sublime” that is usually embedded within stock images of AI. 

Srnicek’s book explores the geopolitical economy of AI, so this cover aims to show how high-level strategic moves between governments and corporations have material impacts on the environment and the world that we live in. Srnicek could have chosen a stereotypical visual of AI (white anthropomorphised robot, human brain, or blue holograms), but in choosing an alternative image, it made it clear that this book was making a different statement about the development of AI. Even if readers might not immediately understand the cover of this book, this might be half the point to entice readers to investigate the book in order to decode it – relating to the idea of mystery which was explored above.

“Artists and communicators are well aware of the power of images. They can inform, inspire, draw attention, or simply entertain. Images that are misleading or inaccurate are equally powerful, but with potentially damaging consequences: they can misinform, limit the imagination, or divert attention from pressing issues.” (Dihal and Duarte, 2023, 5)

Another example of a book that has featured one of the images from our library is The Ethics of AI: Power, Critique, Responsibility’ by Rainer Mühlhoff. This book serves as an accessible and critical interrogation of the effect of AI in society, with a focus on the interplay between AI and power. This book moves away from attempting to predict the ways in which technology could lead to existential risks and the end of humanity. Rather, The Ethics of AI is grounded in the ‘now’ – much like the Better Images of AI library! Mühlhoff considers the social-normative behaviours, power structures and other elements of society, based upon case-studies, to help people understand how a composite of personal responsibility, policy and an understanding of the risks present are vital to helping AI go well.

The cover uses Anne Fehres, Luke Conroy and AI4Media’s image, ‘the Hidden Labour of Internet Browsing’. This image explores the hidden labour behind our everyday use of AI. The use of this image clearly works for Mühlhoff’s book, as it has the perfect mix between the ‘everyday’ and the hidden structures at play, these are embedded within the sliced and slanted crosswalks across the cover. Not only visually striking, this image also meets Goldstein’s assessment of what makes a good book cover, adding some mystery that will reward the reader as they read since the themes will become clearer the more they understand of Mühlhoff’s position.

Of course, the images in the library have not been created to cater for specific books in mind (though some have certainly been inspired by books!). Still, we are always happy to see them used in this way, especially by authors who may not have large budgets or the support of a major publishing house. 


The Covers of Books about AI 

Below, we showcase a selection of other book covers that use visuals of AI that challenge common tropes. Each example demonstrates how visual choices can reinforce the themes of a book and the author’s intentions. Thank you to some of our volunteer stewards for their collection and commentaries on these covers: Beckett LeClair, Laura Martinez, and Liam Palette. 

Technology is Not Neutral: A Short Guide to Technology Ethics by Dr Stephanie Hare

The black and red cover shows a face with the focal point being the eyes. One eye is masked by the back of a camera cell phone camera which is held in front of the face, partially covering it. The human eye and "eye" from the phone back camera reflect a face.

This 2022 book by Dr Stephanie Hare explores how we can create and deploy technologies to minimise harms and maximise benefits. It directly challenges notions of neutral, amoral and unquestionable tech, instead inviting us to consider how wider contexts feed into the ethicality of our use of technologies. The bold colour scheme immediately grabs the viewer’s attention. The provocative imagery of devil horns and a ‘watchful’ device conveys a core argument – that ethics are influenced by a technology’s very designers and users – in a remarkably simple way. 

Human-Centred AI by Ben Shneiderman 

The cover shows lots of mini environments which protray the relationship between technology and humans. For instance, in onem, there is a human interacting with an interactive screen, individuals watching TV, at work, or in factories.

This book focuses on the opportunities presented by AI and how we might capitalise on them through human-centred approaches. Shneiderman writes specifically about his choice not to use a visual with a harmful AI trope like humanoid robots, based on his belief that AI will not possess human-like capabilities like “two-legged mobility, five-fingered dexterity, and dominance of voice interaction”. In deciding on what the cover of his book should include, Shneiderman developed guidelines on what he wanted: images of people, diverse people, expressive human features, technology connecting and empowering people, and natural world representations. 

Communicative AI by Mark Coeckelbergh and David J. Gunkel

The cover background shows a tea-stained old effect and the image is of a Ancient Egyptian Pharaoh typing on some machinery - the image is line-drawn with some blue features.

‘Communicative AI’ takes a critical introduction to LLMs inspired by philosophy, history of ideas, linguistics, and communication theory. Through exploring LLMs in relation to these disciplines, the authors confront longstanding debates about language, consciousness, truth, authorship, and writing. The choice of book cover is especially interesting and could be read as an homage to Plato’s myth of Theuth and Thamus from the Phaedrus for those familiar with Ancient Greek philosophy. Here, Socrates questions the invention of writing, which he argues, in comparison to dialectic discourse, weakens memory and offers the appearance of wisdom without true understanding. 

In the context of LLMs and the critical approach that Coeckelbergh and Gunkel take in their book, this historically inspired cover is fitting to modern day debates about whether LLMs are weakening our own critical thinking abilities and limiting our ability to achieve genuine understanding. The use of a historical cover adds to a sense of mystery and appeal since AI is usually represented in ways that try to present it as “new”, “innovative”, and “magical” – this book cover takes us back to debates we’ve long had throughout history, stretching back to Socrates’ questioning of the invention of writing over 2000 years ago. 

Feeding the Machine by James Muldoon, Mark Graham and Callum Cant

The background of the cover is a standard city scene. The top half is the sky with the text "FEEDING THE MACHINE" in black text and "THE HIDDEN HUMAN LABOUR POWERING AI" in pink. The bottom half shows blurred figures and objects with bounding squares with labels such as "raw material", "worker" and "infrastructure" in pink yellow and green.

Based on years of fieldwork research, and through the story of seven workers around the world, Feeding the Machine, by James Muldoon, Mark Graham and Callum Cant, shows the extractive ways in which AI system are powered, mostly by humans workforce, resulting also in the concentration of power of tech company and elites. The authors call on us to demand a fairer digital future:

If this book could be distilled to a single message is that we, human beings, are the often-hidden force that powers AI – both physically with our labour but also intellectually through AI ingesting and synthesising our collective intelligence” (p. 220). 

The cover image from Shutterstock is an excellent choice that engages with the content. It reflects the process of AI data labelling and AI-generated annotation. It could depict the process of manually assigning labels or categories, which often involves precarious global workforce. It could also represent the tags already added to a dataset to train machine learning models in image recognition, thereby demonstrating how public spaces are repeatedly labelled and surveilled. It brings together the process and the results. You have three categories: raw material (trees), workers (ironically, most of us already fall into this category, or will do. Are we really just a workforce?), and infrastructure (pretty general to fit in?).

Public Data Cultures by Jonathan W.Y. Gray

A collage of patterns with earthy tones, the patterns are quite geometric like in the style of decorative tiles. There is a yellow text box with the title of the book 'public data cultures' in white.

‘Public Data Cultures’ explores the practices and cultures of how data is made public in the age of the Internet. Typically, the language is saturated with extractive and industrial metaphors: “data mining”, “data harvesting”, “data pipelines”, and the common phrase, “data is the new oil”. Gray’s book aims to centre the idea of public data as a networked cultural material through a more critical and creative interrogation of what it means to make data public.

Visual representations of data, especially those used to reflect AI training datasets, show data in vast holograms, giving the impression that data is abstract, objective and impersonal. Gray’s choice of cover shows that data is relational, embedded in culture, and embodied. The colour scheme of earthy tones also reflects associations with natural materials which is interesting given the environmentally-themed metaphors mentioned at the start. However, instead of Gray using these tones to the promote the idea that data is a resource to be consumed with economic value (like land), the cover could be hinting more at the ideas of solidarity, community management, and stewardship reflected in our environmental ecosystems.

Attributing Better Images of AI

A screenshot of the cover of the Attribution Guide alongside the text: "Tips and tricks to attribute Better Images of AI in our new guide!"

In this post, we discuss how to correctly attribute images downloaded from our image library. It’s the legal requirement under which the images are made freely available, and we think it’s only fair to recognise the community of volunteers and artists who made it possible! Our Attribution Guide includes tips to ensure that you are attributing Better Images of AI’s images without violating the terms of the Creative Commons (CC) BY 4.0 license, and also tricks on making attribution text look best in different formats. If you’re a user of our images, you might also find some interesting examples, and be able to send the Guide to others who might need it.

All the images in the library are available to freely download, even for commercial purposes, via a CC BY 4.0 license. CC is a non-profit that provides open licences that allow creators to share their work under a standard set of terms and conditions. The CC BY 4.0 license gives users the maximum freedom to freely share, use and adapt images in the Better Images of AI library, including for commercial purposes.

However, this is upon the condition that users include the correct form of attribution every time any of the images in the library are used.

Failing to attribute the image violates and terminates the CC license under which the images are provided. We’ve made it easy to include the correct attribution on our image cards which offer a custom plain text and HTML copy and paste attribution.

A screenshot of an image card from the library with the copy and paste attribution functionality highlighted in a yellow box with an arrow pointing which states "attribution made easy!"
Image card with copy & paste attribution highlighted in yellow

Typically, the correct form of attribution follows the following template: Artist name [& partner if applicable] / https://betterimagesofai.org / https://creativecommons.org/licenses/by/4.0/. Sometimes, users fail to include the hyperlinks to the CC BY 4.0 licence and/or Better Images of AI (reasons why this is important are discussed below). Furthermore, depending on how the image(s) is being used or the display, the attribution might take various forms or appear in different places.

As a result, we’ve created a simple guide to provide you with information and tips on how to attribute Better Images of AI. The guide is a live community working document which we will continue to update as we find more examples and learn best practices about attributing Better Images of AI. Do not hesitate to get in touch if you ever have any questions about attribution or feedback on the guide (info@betterimagesofai.org).

The Attribution Guide includes some quick top tips to attributing Better Images of AI via CC BY 4.0 licenses and a breakdown of examples of attribution best practices depending on display, e.g., social media, presentation slides, blog posts, banners, events, in-print, newsletters, and physical exhibitions.

The Attribution Guide also provides some common examples of insufficient attribution. We’ve outlined them on page 11 to help avoid any easy mistakes.

Why is attribution important?

Attribution is a legal requirement under the CC BY 4.0 license that the images in our library are available under. This licence allows the free use of images, but only if you give an attribution in the correct format which includes a link to the licence, and an indication if any changes that were made. Failing to attribute violates and terminates the CC license under which the images are provided. In particular, providing a (hyper)link to the CC license is important so that others can see the specific terms and conditions under which they are allowed to use and reuse the work.

Attribution is also about fairness and respect for the creators who contribute to the library, frequently by donation. Providing the artist names ensures recognition for creators and helps others to find their works. The purpose of our library is to improve the representation and inclusivity of AI visuals, so by linking to our library, we want to allow others to find our resources, enabling us to challenge the harmful visual tropes of AI by encouraging greater use of alternative images.

As a non-profit, we’re always very grateful when users provide a shoutout to our library to let others know that we exist and the purpose of our community. We are run entirely by volunteers, so we rely on word-of-mouth and the brilliant visuals from our artists to gain a greater presence among the sea of harmful images that feature human brains and humanoid robots pushed by profitable stock image companies.

Is the CC BY 4.0 license the best to use?

The CC BY 4.0 license has been drafted to be internationally valid, and it provides users with the maximum freedom to use images, provided that they include the correct attribution. We believe that this license offers an appropriate balance between protecting creators’ rights and enabling us to pursue our goal of challenging harmful AI tropes reinforced by dominant imagery by creating new visuals to represent AI.

As part of the goal of our community, it is important for us to make the images in the library as accessible as possible for those communicating about AI, such as journalists, marketers, educators and researchers, so they can use alternative images instead of dominant stock imagery, or just explore them as inspiration for more helpful and diverse representations of AI.

This means that we have chosen the CC BY 4.0 license, which makes the images freely available, even for commercial purposes. Commercial entities are part of the main drivers of AI hype and misleading AI tropes, so offering free resources makes it more possible that we can improve the public understanding of the uses and implications of AI.

The CC BY 4.0 license requires users to include the name of the artist in the attribution which we have seen to provide recognition to the creators and helps others find and support their works. Despite common misconceptions, the CC licenses also do not require artists to relinquish the copyright in their work; these licenses are a way to allow others to use your work under specific conditions while the creator retains copyright.

We understand that some artists will (rightly) not want their work to be offered freely for commercial use in our library. We support these artists and their decision to be adequately compensated for their work, time, and efforts. However, in accordance with the objectives of our library, we have decided to make the images widely available for all uses and purposes. We are always open to discussions about how we can better respect the rights of artists and their work, so please get in touch if you have any ideas.

Disclaimer

Any of the information provided in the Attribution Guide does not constitute legal advice. The Attribution Guide has been created by our volunteer community and it serves as informational guidance about our understanding of how to attribute the images in our library in accordance to the CC BY 4.0 license. The Guide is a working document and will be continuously updated as we learn best practices and spot new, innovative ways of displaying our images.

If you spot any mistakes, errors or have suggestions for ways to improve the Attribution Guide, please do get in touch with us by emailing info@betterimagesofai.org. We’d love to hear from you.

Finally, we would like to express the greatest gratitude to Stefan Kaufmann from Wikimedia for providing invaluable comments and thoughts which led to the curation and development of the Attribution Guide.

🌳 ‘Behind the Forest, There are Trees’: Nicole in conversation with Laura

On the left is Nicole's image which shows a single tree silhouette is composed of a mosaic of an array of small, colourful images of various types of trees in a collage. The images are projected onto a cutout shape of a tree and overlap in vibrant layers. The tree sits against a dark forest background with a white drop shadow which creates distance between the tree and the forest behind it. The base of the tree features a bright green grass wrapped around the trunk. On the right, the text reads: 'Behind the Forest, there are Trees', 'Nicole Crozier' in conversation with Laura. In a blue text box, it reads 'Behind the Image Series'.

In this blog post, Laura Martinez Agudelo (one of our amazing volunteer stewards) interviews Nicole Crozier, the artist behind the image ‘Seeing the Forest for the Trees’ which was submitted as part of The Bigger Picture collection. The post explores how the image criticises, but also reflects on, the development of generative AI and what these new technologies mean for artists and the art industry. Nicole hopes the image can challenge the AI hype and misconceptions about how AI-generated art is created. 

You can freely access and download ‘Seeing the Forest for the Trees’ from our image library here. 

From roots to branches

Nicole is a visual artist originally from Ottawa and she currently lives in Montreal, Quebec. She is studying for a Master’s degree in Fine Arts (Painting and Drawing) at Concordia University, and she is working hard for her thesis defence in September. Prior to moving to Montreal, she lived in Toronto for seven years, where she developed her practice and worked as an arts manager, primarily in the dance world. She decided to enroll in her current programme in order to dedicate more time to her artwork. 

Art has been a part of Nicole’s life since childhood: “I first started painting when I was in grade 9. It was for me a means of expression and also… an escape from bullying at school”. While at high school, she wanted to be a journalist, but her art teacher convinced her to go to art school, which is how she ended up on this path. Nicole completed her undergraduate degree in Visual Arts at the University of Ottawa, graduating in 2013, during which time she primarily explored two artistic approaches: painting and photography. Since then, she has focused on both, “moving back and forth between them”. 

She knows that her technical skills lie mainly in painting, but she admits that she is “a slow painter and it can be frustrating sometimes”. At the same time, she finds that it is also a great quality: “… just slowing down, taking time and engaging in a dialogue with the painting. With photography, she feels the opposite because the process provides a quicker response between her and the subjects.

Besides, she is interested in playing with contrasting ways of reception of her artwork: “creating images that fall between two effects, for example seduction and repulsion… When you see an image, you may at first be attracted to something within the picture, and then repelled; not quite sure what you are looking at… I like working in between spaces, between two poles”. Let’s see how this approach converges with the idea of creating better images of AI. 

The Bigger Picture Workshop

Nicole doesn’t usually explore AI contents in her artwork. She came across it in The Bigger Picture workshop that she attended through Better Images of AI, which is how she heard about the motivations behind the project to create more realistic images of AI: “I was intrigued by the prompt, given my general interest in archetypes and in understanding the world through photography. We live in a hyper image saturated society and think about ourselves so much in relation to photographs”. 

She argues that, in using photography, we “view our daily lives through the camera lens, synthesizing our selves, environments, and social conditions into iconographic ways of seeing the world around us”. This idea crosses over with her first approach of AI image generators: “as an artist, that’s the main way I interact with AI: through text to image generative AI programs and trying to understand how they work and are affecting the arts industry”.

Collage and visual correlations

Although her work has changed a lot over the years, Nicole has always had an aesthetic working methodology and interest in collage. For her, collage is itself a way of creating. She loves to elaborate physical collages with paper and then photograph them. This is evident in her illustration Seeing the Forest for the Trees

In her art practice, Nicole often starts with “a 3-dimensional collage or maquette that I light and then photograph. I like working with cut paper and finding craft supplies that have a textural quality that tips the viewer off that what they are looking at is handmade, that draws them in. I create the illusion of space and then the camera flattens it: a multitude of images I’m combining compressed into one photograph. Which is also a similar process of synthesis used by generative AI in response to text prompts, so I think there is also a visual correlation between the two”

This is one of the reasons why Nicole became interested in the process of AI image generators as “‘sophisticated’ collage makers”, the material conditions of production and how many visual inputs produce one output. She also compares this process to the use of collage by artists in art history, such as the surrealists and how they used chance to access parts of their subconscious when making art. 

With AI (text-to-image or image-to-image models), you can reuse the same prompt and receive a different image each time, but the ’emotional’ and ‘creative’ part of the process is removed. These kinds of AI images show no signs of the subconscious role in creating: they are dead images, most often based on data poached from other artists without consent…”.

The machine would only be able to reproduce the data used to train it. For Nicole, the process of imagining and exploring visual representations is an essential part of creating images. What was then the idea behind Seeing the Forest for the Trees? 

The source of inspiration

A single tree silhouette is composed of a mosaic of an array of small, colourful images of various types of trees in a collage. The images are projected onto a cutout shape of a tree and overlap in vibrant layers. The tree sits against a dark forest background with a white drop shadow which creates distance between the tree and the forest behind it. The base of the tree features a bright green grass wrapped around the trunk.

Nicole Crozier & The Bigger Picture / Better Images of AI / CCBY-4.0

When Nicole was conceiving the image, she was thinking about how to illustrate her understanding of the way AI generators ‘create’ images. The tree-forest relation was a good subject to work with because it is a universal metaphor for the individual versus the group, one image versus a composite image. 

Large language models and generative image models compose images by training on hundreds of thousands of data and metadata items. The process of generating the final image is invisible to us, and the final image could not exist without the multitude of images that were (statistically translated) and put together. I don’t know if I was fully successful, but my contribution was an attempt to express this idea visually.”

For Nicole, the choice of the tree-forest metaphor is also related to how we position ourselves socially as individuals: recognising ourselves as individual trees within the forest”. 

The social component of AI systems is also intrinsic: it is hard not to think about AI through the lens of how we operate in society, because we always approach things from a human perspective, and the tree-forest metaphor is one that maybe we can all easily understand”. This is why Nicole wanted to create a tree made of other trees: It’s a forest inside a tree! And that’s where the idea first came from”. 

She has also been working with handmade maquettes for a long time and she wanted to use this method and materiality to create the image including the human process of making it. Afterwards, she came up with the popular phrase that became the title of the image — a perfect match to reinforce the meaning! 

Now let’s take a closer look at the image to see how it was put together.

The visual and material composition

First, Nicole cut out the image of a tree from a white piece of paper. Then, she created a small scene with it in a box and projected the image of the collage of trees onto the scene, using a Photoshop mask. 

An image of Nicole in their creative environment. They are sitting down next to a desk, surrounded by art equipment and tools.

Picture of Nicole in their creative environment

For the visual composition reflected on the large tree, she selected some images, free to use and without copyright restrictions, from Unsplash. She chose these images based on formal considerations: “I was trying to find images of trees with a lot of empty space around them so that you could see just one tree. The idea was to find archetypal images of trees”. 

Finally, she photographed the whole composition and did some extra manipulation in Photoshop: “it was a technical choice to achieve a well-balanced image”. 

The trees were chosen for their metaphorical relationship with nature and technology as well: “There are so many ways in which we can connect the idea and the visual representation of a tree with environmental and technological concerns, within the dynamic of ecosystems, understanding the branches of a tree as a network – it’s almost cliché, but I think it works really well for this topic”.

Questioning AI hype, sustainability, and the inevitability narrative

Even if Nicole doesn’t think she will make any more artwork about AI imagery specifically, she is currently considering the philosophical aspects of this subject, as well as the ethical issues of AI systems in our society: 

I have deep concerns about AI technology in general, its impact on society and whether it will be mainly beneficial or malevolent, and particularly in relation to climate change. This ethical question extends to myself and why and how I make art too. Honestly, I try to avoid using AI as much as possible…”.

She also mentions the importance of the Better Images of AI project: “I think Better Images of AI is trying to move beyond the black and white binary of imaging AI as either benevolent or malevolent. In a hyper-visual world, they are trying to provide more nuanced images to promote better visual literacy around how AI systems actually work and how they are being implemented in our society”. 

Nicole knows that there is a lot of propaganda and hype surrounding AI, encouraging not only a blindly positive attitude towards it, but also the idea that it is inevitable: the dominant discourse is that AI is here whether you like it or not. The general discourse seems to be ‘if you don’t embrace or adopt AI, you’ll be left behind in the job market’, and I think that scares some people”. 

This is obviously a turning point from many different angles: technological, cultural and environmental… it touches everything. Also, many AI systems are like black boxes. We don’t fully understand the nature of the inputs and processes that generate the outputs”, not even all humanity’s labour behind. 

Nicole thinks that the discourse of inevitability is irresponsible. It neglects real risk, harms and our individual and collective ability of agency: “Corporations creating these AI systems should have a regulated responsibility to ensure they are only used in ethical and beneficial ways. Though given our current neo-liberal economic climate, in which some corporations have more power and wealth than some nation states, I’m not very optimistic about the likelihood of our ability to employ these tools in ethical ways. 

From my understanding, it’s just an intensive version of a colonial regime, like: “let’s gather as much information as possible about all aspects of human experience, with limited compensation – if any –  to those whose data was harvested, and see what we can extract from it for profit for a limited few”. 

Nicole believes this approach is environmentally expansive and extractive, given that “the huge amount of energy needed to maintain these systems is something that most people think of as ‘invisible’, but it has real and concrete effects”. Having mentioned these issues, Nicole shared some other thoughts from the perspective of the art field.

What kind of art do we want?

During our interview, some quotes were proposed for discussion. These quotes came from the book The AI Con: How to Fight Big Tech’s Hype and Create the Future We Want, by Emily M. Bender and Alex Hanna (2025), and specifically from a subsection of Chapter 5 about ‘AI and Art-Making’ (p. 103-112). This book was also discussed at the latest We and AI Book Club monthly meeting. As a visual artist, Nicole loved the idea of sharing her thoughts about it. 

One of the quotes suggested to Nicole was: There are, to date, no synthetic media machines in any medium that are based only on data collected in a way that respects existing artists”, referring to AI systems whose training data includes your own art. 

Nicole said: “My understanding of what they consider to be a media machine are systems that show no respect for copyright and, while I agree with the general statement, I think there is a grey area here. I think creating your own dataset (based on your own past work or work you’ve received consent for or paid for), could be an ethical use of this technology. 

AI is reshaping creative practice and Nicole knows artists who are “exploring those systems as a way of creating art, by creating their own dataset with their own work”, but she believes that “the general processes AI image generators are based around are inherently the opposite of what art is supposed to do”. 

About AI ‘Art’, Bender and Hanna mention in their book an idea expressed by Dr. Johnathan Flowers in an interview for Episode 4: Is AI Art Actually ‘Art’? (Mystery AI Hype Theater 3000, podcast audio, October 26, 2022):the purpose of art is to signal a particular kind of intention and to convey a particular type of experience, and this is precisely what AI art lacks”. 

Nicole agrees with this idea and proposes that it is also useful to ask:

“Is this a type of art that we want to be creating in the first place? Is it culturally productive or regressive? Not in the sense of capitalist productivity, but… Is it actually helping or inspiring anybody? Even more importantly, is this a mirror that we can hold up to see ourselves reflected in?”. 

For Nicole “the medium is the message (quoting McLuhan). Maybe AI art is art, maybe it isn’t, but… Is it really what we need? The focus on whether AI art is art is a smokescreen. What is art? Sometimes, there isn’t even a word for it; it depends on the context, the creative practices and the culture”. 

Two other quotes suggested were: “Why should artists who spent years perfecting their skill be left to starve as a few technical experts who stole their work get rich off of it?” and “AI art generators are already being deployed in ways that disrupt the economic systems through which people become and sustain careers as working artists”. 

Nicole thinks that people working in what is sometimes called ‘traditional artwork’, such as creating art objects for galleries, seem to be less concerned about ‘AI art’ because they feel somehow ‘untouchable’: “collectors always want paintings and physical objects. However, artists in creative industries such as illustration, design and animation are feeling the economic effects of AI much more acutely, and I have a lot of sympathy for them and their jobs. Many artistic fields are being affected…”. 

She believes that there should be more critical regulation to protect those artists, their copyright and the cultural value of their work: “AI is further degrading the general public’s respect for these art forms. People often say ‘oh, my kid can do that!’ and now, with AI image generators, it’s the same idea, ‘oh, I can do that using text-to-image models’. At least for now, I think, we can still tell the difference between something made by the artistic motivation, intention and work of a person (including imagination, experience and artistic skills), and something made by using only an AI image generator. But I think the width of this uncanny valley will continue to shrink in the years to come…”. 

Despite the opacity and mutability of many AI technologies, and all the questions about the latent space in the scanning and statistical process of image visualisation, and the patterns for generation, Nicole concludes by emphasising the importance of ongoing learning and reflection on the applications of AI image generators, not only in art, but also in all professional fields. She encourages us to think critically, without being deterministic, and question “what we should accept or refuse”.

Huge thanks to Nicole for her contribution, and for sharing her insights about her artwork and the challenges of creating in the context of AI image generators today.  

About the artist

Image of Nicole who shown to be creating art, surrounded by creative tools and equipment like paintbrushes.

Nicole Crozier is a visual artist and arts manager based in Tiohtià:ke (Montreal-QC), with ties to Tkaronto (Toronto), born and bred in Adàwe (Ottawa-ON). Nicole holds a Bachelor of Fine Arts (University of Ottawa) and a graduate certificate in Arts Management (Centennial College).

About the author

Laura Martinez Agudelo is a Temporary Teaching and Research Assistant (ATER) at the University Marie & Louis Pasteur – ELLIADD Laboratory. She holds a PhD in Information and Communication Sciences. Her research interests include socio-technical devices and (digital) mediations in the city, visual methods and modes of transgression and memory in (urban) art.   

Headshot of Laura

Cover image: Nicole Crozier & The Bigger Picture / Better Images of AI / CC BY 4.0

Judging Visual Representations of AI: Dialogue, Difference, and Diversity

The title "judging visual representations of AI" is at the top of the image. Circle shaped frames of headshots of each of the images are below. The left features a decorative image of a woman working simultaneously as a delivery worker, remote employee, and caring her child, representing the opportunities and risks of work digitalization.

Recently, the ESRC Centre for Digital Futures at Work (Digit) and Better Images of AI ran a competition aimed at reimagining visual representations of digital transformations at work, including those driven by AI implementation. We received over 70 submissions to the competition from artists and creators from all around the world who created images that reflected the key themes from Digit’s research: digital adoption; digital inclusion; changing employment contracts and conditions; and digital dialogues. 

When designing the competition, it was identified that the judging panel would need to reflect a range of disciplinary and experiential perspectives to meaningfully assess the strength of the submissions which engaged with the social, political, legal, and emotional dimensions of digital transformation of work. In several cases, this required judges to draw upon their own positionality and experiences as knowledgeable individuals in their field, but also as the very people who are situated within the systems and dynamics that the artworks sought to represent or critique. The judges included an international panel of artists, data scientists, sociologists, lawyers, business experts, trade unionists and policy advisors working on the cutting edge of AI. 

In this blog post, we reflect on some of the choices that we made when we designed the ‘Digital Dialogues Art Competition’. We spotlight the panel of judges that came together to deliberate and score the entries into the competition. This blog post serves as a reminder of the importance of thoughtful and interdisciplinary judging panels, especially when the work being evaluated is as interpretive and subjective as visual imagery. We also highlight how projects like this can create space for new forms of conversation between disciplines, such as technology, marketing, and creative fields. 


Who judges and why it matters

In any competition, judging is inevitably shaped by individual and disciplinary values. In recognition of this, we placed considerable emphasis on curating a judging panel that included a broad range of expertise and experience. The Digit team reached out to their existing multidisciplinary community fostered during the undertaking of the research to  include artists, researchers and practitioners who are working at the intersections of technology, work, and society. The idea was to invite individuals who had different relationships to digital transformation at work, so that no single narrative or perspective would determine the judging. 

To guide the process, we also developed a scoring framework that the judges used independently to score the images. The criteria were evenly weighted across four elements: visual impact, alignment with the brief, originality and creativity, and communication of the research themes. Scores were collated from the judges and presented during the deliberation session, allowing everyone to discuss the correlations shown in the rankings of the images that were scored in advance. 

It was interesting to see how the conversations between the judges also raised deeper questions that reflect the epistemic tensions between different kinds of knowledge and disciplines. A salient example of this emerged in the panel’s conversation around one submission, “Wheel of Progress” which is shown below. The judges wrangled with the question: does the abstraction of an image obscure communication, or does it open space for interpretation and imagination about the image’s theme? 

Two workers running inside a scroll wheel embedded in a computer mouse, controlled by a giant capitalist hand.

Image credit: ‘Wheel of Progress’ by Leo Lau*

Jacqueline O’Reilly (Co-Director of Digit) reflected on the importance of having a range of images, some that might be more literal and some that require deeper interpretation to appeal to all audiences. Michael Luck (Deputy Vice-Chancellor of the University of Sussex) welcomed the ambiguity of the image, noting: “I like having to think and to look and to try and work out what’s going on in this”. Another judge, Nick Scott (Head of the Centre for Responsible Union AI) offered a nuanced view, appreciating the layered nature of the piece: “Yes, it is abstract. Yes, it is a bit more artistic. But actually, once you see it – and ‘get it’ – it is telling a very clear story”. 

“Wheel of Progress” demonstrates the nuances of judging visual arts. Better Images of AI is focussed on reimagining images which often requires us to step outside familiar stereotypes, engage with complexity, and explore the different ways that the impacts of AI can be seen, felt, and understood. 


Our judging panel and their reflections

The judging panel was composed of scholars, practitioners, artists, and individuals whose knowledge spanned art, AI, law, labour, and marketing. For many of the judges, the experience of participating in the competition was beneficial and offered a space to engage with research through visual means.

Several of the judges’ conversations during the panel also showed how the judging process prompted them to reflect on their own assumptions: asking whose experiences of digital transformation are prioritised and how visuals can challenge or reinforce dominant narratives. For artists on the panel, the dialogue with scholars and practitioners also offered a chance to see how their own creative methodologies could be expanded or recontextualised to reveal or reframe dimensions of research that are often overlooked. 

Below, we include short bios of each judge, alongside selected reflections on the value they found in the competition and the reasoning behind their decision to engage with the Digital Dialogues Art Competition.

Chanell Daniels

Chanell is the Responsible Technology Innovation Manager at Digital Catapult and Visiting Policy Fellow at the Oxford Internet Institute, University of Oxford. She was previously a Senior Manager in Community Safety at Depop and currently sits as an AI Advisory Board Member for OpenUK.

“With these images, there is an interesting ability to capture nuanced considerations and problems with AI use that can be very difficult to translate into text. This could be applied with how companies and their employees or other stakeholders are able to communicate the impact of digital transformation changes and the concerns that may arise.” 

Nick Scott

Nick brings over 20 years as a digital leader spanning non-profit, trade union and research organisations. At Unions 21 he heads up the Centre for Responsible Union AI, which has been set up to help unions navigate the impact AI and emerging technologies have on their staff, operations, members and mission.

“The union movement is rightly very focused on supporting workers through the impact of AI, from job changes to developments like algorithmic management. We’re looking at the other side – what are the challenges, but also the opportunities, for unions as organisations from AI? How can we manage AI to build union strength when it is most needed?”

Niels Bonde

Niels is a digital artist and his PhD research at the University of Applied Arts Vienna is on facial recognition. Niels’ work has been shown in installations in museums and galleries such as Stedelijk Museum Amsterdam, MIT List Visual Arts Center, Boston, ZKM Karlsruhe, PS1 MoMa New York, Malmö Kunstmuseum, Statens Museum for Kunst Copenhagen, Academy of Fine Arts Hanoi Vietnam, and Contemporary Art Centre Vilnius Lithuania.

“AI-generated images now have become much more convincing, and as a consequence of that we see a deluge of AI-slop where the content is generated by Chat GPT and friends’ harvesting of images coming from similar sources, generating similar content. This is in particular an issue in illustration, as this competition addresses. As a few prompts quickly generate enormous amounts of derivative images, it is important to support and promote original content made by artists.”

Bhumika Billa

Bhumika is a PhD student at Cambridge Faculty of Law, Trust scholar, and Research Associate at the Centre for Business Research, University of Cambridge. Bhumika is also an award-winning poet, dancer, and filmmaker – her work has been featured by various organisations including Button Poetry, BBC Words First, Southbank Centre, Apples & Snakes, UniSlam, and Harvard University.

“This was the first time I was exploring how we are translating AI through art because so far I’ve only thought about how AI has been translating us in my research. I think it’s really important to look at that reflexivity.” 

Jacqueline O’Reilly 

Jacqueline is the Co-Director for the ESRC Centre for Digital Futures at Work (Digit) and Professor of Comparative Human Resource Management at the University of Sussex Business School. Jacqueline was awarded a Jean Monnet Research Fellowship at the European University Institute in Florence and appointed Fellow of the Academy of Social Sciences (FAcSS) in 2019.

“It has been a great experimental vehicle to communicate the academic evidence from our research to the broadest audience. We hope this will ignite further discussions about these emerging trends.”

Michael Luck

Michael is the Deputy Vice-Chancellor and Provost at the University of Sussex. Previously, he was founding Director of King’s Institute for Artificial Intelligence and Director of the UKRI Centre for Doctoral Training in Safe and Trusted AI.

“The tone of the conversation that we have in general in the press is just not good enough. I think that having appropriate representations and thinking about the implications of AI is critical for the future.”

Tania Duarte

Tania is the Founder of We and AI, a UK non-profit focusing on facilitating critical thinking and more inclusive decision making about AI through AI literacy. Their programmes include the Better Images of AI collaboration with BBC R&D and the Leverhulme Centre for the Future of Intelligence.

“The competition entries as a whole were wonderful in terms of the diversity of medium, style, and conceptual approach. At a time when so much visual content online seems to be so uniformly stylised and bland, to see illustrations, collages, digital art, cartoons, watercolours tell such different stories in provocative and intriguing ways is refreshing. I particularly enjoyed the creation or depiction of some new metaphors of AI that are far closer to the bone than ones we typically see.”

Ben Wodecki

Ben is an accomplished technology journalist with an established track record reporting on cutting-edge developments in AI, emerging tech, data centres, networking, and innovation law. He was named among MVPR’s top 18 journalists writing about AI in 2024 and has previously written for AI Business, The AI Journal, and Capacity Media.

Rob Keery

Rob is the CMO at Anything is Possible and Jagged Edge AI. Rob loves connecting with bold brands and getting under the skin of their media, tech and creative challenges – then turning them into effective growth.

“Day to day it’s challenging to communicate about AI with people whose knowledge is mediated through tech-sector boosterism or media fearmongering. In the blink of an eye AI has gone from superstructure to infrastructure, creating an urgent need to develop more nuanced tools to help people understand the way AI tech is changing their lives and work.

“If AI is going to fundamentally restructure work and the economy, our home lives and our interactions with online spaces, and that ‘if’ is getting smaller every day, then people need to have a voice to exercise their control and autonomy over the pace and nature of that change. But that voice is impossible without language, and people do not have that language for understanding the role of AI in their lives – so creating new models to think with is a project that deserves our sustained attention and input.”

Maninder Paul

Maninder is LinkedIn’s Top Digital Strategy Voice 2024, a seasoned B2B marketing strategist with 15+ years of experience in digital marketing and AI-driven transformation for global tech brands like Accenture and Adobe.

“As a senior marketer, I know the power of visuals in shaping brand perception and storytelling – especially in B2B. Images don’t just support a message; they are the message. I was honoured to serve as a judge for Better Images in AI – an initiative that encourages us to critically examine how AI is influencing culture.

AI can now produce images at scale, but speed and scale don’t always translate to quality or relevance. Too often, we see outputs that reflect embedded biases – falling into stereotypes, missing details, and offering a one-sided view.Whether it’s gender, race, age, or profession, these visual shortcuts can unintentionally reinforce exclusion. We’re at a pivotal moment. If we’re intentional, we can tap into AI to create visual narratives that truly reflect the diversity of the world we’re speaking to.”


By bringing people together from diverse disciplines, it was acknowledged that each judge came with their own ways of seeing, interpreting, and engaging with visual works. Their reflections as judges, but also people who regularly communicate about and engage with AI, remind us about the role that visual communication plays in shaping public understandings of technological change.

The deliberations between the judges also show how visuals serve an important role to complicate narratives, invite reimagining, and open up seemingly complex ideas to wider audiences. We hope that the “Digital Dialogues Art Competition” inspires others to think creatively about how academic research can be visualised, and to see the act of judging as a meaningful opportunity to share knowledge and reflect on differences. 


*While the original “Wheel of Progress” submission sparked rich discussion among the judges for its abstract and interpretive qualities, a simpler, more accessible version of the image has since been added to the Better Images of AI library which you can see here. The library is designed to function as an alternative to traditional stock imagery by providing clear visuals for public communication about AI so a variation of this image was added and can be downloaded for free under a CCBY-4.0 license. 

Cover image attribution: Julieta Longo & Digit / Better Images of AI / CC BY 4.0

The Bigger Picture Exhibition: Re-imagining AI Imagery

Four individuals participating in 'co-creation' activities by chatting and sharing ideas on post-it notes,

In this blog post, Emma Clarke, Nic Flanagan and Helen Sheridan reflect on “The Bigger Picture” and its beginnings which started in co-creation activities to re-imagine AI images, but it quickly grew into to a call for “better images of AI” and successful exhibition which was attended by 1200 visitors in Dublin and Cork.

In 2021, the Research Ireland ADAPT Centre launched its #DiscussAI campaign, aiming to ignite a national conversation in Ireland about Artificial Intelligence (AI) and its societal impacts. 

This initiative quickly highlighted a frustration: the scarcity of usable images of AI that genuinely captured the technology. Stock images that are dominated by sci-fi tropes like humanoid robots, glowing brains and digital numbers don’t align with the discussions the ADAPT Centre fosters through its public engagement activities. These activities seek to demystify, discuss and educate about AI, but the majority of visual imagery out there tends to reinforce concern and confusion, rather than provide clarity.

A chance encounter at a public event about ‘Information and Misinformation through the Ages: Past, Present and Future’ paved the way for a collaborative initiative called ‘The Bigger Picture‘. This project brings together artists, AI researchers, public engagement experts, along with ‘We and AI’ and ‘Better Images of AI’, with the shared goal of collectively reimagining how we perceive AI.

At the heart of ‘The Bigger Picture’ is a participatory approach, designed to democratise the conversation around AI imagery. 

Co-creation

‘The Bigger Picture: Re-imagining AI Imagery’ was a Science Week 2024 initiative funded by Research Ireland. Interactive co-creation workshop sessions in Cork and Dublin provided vibrant spaces for exploration and dialogue around art and creativity in the age of Generative AI. 

We started with a simple icebreaker: “What does AI look like to you?” Doodled on post-it notes, the responses highlighted common perceptions of AI, ranging from drawings of robots, logos related to technology and depictions of Generative AI. 

Images of participant’s post-it notes responding to the prompt: “what does AI look like to you?”

Through facilitated discussions and hands-on activities over the course of a half-day workshop, participants were introduced to concepts like Generative AI and Explainable AI (XAI), emboldening participants to understand the technology’s nuances and experiment with prompting techniques in a low (or no) tech way. A “Walking Debate” encouraged lively discussions on ethics, technology and artistic practices related to AI. 

Participants taking part in co-creation activities

The co-creation phase was crucial because the insights gleaned from the half-day workshops directly informed a subsequent call for image submissions. By involving artists, creatives, technologists and people with a curiosity about AI from the outset, ‘The Bigger Picture’ ensured that the project’s artistic direction was genuinely reflective of community perspectives.

Call for Images

Building on these foundational workshops, an open call for artists and image-makers to contribute new AI imagery was launched. The challenge was clear: move beyond the “glowing brains” and “dystopian futures” to create new images that truly reflected AI’s presence and impact. 

The call was structured around three main themes: “AI is Everywhere”, “AI is Human,” and “AI is Complex.” These themes allowed for a diverse range of interpretations, prompting artists to consider AI in its everyday applications, its human-driven nature and its inherent complexity. 

Exhibitions in Cork and Dublin

The culmination of this participatory journey was “The Bigger Picture: Reimagining AI Imagery” exhibition in Cork and Dublin during Science Week. Eight pieces – seven images and one sculpture – were selected by an independent judging panel, each offering a unique and thought-provoking take on “AI is Everywhere.” These exhibitions, which collectively attracted over 1,200 visitors, provided a powerful visual counter-narrative to the stereotypical stock imagery we tend to see in online searches for images of “Artificial Intelligence”.

Yutong Liu’s image “AI is Everywhere” displayed at the exhibition

The Bigger Picture x Better Images of AI

A number of images that were submitted to the Call for Images were added to the Better Images of AI library, making them freely available for use in publications and educational contexts globally. These images have since been used in numerous online publications ensuring that the more accurate and representative visuals created through “The Bigger Picture” will continue to shape public understanding of AI long after the project’s conclusion.

Images from “The Bigger Picture” collection featured “in the wild” on webpages and articles. From left to right: (1) Tech Policy Press, (2) Cambridge Centre for Science and Policy, (3) Future Design Lab

“The Bigger Picture Project” demonstrates the power of participatory design. By empowering communities to explore, discuss, and creatively depict AI, we not only generated a rich collection of new imagery but also fostered a deeper public understanding of this transformative technology. This project demonstrates that moving beyond the sci-fi clichés requires more than just new images; it requires new ways of thinking, born from collective engagement and a shared vision for a more informed future with AI.

A zine exploring the process can be viewed here.

What’s next for ‘The Bigger Picture’?

Cruinniú na nÓg (a national day of free creativity for children and young people under 18) is an annual national celebration of youth creativity in Ireland. For 2025’s celebration, ‘The Bigger Picture’ worked with creative teens in schools in Dublin to co-create a call for images on the topic “AI is All Around Us”.  Ten images, created by teens for teens, go on display in Dublin City University from 7 June – 29 July 2025. The images explore topics like AI in Education, the impact AI is having on the environment and the natural world and the growing concerns around misinformation and Deep Fake technology.

Behind the scenes of “The Bigger Picture”

While the core activities of ‘The Bigger Picture’ are driven by Dr Emma Clarke (ADAPT, DCU), Nic Flanagan (MTU) and Helen Sheridan (ADAPT, TU Dublin), the project represents a dynamic collective that brings together artists and creators (see all artists here), organisations (Better Images of AI, We and AI, ADAPT Centre, Beta Festival, DCU Arts and Culture, Cruinniú na nÓg, The Digital Hub, Dublin City Council), many co-creators, collaborators (Faye Murphy, Aisling Murray, Tania Duarte, Jenny O’Brien), schools (St Mary’s Holy Faith and St Vincent’s Glasnevin), funders (Research Ireland, Creative Ireland) and more to explore how we can move towards more representative imagery of AI through engaging participatory endeavours. 


Winners Announced: Competition to Visualise ‘Digital Transformation at Work’

Poster announcing the winners of the Digital Dialogues Art Competition. White text reads 'Winners Announced' with maroon background. In the middle, there is a collage of some of the winning images. Includes logos of ESRC, Better Images of AI and Digit.

In April, the ESRC Centre for Digital Futures at Work (Digit) and Better Images of AI (BIoAI) launched a competition to reimagine the visual communication of how work is changing in the digital age. 

We received over 70 images to the competition from illustrators, artists, researchers, graphic designers, and photographers from all around the world, including Brazil, Hong Kong, Lebanon, France, Uganda, Argentina, Peru, Ireland, the US and the UK. The submissions thoughtfully challenged the dominant stock imagery used to depict digital transformation at work by offering more nuanced, inclusive, and grounded visual representations. 

Entrants submitted their images to reflect four themes: digital adoption, digital inclusion, changing employment contracts and working conditions, and digital dialogues. These were derived from the ‘Digital Dialogues’ report of Digit’s 5 year research programme which investigated ongoing impacts of digital transformation on people’s daily lives. 

“Collectively, these images prompt us to think more deeply about the multifaceted impacts of the digital transformation of work. They offer us more thoughtful, nuanced and varied ways of seeing and imagining the changes already taking place. By making them freely available through the Better Images of AI library, we hope they will also play a small part in helping to shape the emergent digital work ecosystem, by helping to shape the wider conversation. It has been a great experimental vehicle to communicate the academic evidence from our research to the broadest audience. We hope this will ignite further discussions about these emerging trends”
Professor Jacqueline O’Reilly, Co-Director of Digit

The BIoAI team conducted an initial short list of images for judges to score. The panel came together to discuss their scores and select a series of winners and runners-up that they thought best reflected the complexity, diversity, and real-world implications of digital transformation at work. The judging panel was composed of experts from creative, research, technical, and union backgrounds: 

  • Niels Bonde (digital artist and academic fellow)
  • Bhumika Billa (legal academic and creative) 
  • Chanell Daniels (Responsible AI manager at Digital Catapult) 
  • Tania Duarte (Better Images of AI, Founder of We and AI) 
  • Rob Keery (CMO at Anything is Possible and Jagged Edge AI) 
  • Michael Luck (Deputy Vice-Chancellor at University of Sussex) 
  • Jacqueline O’Reilly (Co-Director of Digit)
  • Maninder Paul (AI Strategist) 
  • Nick Scott (AI Director at Unions 21) 
  • Nina Wakeford (Professor of Art) 
  • Ben Wodeki (Technology Reporter) 

As a result of the strength and number of competition entries, the judges awarded an additional ‘highly commended’ prize.

We would like to thank all the artists who entered the competition, including many who kindly donated their submissions to the Better Images of AI library. This means that a wider selection of over 20 images are available under a Creative Commons license for anyone to use for free with attribution.

“We have been overwhelmed to receive such a diverse range of submissions that provided rich interpretations of Digit’s research and illustrate really interesting aspects of digital transformation, that don’t make it into stock image libraries. A special thank you to the judges, Digit, and ESRC who have also supported and contributed invaluably to the competition. We look forward to seeing these new images being used by the Better Images of AI’ Image library’s users to illustrate news articles and comment related not only to digital transformation and the future of work, but also some of the broader questions they raise about the increasing use of AI in the workplace.”
– Tania Duarte, Founder of We and AI, for Better images of AI

The winners

Yutong Liu & Digit / Better Images of AI / CC BY 4.0

“Across time, the sun never sets. Exploitation? Oppression? Or convenience? A group of people work around the tower, hailing from different places and time zones. While they enjoy greater freedom in choosing their working hours, they also face the challenges of time differences. This is the precarious balance of digital nomadism.”

Download “Digital Nomads: Across Time” for free in the Better Images of AI library.

WINNER #1: Kathryn Conrad – “Isolation” 

Kathryn Conrad & Digit / Better Images of AI / CC BY 4.0

“The image is intended to represent independent data gig workers who work in isolation not only from the larger project with which they might be engaged (e.g., flagging graphic images for video platforms, tagging data for commercial AI systems or weapon systems) but also from other human workers (through distance, physical separation, or technological buffers like headphones).”

Download “Isolation” for free in the Better Images of AI library. 

WINNER #2: Yutong Liu – “Digital Nomads: Digital-Based Connection” 

Yutong Liu & Digit / Better Images of AI / CC BY 4.0

“Thanks to advancements in digital technology, people can now work from various places, including those closer to nature, reflecting a shift in work environments. However, at the same time, birds resembling mouse cursors are causing chaos in the sky. Through this imagery, I highlight the challenges and unknown risks brought by such digital communities.”

Download “Digital Nomads: Digital-Based Connection” for free in the Better Images of AI library. 

WINNER #3: Janet Turra – “Entry Level” 

Janet Turra & Digit / Better Images of AI / CC BY 4.0

“I wanted to illustrate how digital transformation can make it more difficult for young people to gain the skills required for entry level jobs. The goalposts being moved, as it were, as a result of AI adoption.”

Download “Entry Level” for free in the Better Images of AI library. 

WINNER #4: IceMing – “Stochastic Parrots at Work” 

IceMing & Digit / Better Images of AI / CC BY 4.0

“The image illustrates the experimental integration of AI into human workplaces, drawing on the metaphor of “stochastic parrots” to represent generative AI tools. The glitchy AI parrots assist with analyzing, sorting, and sense-making tasks, but their presence is varied. Some AI are leashed, symbolizing attempts at control, while others respond to human commands more autonomously.”

Download “Stochastic Parrots at Work” for free in the Better Images of AI library.


The runners up

RUNNER UP #1: Leo Lau – ”Wheel of Progress”

‘Wheel of Progress’ by Leo Lau

“This image explores the paradox of digital transformation in the workplace. 2 knowledge workers, running inside a wheel embedded within a computer mouse, struggle to keep pace as a powerful hand (representing employers or capitalistic forces).”

RUNNER UP #2 (JOINT): Leo Lau – “Knowledge Sweatshop”

Leo Lau & Digit / Better Images of AI / CC BY 4.0

“This image illustrates digital transformation gone wrong, where technology becomes a tool for intensified extraction. Instead of liberating labour, automation can lock workers into more exhausting cycles of output, without increasing agency or rewards.”
Download “Knowledge Sweatshop” for free in the Better Images of AI library. 

RUNNER UP #2 (JOINT): Julieta Longo – ”Digitalisation and Moonlighting” 

Julieta Longo & Digit / Better Images of AI / CC BY 4.0

“The image represents both the possibilities and the risks of work digitalisation, particularly for mothers and people with caregiving responsibilities. Platform-based work and remote work are presented as activities that may help reconcile paid and unpaid labor, though this reconciliation often involves tensions.”

Download “Digitalisation and Moonlighting” for free in the Better Images of AI library.

RUNNER UP #3: Nadia Nadesan – ”We’re Sorry!” 

‘We’re Sorry’ by Nadia Nadesan

“It evokes a time when mobile devices were tools of aspiration and accessibility, yet now symbolize obsolescence. The depicted phone represents both an entry point to digital life and a marker of technological disparity—while some communities have moved on to advanced smart devices and constant connectivity, others remain tethered to outdated tools.”

RUNNER UP #4: Jamillah Knowles – ”Bold Office” 

Jamillah Knowles & Digit / Better Images of AI / CC BY 4.0

“A brightly coloured office populated with all kinds of people working at connected desks. There are computer screens and networks in the air in clouds. The image shows the connectivity of a digitally transformed workplace.”

Download “Bold Office” for free in the Better Images of AI library.

HIGHLY COMMENDED: Reihaneh Golpayegani – ”Employment in Frames” 

‘Employment in Frames’ by Reihaneh Golpayegani

“This image was intended to convey multiple concepts, the storyboard style was chosen to draw attention to changed working conditions—while also touching on socio-economic inequalities and workplace technology adoption. The blurring of work and personal life is emphasised in two separate illustrations as one of the most relatable implications of digital transformation.”


In the coming weeks, we’ll be posting a series of deep dives into the artwork and artists that entered our ‘Digital Dialogues Art Competition’. These posts will explore the ideas behind the entries, the creative processes involved, and the broader themes about digital transformation that we’ve seen emerge across the submissions.

We’ll also be sharing feedback from the judges and organisers, offering insight into how decisions were made and how the competition itself was designed, reflecting on the criteria and the reasons specific choices were made.

Cover image credits (left to right)

IceMing & Digit / Better Images of AI / CC BY 4.0

Janet Turra & Digit / Better Images of AI / CC BY 4.0

Julieta Longo & Digit / Better Images of AI / CC BY 4.0

Leo Lau & Digit / Better Images of AI / CC BY 4.0

Yutong Liu & Digit / Better Images of AI / CC BY 4.0

Kathryn Conrad & Digit / Better Images of AI / CC BY 4.0

‘AI Am Over The Hype’ by Rameez Raja

A red-toned illustration shows a man's head surrounded by swirling AI icons, with small, mischievous witch-like figures flying around him. The man's expression appears disoriented and fatigued. Below is the text 'AI Am Over The Hype' by Rameez Raja.

Artist contributions to the Better Images of AI library have always served a really important role in relation to fostering understanding and critical thinking about AI technologies and their context. Images facilitate deeper inquiries into the nature of AI, its history, and ethical, social, political and legal implications.

When artists create better images of AI, they often have to grapple with these narratives in their attempts to more realistically portray the technology and point towards its strengths and weaknesses. Furthermore, as artists freely share these images in our library, others can benefit from learning about the artist’s own internal motivations (which are provided in the descriptions) but the images can also inspire users’ own musings.

In this series of blog posts, some of our volunteer stewards are each taking turns to choose an image from the Archival Images of AI collection and unpack the artist’s processes and explore what that image means to them. 

At the end of 2024, we released the Archival Images of AI Playbook with AIxDESIGN and the Netherlands Institute for Sound and Vision. The playbook explores how existing images – especially those from digital heritage collections – can help us craft more meaningful visual narratives about AI. Through various image-makers’ own attempts to make better images of AI, the playbook shares numerous techniques which can teach you how to transform existing images into new creations.

Here, Rameez Raja unpacks AI Am Over It’ Nadia Piet’s (an image-maker) own better image of AI that was created for the playbook. Rameez personally reflects on his feelings towards AI amidst a never-ending stream of AI hype and ‘LinkedIn guru hot takes’ on the latest developments in the space. Despite the increasing infiltration of AI into society, Rameez comments on how Piet’s image points to a growing resistance in society against using AI as developers steal artwork from creators, further misinformation, and challenge our sense of self. 


A red-toned illustration shows a man's head surrounded by swirling AI icons, with small, mischievous witch-like figures flying around him. The man's expression appears disoriented and fatigued, symbolizing the mental overload caused by the overwhelming flood of AI tools and news. The witches represent the chaotic, cackling nature of rapid AI developments, adding to the sense of dizziness and confusion.

Nadia Piet & Archival Images of AI + AIxDESIGN / Better Images of AI / CC BY 4

“So, what do you think of AI?”. “I’m tired of it.”

 This is the  go-to question that always finds its way to me—at family dinners, in WhatsApp groups, or halfway through a drink with someone. And truthfully? It exhausts me. Not because I’m indifferent—far from it. I spend my days thinking deeply about technology, analysing platforms, working at the intersection of AI, society, and policy. But lately, I’ve been feeling the weight of it all. My brain feels like it’s buffering.

There’s something about the pace, the hype, the never-ending stream of think-pieces, hot takes, and LinkedIn gurus that leaves me exhausted. One day it’s agents, the next it’s Sora, then AutoGPT—each promising disruption, innovation, or a new dawn. And yet, behind all that noise, the human questions remain: Who is this tech serving? Who’s left out? And most of all—how are we feeling in the face of it?

That’s why Nadia Piet’s artwork, AI Am Over It, resonated with me. It  comments on AI fatigue, illustrating how the overwhelming flood of tools and constant influx of headlines leaves most people feeling dizzy and disoriented. With AI icons swirling around the figure’s head, it captures the mental overload and confusion many feel as they struggle to keep up with rapid developments / the fast-paced AI landscape.

It feels like a snapshot of my inner world: a human figure—serene, stoic—surrounded by a chaotic halo of AI logos competing for attention. The AI fatigue  is real. The figure—drawn from what looks like a Renaissance or alchemical manuscript—evokes an age of inquiry, mysticism, and visionary thinking. But here, he’s not discovering truths. He’s being drowned in them. He’s being submerged in signals—too many, too loud, too fast to make sense of.

AI Overload

The image captures what AI has become for so many of us: not a revelation, but a cognitive overload. The myth of AI as a rational, godlike mind—an Enlightenment fantasy—is clashing with the reality of our current AI landscape: noisy, exploitative, corporatised. The logos circling the figure don’t represent knowledge; they represent branding, monetisation, and an endless feed of skewed updates. 

Another layer that struck me was that the central figure might as well be a ghost from the past. A time traveler from an era where knowledge was sacred, slow, and wrapped in ritual. The alchemists, the philosophers, the mystics—they sought truth through wonder. Today, we scrape, prompt, and automate. In Piet’s image, this archival human seems caught in a time loop, trapped in the chaos of modern signals. There’s a sadness to it. A sense of lost dialogue between worlds.

We’re not just engaging with AI anymore—we’re surrounded by it. That’s what I see in those orbiting logos. A kind of orbital trap, where our thoughts, emotions, and even our sense of self are influenced by algorithmic systems. Elon Musk’s Grok being used to clap back at posts on X is a perfect example of this cultural drift. AI isn’t just answering questions—it’s shaping how we argue, how we feel, how we relate to each other. It’s performance masked as fact-checking, surveillance disguised as help.

And while some celebrate the spread of these tools as progress, many of us are quietly turning away. There’s a kind of reverse effect happening: the more AI saturates every part of public discourse, the more we begin to tune out. When everyone is suddenly an expert, a prompt engineer, or a tech visionary, the truth becomes harder to locate. In that fog of hot takes and hype, we lose clarity. We lose trust. We lose the human signal in the noise.

Seeing Through the Hype

What ‘AI Am Over It’ does so powerfully is that it doesn’t just document the presence of AI—it critiques it. The title is a mood, a manifesto, a coping mechanism. It aligns with broader movements we’re seeing across the creative world. Take the backlash from artists like Paul McCartney or Kate Bush, who’ve criticised AI companies for using their voices or songs without permission. That outrage has led to tangible action—like amendments pushing for more transparency and economic impact assessments in AI development.

We need more of this. Because unregulated AI doesn’t just risk misinformation—it risks stagnation. Creativity becomes lazy when it’s just derivative output from a scraped dataset. Why explore new ideas when you can prompt a remix? If we lean too heavily on AI to create, to ideate, to think, we may lose touch with what it means to make something truly original. The danger isn’t just economic—it’s existential. Are we becoming passive consumers of pre-generated thought?

This is where Piet’s image becomes more than aesthetic. It’s archival. It preserves a moment of resistance, a visual reminder that AI isn’t just a tool—it’s a terrain we navigate daily, often without clear maps. And like any map, the legends matter. Whose vision is being drawn? Who controls the ink? By invoking a figure from the past, the image also invites us to reflect on the longer history of AI—its myths, its cycles of hype, and the often invisible human labour that has always underpinned technological change. Archival imagery, in this way, becomes a tool for challenging present-day narratives, reminding us that today’s ‘new’ is often built on forgotten or overlooked foundations.

And then there’s the meme-ification of it all. AI isn’t just a tool—it’s become part of our collective moodboard. The rise of “Ghiblification,” where AI generates images in the Studio Ghibli style, might seem innocent or even charming. But it’s another front in the conversation over cultural ownership. Art as aesthetic, stripped of context, style without story. These remixes flatten rather than deepen our understanding. They don’t honour artistry—they commodify it.

That’s why I keep returning to ‘AI Am Over It’. It’s not prescriptive. It doesn’t try to tell us what AI is or what we should think. It simply reflects. It holds up a mirror to our moment—messy, noisy, and at times, disillusioned. But it also quietly reminds us that we’re still here. That amidst the automation, the chaos, the acceleration, the human is not lost – just tired!

Maybe being “over it” isn’t the end. Maybe it’s the start of something else—a pause, a breath, a reorientation. A chance to find our own orbit again.


About the author

Rameez Raja (he/him) is a data analytics engineer and storyteller, passionate about AI and designing systems that foster connection for a healthier society. A UCL graduate, he is pursuing an MS in AI at the University of Bath and advocates for trustworthy communication as essential to thriving democracies and communities.


If you want to contribute to our new blog series, ‘Through My Eyes’, by selecting an image from the Better Images of AI Library and exploring what the image means to you, get in touch (info@betterimagesofai.org). 

Cover image credit: Nadia Piet & Archival Images of AI + AIxDESIGN /Better Images of AI/ CC BY 4

Explore other posts in the ‘Through My Eyes’ Series

https://thistle-oriole.pikapod.net/what-do-i-see-in-ways-of-seeing-by-zoya-yasmine/
https://thistle-oriole.pikapod.net/exploring-complexity-in-the-data-flock-by-joe-bourne/
https://thistle-oriole.pikapod.net/weaved-wires-weaving-me-by-laura-martinez-agudelo/

Exploring Complexity in the Data Flock by Joe Bourne

A laptopogram displaying a dataset as cloud-like clusters of black blobs on a neutral background. There are three larger collections, almost resembling a map, with some data points leaking out into the negative space. Over this image, is the text ''Through My Eyes Blog Series' in the right top corner in white text in a maroon text box/ Below the image, is the text 'Exploring Complexity in the Data Flock' (bold) 'By Joe Bourne' against a light blue background.

Artist contributions to the Better Images of AI library have always served a really important role in relation to fostering understanding and critical thinking about AI technologies and their context. Images facilitate deeper inquiries into the nature of AI, its history, and ethical, social, political and legal implications.

When artists create better images of AI, they often have to grapple with these narratives in their attempts to more realistically portray the technology and point towards its strengths and weaknesses. Furthermore, as artists freely share these images in our library, others can benefit from learning about the artist’s own internal motivations (which are provided in the descriptions) but the images can also inspire users’ own musings.

In this series of blog posts, some of our volunteer stewards are each taking turns to choose an image from the library and unpack the artist’s processes and explore what that image means to them.

Here, Joe Bourne explores Data Flock (digits) by Philipp Schmitt and reflects on how the image invites us to think about the subtleties in the relationships between AI, data, and humans. He draws attention to the image’s ambiguity that represents the complexity of data without trying to gloss over its nuances which can mislead us or prevent us from making our own judgments about information. 


A laptopogram displaying a dataset as cloud-like clusters of black blobs on a neutral background. There are three larger collections, almost resembling a map, with some data points leaking out into the negative space.

Philipp Schmitt / Better Images of AI  / CC-BY 4.0 


From Posters on Bedroom Walls to Da Vinci’s Notebooks

I assumed choosing my favourite image from the Better Images of AI collection would be a personal thing. What I didn’t expect was to find myself having to do some intense googling to track down a half-remembered exhibition poster from my teenage bedroom wall. 

The image that sparked this trip down memory lane is Data Flock (digits) by Philipp Schmitt. Data Flock (digits) shows a machine learning dataset visualized spatially, in cloud-like clusters according to visual similarity of the data. Although visualizations like this one always simplify and fail to represent the data’s true complexity and nuance, they guide the researchers’ intuitions for their subject matter. The image is a ‘laptopogram’, created by exposing photographic paper using a computer screen and developed in the artist’s bathtub. The process preserves a digital artifact of AI research in silver crystals, returning a physical dimension to sterile data. Dust, scratches, and the marks left by the artist’s hands draw a connection to the role of the researchers’ subjectivity in making AI.


At first glance, it reminded me of the speculative models and scribblings on the poster for Panamarenko’s Bing of the Ferro Lusto 2000 exhibition from my teenage bedroom wall. Schmitt’s image has a similar hand-crafted and open-ended feel. Panamarenko’s sketches looked like fantastical vehicles or improbable machines, while Data flock (digits) evokes something more abstract and organic. To me, the blobs look like tiny grubs, or bacteria, maybe even buffalo from a great height. Others might see beans, or droplets, or brush marks. There’s no single right answer, and that’s part of what makes it compelling.

It also calls to mind da Vinci’s famous notebooks with flying machines and the vitruvian man: the yellowed backgrounds, the visible drafting marks and something simultaneously analytical and artistic. Like those sketches, Schmitt’s image sits at the intersection of science, art and science fiction: not to explain, but to explore. The data is clustered, sorted, and shaped, but the meaning remains open. This is what I find so captivating: that Data Flock (digits) captures the process of pattern recognition without forcing a conclusion. It’s a good reminder that even when AI or data analysis can spot patterns, we’re still the ones making sense of them. Or trying to, at least.

AI Metaphors and Meaning

There’s also something quietly organic in the image’s visual texture. To me, the ‘flocking’ resembles weather maps or wind currents: pressure systems moving across the frame. In my own research, I’ve written about the metaphors we reach for when trying to explain data-driven technologies. “The cloud” is one example: a term that implies something weightless and remote, when in fact it refers to very grounded, physical infrastructures. The language we use to describe AI is full of euphemism, metaphor and anthropomorphism, and while those can help us relate to the intangible and complex parts, systems and concepts behind data, AI and the internet, they also risk misleading us. Data flock (digits) plays with this tension: hinting at anthropomorphic movement, without giving in completely to any recognisable metaphor or cliche. The blobs in this data flock feel simultaneously natural and digital.

Something else that draws me to this image is how it reveals something of the process behind machine learning. The blobs are grouped according to visual similarity, but there’s no legend or key. You’re left to observe, to notice, to wonder. It’s an aesthetic representation of categorisation (one of the fundamental operations in data science) but without the usual gloss of objectivity or neatness. It invites ambiguity and curiosity. It shows us the work of sorting and learning. Schmitt’s own description of the image, that “visualizations like this one always simplify and fail to represent the data’s true complexity and nuance, [but] they guide the researchers’ intuitions”, gets to the heart of why I admire it. I’m always drawn to attempts to make AI or machine learning more tangible. Especially when they don’t try to smooth over the complexity. The best ones let you see the mess, the uncertainty, the weird edges that don’t quite line up. That’s where it gets interesting. This image does that. It reminds us that there is always a human: whether analysing data, interpreting visualisations, or deciding how best to communicate them. Even when making the image itself, captured by the marks, scratches and fingerprints.

Art for Art’s Sake

As well as sending me down memory lane, remembering having my mind expanded in the Hayward Gallery twenty-plus years ago, the image also led me down a wonderfully unexpected rabbit hole. I’d never heard of a laptopogram before reading Schmitt’s accompanying interpretation for this image. This discovery speaks to something that makes Better Images of AI so valuable. While its stated purpose is to improve the visuals used to represent AI in public life, it also functions as an art exhibition in its own right: Art for art’s sake. Through this project I’ve been introduced to all kinds of image-making techniques I didn’t know about before: digital collaging, archival remixing, glitch aesthetics. As someone who enjoys low-fi making and physical processes, I was delighted to learn that data flock (digits) was created by exposing photographic paper to a computer screen and developing it in a bathtub. You can see that process in the final image: in the specks, scratches, and smudges. It’s a tactile, analogue production that sits in refreshing contrast to the smooth, polished surfaces of AI-generated imagery.

The Value of Ambiguity

Finally, there’s a practical reason I keep returning to this image: it’s incredibly useful. Because it’s not tied to a specific AI use case, and because its aesthetic is so open-ended, I’ve found myself using it in presentations, slides, and publications across a range of contexts. It doesn’t tell the viewer what to think, but it allows them space to think. For a project like Better Images of AI, which aims to shift how these technologies are represented, that matters. Likelihood of adoption should be part of how we evaluate what makes an image “better.”

Data flock (digits) is a reminder that images don’t need to explain everything. Sometimes, they’re more powerful when they simply invite us to pay attention: to complexity, to process, and to the humans behind the scenes.


About the author

Joe Bourne (he/him) is doing a PhD in Speculative Design and Emerging Technologies at Imagination Lancaster, and he is a Partnership Development Lead at the Alan Turing Institute. Joe is particularly interested in public understanding and imaginings of emerging technology, and people’s hopes and fears associated to this.


If you want to contribute to our new blog series, ‘Through My Eyes’, by selecting an image from the Better Images of AI Library and exploring what the image means to you, get in touch (info@betterimagesofai.org). 

Cover image credit: Philipp Schmitt / Better Images of AI  / CC-BY 4.0 

Explore other posts in the ‘Through My Eyes’ Series

https://thistle-oriole.pikapod.net/what-do-i-see-in-ways-of-seeing-by-zoya-yasmine/
https://thistle-oriole.pikapod.net/weaved-wires-weaving-me-by-laura-martinez-agudelo/


Images of AI – Between Fiction and Function

This image shows an abstract microscopic photograph of a Graphics Processing Unit resembling a satellite image of a big city. The image has been overlayed with a bright blue filter. In the middle of the image is the text, 'Images of AI - Between Fiction and Function' in a white text box with black text. Beneath, in a maroon text box is the author's name in white text.

“The currently pervasive images of AI make us look somewhere, at the cost of somewhere else.”

In this blog post, Dominik Vrabič Dežman provides a summary of his recent research article, ‘Promising the future, encoding the past: AI hype and public media imagery‘.

Dominik sheds light on the importance of the Better Images of AI library which fosters a more informed, nuanced public understanding of AI by breaking the stronghold of the “deep blue sublime” aesthetic with more diverse and meaningful representations of AI.

Dominik also draws attention to the algorithms which perpetuate the dominance of familiar and sensationalist visuals and calls for movements which reshape media systems to make better images of AI more visible in public discourse.

The full paper is published in the AI and Ethics Journal’s special edition on ‘The Ethical Implications of AI Hype, a collection edited by We and AI.


AI promises innovation, yet its imagery remains trapped in the past. Deep-blue, sci-fi-inflected visuals have flooded public media, saturating our collective imagination with glowing, retro-futuristic interfaces and humanoid robots. These “deep blue sublime” [1] images, which draw on a steady palette of outdated pop-cultural tropes and clichés, do not merely depict AI — they shape how we think about it, reinforcing grand narratives of intelligence, automation, and inevitability [2]. It takes little to acknowledge that the AI discussed in public media is far from the ethereal, seamless force these visuals disclose. Instead,  the term generally refers to a sprawling global technological enterprise, entangled with labor exploitation, ecological extraction, and financial speculation [3–10] — realities conspicuously absent from its dominant public-facing representations.

The widespread rise of these images is suspended against intensifying “AI hype” [11], which has been compared to historical speculative investment bubbles [12,13]. In my recent research [1,14,15], I join a growing body of research looking into images of AI [16–21], to explore how AI images operate at the intersection of aesthetics and politics. My overarching ambition has been to contribute an integrated account of the normative and the empirical dimensions of public images of AI to the literature.  I’ve explored how these images matter politically and ethically, inseparable from the pathways they take in real-time, echoing throughout public digital media and wallpapering it in seen-before denominations of blue monochrome.

Rather than measuring the direct impact of AI imagery on public awareness, my focus has been on unpacking the structural forces that produce and sustain these images. What mechanisms dictate their circulation? Whose interests do they serve? How might we imagine alternatives? My critique targets the visual framing of AI in mainstream public media — glowing, abstract, blue-tinted veneers seen daily by millions on search engines, institutional websites, and in reports on AI innovation. These images do not merely aestheticize AI; they foreclose more grounded, critical, and open-ended ways of understanding its presence in the world.


The Intentional Mindlessness of AI Images

This image shows a google images search for 'artificial intelligence'. The result is a collection of images which contain images of the human brain, the colour blue, and white humanoid robots.

Google Images search results for “artificial intelligence”. January 14, 2025. Search conducted from an anonymised instance of Safari. Search conducted from Amsterdam, Netherlands.

Recognizing the ethico-political stakes of AI imagery begins with acknowledging that what we spend our time looking at, or not looking beyond, matters politically and ethically. The currently pervasive images of AI make us look somewhere, at the cost of a somewhere else. The sheer volume of these images, and their dominance in public media, slot public perception into repetitive grooves dominated by human-like robots, glowing blue interfaces, and infinite expanses of deep-blue intergalactic space. By monopolizing the sensory field through which AI is perceived, they reinforce sci-fi clichés, and more importantly,  obscure the material realities — human labor, planetary resources, material infrastructures, and economic speculation — that drive AI development [22,23].

In a sense, images of AI could be read as operational [24–27], enlisted in service of an operation which requires them to look, and function, the way they do. This might involve their role in securing future-facing AI narratives, shaping public sentiment towards acceptance of AI innovation, and supporting big tech agendas for AI deployment and adoption. The operational nature of AI imagery means that these images cannot be studied purely as an aesthetic artifact, or autonomous works of aesthetic production. Instead, these images are minor actors, moving through technical, cultural and political infrastructures. In doing so, individual images do not say or do much per se – they are always already intertwined in the circuits of their economic uptake, circulation, and currency; not at the hands of the digital labourers who created them, but of the human and algorithmic actors that keep them in circulation.

Simultaneously, the endurance of these images is less the result of intention than of a more mindless inertia. It quickly becomes clear how these images do not reflect public attitudes, nor of their makers; anonymous stock-image producers, digital workers mostly located in the global South [28]. They might reflect the views of the few journalistic or editorial actors that choose the images in their reporting [29], or are simply looking to increase audience engagement through the use of sensationalist imagery [30]. Ultimately, their visibility is in the hands of algorithms rewarding more of the same familiar visuals over time [1,31], of stock image platforms and search engines, which maintain close ties with media conglomerates  [32], which, in turn, have long been entangled with big tech [33]. The stock  images are the detritus of a digital economy that rewards repetition over revelation: endlessly cropped, upscaled, and regurgitated “poor images” [34], travelling across cyberspace as they become recycled, upscaled, cropped, reused, until they are pulled back into circulation by the very systems they help sustain [15,28].


AI as Ouroboros: Machinic Loops and Recursive Aesthetics

As algorithms increasingly dictate who sees what in the public sphere [35–37], they dictate not only what is seen but also what is repeated. Images of AI become ensnared in algorithmic loops, which sediment the same visuality over time on various news feeds and search engines [15]. This process has intensified with the proliferation of generative AI: as AI-generated content proliferates, it feeds on itself—trained on past outputs, generating ever more of the same. This “closing machinic loop” [15,28] perpetuates aesthetic homogeneity, reinforcing dominant visual norms rather than challenging them. The widespread adoption of AI-generated stock images further narrows the space for disruptive, diverse, and critical representations of AI, making it increasingly difficult for alternative images to surface in public visibility.

The image shows a humanoid figure with a glowing, transparent brain stands in a digital landscape. The figure's body is composed of metallic and biomechanical components, illuminated by vibrant blue and pink lights. The background features a high-tech grid with data streams, holographic interfaces, and circuitry patterns.

ChatGPT 4o output for query: “Produce an image of ‘Artificial Intelligence’”. 14 January 2025.


Straddling the Duality of AI Imagery

In critically examining AI imagery, it is easy to veer into one of two deterministic extremes — both of which risk oversimplifying how these images function in shaping public discourse:

  1. Overemphasizing Normative Power:

This approach risks treating AI images as if they have autonomous agency, ignoring the broader systems that shape their circulation. AI images appear as sublime artifacts—self-contained objects for contemplation, removed from their daily life as fleeting passengers in the digital media image economy. While the production of images certainly exerts influence in shaping socio-technical imaginaries [38,39], they operate within media platforms, economic structures, and algorithmic systems that constrain their impact.

2. Overemphasizing Materiality:

This perspective reduces AI to mere infrastructure, seeing images as passive reflections of technological and industrial processes, rather than an active participant in shaping public perception. From this view, AI’s images are dismissed as epiphenomenal, secondary to the “real” mechanisms of AI’s production: cloud computing, data centers, supply chains, and extractive labor. In reality, AI has never been purely empirical; cultural production has been integral to AI research and development from the outset, with speculative visions long driving policy, funding, and public sentiment [40].

Images of AI are neither neutral nor inert. The current diminishing potency of glowing, sci-fi-inflected AI imagery as a stand-in for AI in public media suggests a growing fatigue with their clichés, and cannot be untangled from a general discomfort with AI’s utopian framing, as media discourse pivots toward concerns over opacity, power asymmetries, and scandals in its implementation [29,41]. A robust critique of the cultural entanglements of AI requires addressing both its normative commitments (promises made to the public), and its empirical components (data, resources, labour; [6]).

Toward Better Images: Literal Media & Media Literacy

Given the embeddedness of AI images within broader machinations of power, the ethics of AI images are deeply tied to public understanding and awareness of such processes. Cultivating a more informed, critical public — through exposure to diverse and meaningful representations of AI — is essential to breaking the stronghold of the deep blue sublime.

At the individual level, media literacy equips the public to critically engage with AI imagery [1,42,43]. By learning to question the visual veneers, people can move beyond passive consumption of the pervasive, reductive tropes that dominate AI discourse. Better images recalibrate public perception, offering clearer insights into what AI is, how it functions, and its societal impact.The kind of images produced are equally important. Better images would highlight named infrastructural actors, document AI research and development, and/or, diversify the visual associations available to us, loosening the visual stronghold of the currently dominant tropes.

This greatly raises the bar for news outlets in producing original imagery of didactic value, which is where open-source repositories such as Better Images of AI serve as invaluable resources. This crucially bleeds into the urgency for reshaping media systems, making better images readily available to creators and media outlets, helping them move away from generic visuals toward educational, thought-provoking imagery. However, creating better visuals is not enough;  they must become embedded into media infrastructure to become the norm rather than the exception.

Given the above, the role of algorithms cannot be ignored. As mentioned above, algorithms drive what images are seen, shared, and prioritized in public discourse. Without addressing these mechanisms, even the most promising alternatives risk being drowned by the familiar clichés. Rethinking these pathways is essential to ensure that improved representations can disrupt the existing visual narrative of AI.

Efforts to create better AI imagery are only as effective as their ability to reach the public eye and disrupt the dominance of the “deep blue sublime” aesthetic in public media. This requires systemic action—not merely producing different images in isolation, but rethinking the networks and mechanisms through which these images are circulated. To make a meaningful impact, we must address both the sources of production and the pathways of dissemination. By expanding the ways we show, think about, and engage with AI, we create opportunities for political and cultural shifts. A change in one way of sensing AI (writing / showing / thinking / speaking) invariably loosens gaps for a change in others.

Seeing AI ≠ Believing AI

AI is not just a technical system; it is a speculative, investment-driven project, a contest over public consensus, staged by a select few to cement its inevitability [44]. The outcome is a visual regime that detaches AI’s media portrayal from its material reality: a territorial, inequitable, resource-intensive, and financially speculative global enterprise.

Images of AI come from somewhere (they are products of poorly-paid digital labour, served through algorithmically-ranked feeds), do something (torque what is at-hand for us to imagine with, directing attention away from AI’s pernicious impacts and its growing inequalities), and go somewhere (repeat themselves ad nauseam through tightening machinic loops, numbing rather than informing; [16]).

The images have left few fooled, and represent a missed opportunity for adding to public sensitisation and understanding regarding AI. Crucially, bad images do not inherently disclose bad tech, nor do good images promote good tech; the widespread adoption of better images of AI in public media would not automatically lead to socially good or desirable understandings, engagements, or developments of AI. That remains the issue of the current political economy of AI, whose stakeholders only partially determine this image economy. Better images alone  cannot solve this, but they might open slivers of insight into AI’s global “arms race.”

As it stands, different visual regimes struggle to be born. Fostering media literacy, demanding critical representations, and disrupting the algorithmic stranglehold on AI imagery are acts of resistance. If AI is here to stay, then so too must be our insistence on seeing it otherwise — beyond the sublime spectacle, beyond inevitability, toward a more porous and open future.

About the author

Dominik Vrabič Dežman (he/him) is an information designer and media philosopher. He is currently at the Departments of Media Studies and Philosophy at the University of Amsterdam. Dominik’s research interests include public narratives and imaginaries of AI, politics and ethics of UX/UI, media studies, visual communication and digital product design.

Cover image credit: Fritzchens Fritz / Better Images of AI / CC BY 4.0 (modified with a blue filter and overlayed text)

References

1. Vrabič Dežman, D.: Defining the Deep Blue Sublime [Internet]. SETUP; (2023). 2023. https://web.archive.org/web/20230520222936/https://deepbluesublime.tech/

2. Burrell, J.: Artificial Intelligence and the Ever-Receding Horizon of the Future [Internet]. Tech Policy Press. (2023). 2023 Jun 6. https://techpolicy.press/artificial-intelligence-and-the-ever-receding-horizon-of-the-future/

3. Kponyo, J.J., Fosu, D.M., Owusu, F.E.B., Ali, M.I., Ahiamadzor, M.M.: Techno-neocolonialism: an emerging risk in the artificial intelligence revolution. TraHs [Internet]. (2024 [cited 2025 Feb 18]. ). https://doi.org/10.25965/trahs.6382

4. Leslie, D., Perini, A.M.: Future Shock: Generative AI and the International AI Policy and Governance Crisis. Harvard Data Science Review [Internet]. (2024 [cited 2025 Feb 18]. ). https://doi.org/10.1162/99608f92.88b4cc98

5. Regilme, S.S.F.: Artificial Intelligence Colonialism: Environmental Damage, Labor Exploitation, and Human Rights Crises in the Global South. SAIS Review of International Affairs. 44:75–92. (2024. ). https://doi.org/10.1353/sais.2024.a950958

6. Crawford, K.: The atlas of AI power, politics, and the planetary costs of artificial intelligence [Internet]. (2021). https://www.degruyter.com/isbn/9780300252392

7. Sloane, M.: Controversies, contradiction, and “participation” in AI. Big Data & Society. 11:20539517241235862. (2024. ). https://doi.org/10.1177/20539517241235862

8. Rehak, R.: On the (im)possibility of sustainable artificial intelligence. Internet Policy Review [Internet]. ((2024 Sep 30). ). https://policyreview.info/articles/news/impossibility-sustainable-artificial-intelligence/1804

9. Wierman, A., Ren, S.: The Uneven Distribution of AI’s Environmental Impacts. Harvard Business Review [Internet]. ((2024 Jul 15). ). https://hbr.org/2024/07/the-uneven-distribution-of-ais-environmental-impacts

10. : What we don’t talk about when we talk about AI | Joseph Rowntree Foundation [Internet]. (2024). 2024 Feb 8. https://www.jrf.org.uk/ai-for-public-good/what-we-dont-talk-about-when-we-talk-about-ai

11. Duarte, T., Barrow, N., Bakayeva, M., Smith, P.: Editorial: The ethical implications of AI hype. AI Ethics. 4:649–51. (2024. ). https://doi.org/10.1007/s43681-024-00539-x

12. Singh, A.: The AI Bubble [Internet]. Social Science Encyclopedia. (2024). 2024 May 28. https://www.socialscience.international/the-ai-bubble

13. Floridi, L.: Why the AI Hype is Another Tech Bubble. Philos Technol. 37:128. (2024. ). https://doi.org/10.1007/s13347-024-00817-w

14. Vrabič Dežman, D.: Interrogating the Deep Blue Sublime: Images of Artificial Intelligence in Public Media. In: Cetinic E, Del Negueruela Castillo D, editors. From Hype to Reality: Artificial Intelligence in the Study of Art and Culture. Rome/Munich: HumanitiesConnect; (2024). https://doi.org/10.48431/hsah.0307

15. Vrabič Dežman, D.: Promising the future, encoding the past: AI hype and public media imagery. AI Ethics [Internet]. (2024 [cited 2024 May 7]. ). https://doi.org/10.1007/s43681-024-00474-x

16. Romele, A.: Images of Artificial Intelligence: a Blind Spot in AI Ethics. Philos Technol. 35:4. (2022. ). https://doi.org/10.1007/s13347-022-00498-3

17. Singler, B.: The AI Creation Meme: A Case Study of the New Visibility of Religion in Artificial Intelligence Discourse. Religions. 11:253. (2020. ). https://doi.org/10.3390/rel11050253

18. Steenson, M.W.: A.I. Needs New Clichés [Internet]. Medium. (2018). 2018 Jun 13. https://web.archive.org/web/20230602121744/https://medium.com/s/story/ai-needs-new-clich%C3%A9s-ed0d6adb8cbb

19. Hermann, I.: Beware of fictional AI narratives. Nat Mach Intell. 2:654–654. (2020. ). https://doi.org/10.1038/s42256-020-00256-0

20. Cave, S., Dihal, K.: The Whiteness of AI. Philos Technol. 33:685–703. (2020. ). https://doi.org/10.1007/s13347-020-00415-6

21. Mhlambi, S.: God in the image of white men: Creation myths, power asymmetries and AI [Internet]. Sabelo Mhlambi. (2019). 2019 Mar 29. https://web.archive.org/web/20211026024022/https://sabelo.mhlambi.com/2019/03/29/God-in-the-image-of-white-men

22. : How to invest in AI’s next phase | J.P. Morgan Private Bank U.S. [Internet]. Accessed 2025 Feb 18. https://privatebank.jpmorgan.com/nam/en/insights/markets-and-investing/ideas-and-insights/how-to-invest-in-ais-next-phase

23. Jensen, G., Moriarty, J.: Are We on the Brink of an AI Investment Arms Race? [Internet]. Bridgewater. (2024). 2024 May 30. https://www.bridgewater.com/research-and-insights/are-we-on-the-brink-of-an-ai-investment-arms-race

24. Paglen, T.: Operational Images. e-flux journal. 59:3. (2014. ). 

25. Pantenburg, V.: Working images: Harun Farocki and the operational image. Image Operations. Manchester University Press; p. 49–62. (2016). 

26. Parikka, J.: Operational Images: Between Light and Data [Internet]. (2023). 2023 Feb. https://web.archive.org/web/20230530050701/https://www.e-flux.com/journal/133/515812/operational-images-between-light-and-data/

27. Celis Bueno, C.: Harun Farocki’s Asignifying Images. tripleC. 15:740–54. (2017. ). https://doi.org/10.31269/triplec.v15i2.874

28. Romele, A., Severo, M.: Microstock images of artificial intelligence: How AI creates its own conditions of possibility. Convergence: The International Journal of Research into New Media Technologies. 29:1226–42. (2023. ). https://doi.org/10.1177/13548565231199982

29. Moran, R.E., Shaikh, S.J.: Robots in the News and Newsrooms: Unpacking Meta-Journalistic Discourse on the Use of Artificial Intelligence in Journalism. Digital Journalism. 10:1756–74. (2022. ). https://doi.org/10.1080/21670811.2022.2085129

30. De Dios Santos, J.: On the sensationalism of artificial intelligence news [Internet]. KDnuggets. (2019). 2019. https://www.kdnuggets.com/on-the-sensationalism-of-artificial-intelligence-news.html/

31. Rogers, R.: Aestheticizing Google critique: A 20-year retrospective. Big Data & Society. 5:205395171876862. (2018. ). https://doi.org/10.1177/2053951718768626

32. Kelly, J.: When news orgs turn to stock imagery: An ethics Q & A with Mark E. Johnson [Internet]. Center for Journalism Ethics. (2019). 2019 Apr 9. https://ethics.journalism.wisc.edu/2019/04/09/when-news-orgs-turn-to-stock-imagery-an-ethics-q-a-with-mark-e-johnson/

33. Papaevangelou, C.: Funding Intermediaries: Google and Facebook’s Strategy to Capture Journalism. Digital Journalism. 0:1–22. (2023. ). https://doi.org/10.1080/21670811.2022.2155206

34. Steyerl, H.: In Defense of the Poor Image. e-flux journal [Internet]. (2009 [cited 2025 Feb 18]. ). https://www.e-flux.com/journal/10/61362/in-defense-of-the-poor-image/

35. Bucher, T.: Want to be on the top? Algorithmic power and the threat of invisibility on Facebook. New Media & Society. 14:1164–80. (2012. ). https://doi.org/10.1177/1461444812440159

36. Bucher, T.: If…Then: Algorithmic Power and Politics. Oxford University Press; (2018). 

37. Gillespie, T.: Custodians of the internet: platforms, content moderation, and the hidden decisions that shape social media. New Haven: Yale University Press; (2018). 

38. Jasanoff, S., Kim, S.-H., editors.: Dreamscapes of Modernity: Sociotechnical Imaginaries and the Fabrication of Power [Internet]. Chicago, IL: University of Chicago Press; Accessed 2022 Jun 26. https://press.uchicago.edu/ucp/books/book/chicago/D/bo20836025.html

39. O’Neill, J.: Social Imaginaries: An Overview. In: Peters MA, editor. Encyclopedia of Educational Philosophy and Theory [Internet]. Singapore: Springer Singapore; p. 1–6. (2016). https://doi.org/10.1007/978-981-287-532-7_379-1

40. Law, H.: Computer vision: AI imaginaries and the Massachusetts Institute of Technology. AI Ethics [Internet]. (2023 [cited 2024 Feb 25]. ). https://doi.org/10.1007/s43681-023-00389-z

41. Nguyen, D., Hekman, E.: The news framing of artificial intelligence: a critical exploration of how media discourses make sense of automation. AI & Soc. 39:437–51. (2024. ). https://doi.org/10.1007/s00146-022-01511-1

42. Woo, L.J., Henriksen, D., Mishra, P.: Literacy as a Technology: a Conversation with Kyle Jensen about AI, Writing and More. TechTrends. 67:767–73. (2023. ). https://doi.org/10.1007/s11528-023-00888-0

43. Kvåle, G.: Critical literacy and digital stock images. Nordic Journal of Digital Literacy. 18:173–85. (2023. ). https://doi.org/10.18261/njdl.18.3.4

44. Tacheva, Z., Appedu, S., Wright, M.: AI AS “UNSTOPPABLE” AND OTHER INEVITABILITY NARRATIVES IN TECH: ON THE ENTANGLEMENT OF INDUSTRY, IDEOLOGY, AND OUR COLLECTIVE FUTURES. AoIR Selected Papers of Internet Research [Internet]. (2024 [cited 2025 Feb 18]. ). https://doi.org/20250206083707000

What Do I See in ‘Ways of Seeing’ by Zoya Yasmine

At the top there is a Diptych contrasting a whimsical pastel scene with large brown rabbits, a rainbow, and a girl in a red dress on the left, and a grid of numbered superpixels on the right - emphasizing the difference between emotive seeing and analytical interpretation. At the bottom, there is black text which says 'what do i see in ways of seeing' by Zoya Yasmine. In the top right corner, there is text in a maroon text box which says 'through my eyes blog series'.

Artist contributions to the Better Images of AI library have always served a really important role in relation to fostering understanding and critical thinking about AI technologies and their context. Images facilitate deeper inquiries into the nature of AI, its history, and ethical, social, political and legal implications.

When artists create better images of AI, they often have to grapple with these narratives in their attempts to more realistically portray the technology and point towards its strengths and weaknesses. Furthermore, as artists freely share these images in our library, others can benefit from learning about the artist’s own internal motivations (which are provided in the descriptions) but the images can also inspire users’ own musings.

In this series of blog posts, some of our volunteer stewards are each taking turns to choose an image from the Archival Images of AI collection and unpack the artist’s processes and explore what that image means to them. 

At the end of 2024, we released the Archival Images of AI Playbook with AIxDESIGN and the Netherlands Institute for Sound and Vision. The playbook explores how existing images – especially those from digital heritage collections – can help us craft more meaningful visual narratives about AI. Through various image-makers’ own attempts to make better images of AI, the playbook shares numerous techniques which can teach you how to transform existing images into new creations. 

Here, Zoya Yasmine unpacks ‘Ways of Seeing’ Nadia Piet’s (an image-maker) own better image of AI that was created for the playbook. Zoya comments on how it is a really valuable image to depict the way that text-to-image generators ‘learn’ how to generate their output creations. Zoya considers how this image relates to copyright law (she’s a bit of an intellectual property nerd) and the discussions about whether AI companies should be able to use individual’s work to train their systems without explicit consent or remuneration. 

ALT text: Diptych contrasting a whimsical pastel scene with large brown rabbits, a rainbow, and a girl in a red dress on the left, and a grid of numbered superpixels on the right - emphasizing the difference between emotive seeing and analytical interpretation.

Nadia Piet + AIxDESIGN & Archival Images of AI / Better Images of AI / CC BY 4.0

‘Ways of Seeing’ by Nadia Piet 

This diptych contrasts human and computational ways of seeing: one riddled with memory and meaning, the other devoid of emotional association and capable of structural analysis. The left pane shows an illustration from Tom Seidmann-Freud’s Book of Hare Stories (1924) which portrays a whimsical, surreal scene that is both playful and uncanny. On the right, the illustration is reduced to a computational rendering, with each of its superpixels (16×16) fragmented and sorted by visual complexity with a compression algorithm. 


Copyright and training AI systems 

Training AI systems requires substantial amounts of input data – from images, videos, texts and other content. Based on the data from these materials, AI systems can ‘learn’ how to make predictions and provide outputs. However, lots of these materials used to train AI systems are often protected by copyright owned by another parties which raises complex questions about ownership and the legality of using such data without permission. 

In the UK, Getty Images filed a lawsuit against Stability AI (developers of a text-to-image model called Stable Diffusion) claiming that 7.3 million of its images were unlawfully scrapped from its website to train Stability AI’s model. Similarly, Mumsnet has launched a legal complaint against OpenAI, the developer of ChatGPT, accusing the AI company of scraping content from its site (with over 6 billion words shared by community members) without consent. 

The UK’s Copyright, Designs and Patents Act 1998 (the Act) provides companies like Getty Images and Mumsnet with copyright protection over their databases and assets. So unless an exception applies, permission (through a license) is required if other parties wish to reproduce or copy the content. Section 29(A) of the Act provides an exception which permits copies of any copyright protected material for the purposes of Text and Data Mining (TDM) without a specific license. But, this lenient provision is for non-commercial purposes only. Although the status of AI systems like Stable Diffusion and ChatGPT have not been tested before the courts yet, they are likely to fall outside the scope of non-commercial purposes

TDM is the automated technique used to extract and analyse vast amounts of online materials to reveal relationships and patterns in the data. TDM has become an increasingly valuable tool to train lucrative generative AI systems on mass amounts of materials scraped from the Internet. It becomes clear that AI models cannot be developed or built efficiently without input data that has been created by human artists, researchers, writers, photographers, publishers, and creators. However, as much of their works are being used without payment or attribution by AI companies, big tech companies are essentially ‘freeriding’ on the works of the creative industry who have invested significant time, effort, and resources into producing such rich works. 


How does this image relate to current debates about copyright and AI training? 

When I saw this image, it really prompted me to think about the training process of AI systems and the purpose of the copyright system. ‘Ways of Seeing’ has stimulated my own thoughts about how computational models ‘learn’ and ‘see’ in contrast to human creators

Text-to-image AI generators (like Stable Diffusion or Midjourney) are repeatedly trained on thousands of images which allow the models to ‘learn’ to identify patterns, like what common objects and colours look like, and then reproduce these patterns when instructed to create new images. While Piet’s image has been designed to illustrate a ‘compression algorithm’ process, I think it also serves as a useful visual to reflect how AI processes visual data computationally, reducing it to pixels, patterns, or latent features. 

It’s important to note that often the images generated by AI models will not necessarily be exact copies of the original images used in the training process – but instead, they serve as statistical approximations of training data which have informed the model’s overall understanding of how objects are represented. 

It’s interesting to think about this in relation to copyright and what this legal framework serves to protect. Copyright stands to protect the creative expression of works – for example, the lighting, exposure, filter, or positioning of an image – but not the ideas themselves. The reason that copyright law focuses on these elements is because they reflect the creator’s own unique thoughts and originality. However, as Piet’s illustration can usefully demonstrate, what is significant about the AI training process for copyright law is that often TDM is often not used to extract the protected expression of the materials.

To train AI models, it is often the factual elements of the work that might be the most valuable (as opposed to the creative aspects). The training process relies on the broad visual features of the images, rather than specific artistic choices. For example, when training text-to-image models, TDM is not often used to extract data about the lighting techniques which are employed to make an image of a cat particularly appealing. Instead, the accessibility to images of cats which detail the features that resemble a cat (fur, whiskers, big eyes, paws) are what’s important. In Piet’s image, the protectable parts of the illustration from the ‘Book of Hare Stories’ would subsist in the artistic style and execution  – for example, the way that the hare and other elements are drawn, the placement and interaction of the elements, and the overall design of the image. 

The specific challenge for copyright law is that AI companies are unable to capture these ‘unprotectable’ factual elements of materials without making a copy or storing the protected parts (Lemley and Casey, 2020). I think Nadia’s image really highlights the transformation of artwork into fragmented ‘data’ for training systems which challenges our understanding of creativity and originality. 

My thoughts above are not to suggest that AI companies should be able to freely use copyright protected works as training data for their models without remunerating or seeking permission from copyright owners. Instead, the way that TDM and generative AI ‘re-imagine’ the value of these ‘unprotectable’ elements means that AI companies still freeride on creator’s materials. Therefore, AI companies should be required to explicitly license copyright-protected materials used to train their systems so creators are provided with proper control over their works (you can read more about my thoughts here).

Also, I do not deny that there are generative AI systems that aim to reproduce a particular artist’s style – see here. In these instances, I think it would be easier to prove that there was copyright infringement since these are a clear reproduction of ‘protected elements’. However, if this is not the purpose of the AI tool, developers try to avoid the outputs replicating training data too similarly as this can open them up more easily to copyright infringement for both the input (as discussed in this piece) but also the output image (see here for a discussion). 


My favourite part of Nadia Piet’s image

I think my favourite part of the image is the choice of illustration used to represent computational processing. As Nadia writes in her description, Tom Seidmann-Freud’s illustration depicts a “whimsical, surreal scene that is both playful and uncanny”. Tom, an Austrian-Jewish painter and children’s book author and illustrator (and also Sigmund Freud’s niece), led a short life and she died of an overdose of sleeping pills in 1930 at age 37 after the death of her husband a few months prior. 

“The Hare and the Well” (Left), “Fable of the Hares and the Frogs” (Middle), “Why the Hare Has No Tail” (Right) by Tom Seidmann-Freud derived in the Public Domain Review

After Tom’s death, the Nazis came to power and attempted to destroy much of the art she had created as part of the purge of Jewish authors. Luckily, Tom’s family and art lovers were able to preserve much of her work. I think Nadia’s choice of this image critiques what might be ‘lost’ when rich, meaningful art is reduced to AI’s structural analysis. 

A second point, although not related exactly to the image, is the very thoughtful title, ‘Ways of Seeing’. ‘Ways of Seeing’ was a 1972 BBC television series and book created by John Berger. In the series, Berger criticised traditional Western cultural aesthetics by raising questions about hidden ideologies in visual images like the male gaze embedded in the female nude. He also examined what had changed in our ‘ways of seeing’ in the time between the art was made and the present day. Side note: I think Berger’s would have been a huge fan of Better Images of AI. 

In a similar vein, Nadia has used Seidmann-Freud’s art as a way to explore new parallels with technology like AI which would not have been thought about at the time the work was created. In addition, Nadia’s work serves as an invitation to see and understand AI differently, and like Berges, her work supports artists around the world.


The value of Nadia’s ‘better image of AI’ for copyright discussions

As Nadia writes in the description, Tom Seidmann-Freud’s illustration was derived from the Public Domain Review, where it is written that “Hares have been known to serve as messengers between the conscious world and the deeper warrens of the mind”. From my perspective, Nadia’s whole image acts as a messenger to convey information about the two differing modes of seeing between humans and AI models. 

We need better images of AI like this. Especially for the purposes of copyright law so we can have more meaningful and informed conversations about the nature of AI and its training processes. All too often, in conversations about AI and creativity, images used depict humanoid robots painting on a canvas or hands snatching works.

‘AI art theft’ illustration by Nicholas Konrad (Left) and Copyright and AI image (Right)

These images create misleading visual metaphors that suggest that AI is directly engaging in creative acts in the same way that humans do. Additionally, visuals showing AI ‘stealing’ works reduce the complex legal and ethical debates around copyright, licensing, and data training to overly simplified, fear-evoking concepts.

Thus, better images of AI, like ‘Ways of Seeing’, can serve a vital role as a messenger to represent the reality of how AI systems are developed. This paves the way for more constructive legal dialogues around intellectual property and AI that protect creator’s rights, while allowing for the development of AI technologies based on consented, legally acquired datasets.


About the author

Zoya Yasmine (she/her) is a current PhD student exploring the intersection between intellectual property, data, and medical AI. She grew up in Wales and in her spare time she enjoys playing tennis, puzzling, and watching TV (mostly Dragon’s Den and Made in Chelsea). Zoya is also a volunteer steward for Better Images of AI and part of many student societies including AI in Medicine, AI Ethics, Ethics in Mathematics & MedTech. 


This post was also kindly edited by Tristan Ferne – lead producer/researcher at BBC Research & Development.


If you want to contribute to our new blog series, ‘Through My Eyes’, by selecting an image from the Archival Images of AI collection and exploring what the image means to you, get in touch (info@betterimagesofai.org)

Cover image credit: Nadia Piet + AIxDESIGN & Archival Images of AI / Better Images of AI / CC BY 4.0

Explore other posts in the ‘Through My Eyes’ Series

https://thistle-oriole.pikapod.net/weaved-wires-weaving-me-by-laura-martinez-agudelo/
https://thistle-oriole.pikapod.net/exploring-complexity-in-the-data-flock-by-joe-bourne/

‘Weaved Wires Weaving Me’ by Laura Martinez Agudelo

At the top, Digital collage featuring a computer monitor with circuit board patterns on the screen. A Navajo woman is seated on the edge of the screen, appearing to stitch or fix the digital landscape with their hands. Blue digital cables extend from the monitor, keyboard, and floor, connecting the image elements. Beneath, there is the text in black, 'Weaved Wires Weaving Me' by Laura Martinez Agudelo'. In the top right corner, there is a text box in maroon with the text in white: 'through my eyes blog series'

Artist contributions to the Better Images of AI library have always served an important role to foster understanding and critical thinking about AI technologies and their context. Images facilitate deeper inquiries into the nature of AI, its history, and ethical, social, political and legal implications.

When artists create better images of AI, they often have to grapple with these narratives in their attempts to more realistically portray the technology and point towards its strengths and weaknesses. Furthermore, as artists freely share these images in our library, others can benefit from learning about the artist’s own internal motivations (which are provided in image descriptions) but the images can also inspire users’ own musings.

In our blog series, “Through My Eyes”, some of our volunteer stewards take turns selecting an image from the Archival Images of AI collection. They delve into the artist’s creative process and explore what the image means to them—seeing it through their own eyes.

At the end of 2024, we released the Archival Images of AI Playbook with AIxDESIGN and the Netherlands Institute for Sound and Vision. The playbook explores how existing images – especially those from digital heritage collections – can help us craft more meaningful visual narratives about AI. Through various image-makers’ own attempts to make better images of AI, the playbook shares numerous techniques which can teach you how to transform existing images into new creations. 

Here, Laura Martinez Agudelo shares her personal reflections on ‘Weaving Wires 1’ – Hanna Barakat’s own better image of AI that was created for the playbook. Laura comments on how the image uncovers the hidden Navajo women’s labor behind the assembly of microchips in Silicon Valley – inviting us to confront the oppressive cultural conditions of conception, creation and mediation of the technology industry’s approach to innovation.


Digital collage featuring a computer monitor with circuit board patterns on the screen. A Navajo woman is seated on the edge of the screen, appearing to stitch or fix the digital landscape with their hands. Blue digital cables extend from the monitor, keyboard, and floor, connecting the image elements.

Hanna Barakat + AIxDESIGN & Archival Images of AI / Better Images of AI / Weaving Wires 1 / CC-BY 4.0


Cables came out and crossed my mind 

Weaving wires 1 by Hanna Barakat is about hidden histories of computer labor. As it is explained in the image’s description, her digital collage is inspired by the history of computing in the 1960s in Silicon Valley, where the Fairchild Semiconductor company employed Navajo women for intensive tasks such as assembling microchips. Their work (actually with their hands and their digits) was a way for these women to provide for their families in an economically marginalized context.

At that time, this labor was made to be seen as a way to legitimize the transfer of the weaving cultural practices to contribute to technological innovation. This legitimation appears to be an illusion, to converge the unchanging character of weaving as heritage, with the constant renewal of global industry, but it also presupposes the non-recognition of Navajo women’s labor and a techno-cultural and gendered transaction. Their work is diluted in meaning and action, and overlooked in the history of computing.
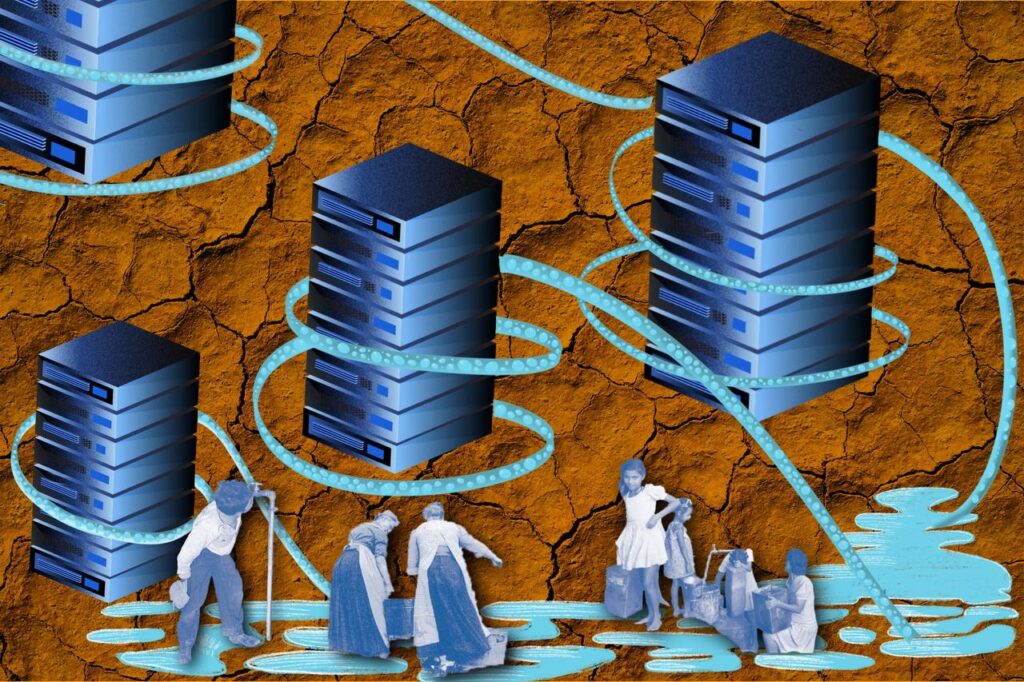
In Weaving wires 1, we can see a computer monitor with circuit board patterns on the screen, and a juxtaposed woven design. Then, two potential purposes dialogue with the woman sitting at the edge of the screen, suspended in a white background: is the woman stitching or fixing or even both as she weaves and prolongs the wires? These blue wires extend from the monitor, keyboard and beyond. The woman seems to be modifying or constructing a digital landscape with her own hands, leading us to remember the place where these materialities come from, and the memories they connect to.

Since my mother tongue is Spanish, a distant memory of the word “Navajo” and the image of weaving women appeared. “Navajo” is a Spanish adaptation of the Tewa Pueblo word navahu’u, which means “farm fields in the valley”. The Navajo people call themselves Diné, literally meaning “The People”. At this point, I began to think about the specific socio-spatial conditions of Navajo/Diné women at that time and their misrepresentation today. When I first saw the collage, I felt these cables crossing my own screen. Many threads began to unravel in my head in the form of question marks. I wondered how older and younger generations of Navajo/Diné women have experienced (and in other ways inherited) this hidden labor associated with the transformation of the valley and their community. This image disrupts as a visual opposition to the geographic and social identification of Silicon Valley as presented, for example, in the media. So now, these wires expand the materiality to reveal their history. Hanna creatively represents the connection between key elements of this theme. Let’s explore some of her artistic choices.

Recoded textures as visual extensions 

Hanna Barakat is a researcher, artist and activist who studies emerging technologies and their social impact. I discovered her work thanks to the Archival Images of AI project (Launch & Playtest). Weaving wires 1 is part of a larger project from Hanna where a creative dialogue between textures and technology is proposed. Hanna plays with intersections of visual forms to raise awareness of the social, racial and gender issues behind technologies. Weaving wires 1 reconnected me with the importance of questioning the human and material extractive conditions in which technological devices are produced.

As a lecturer in (digital) communication, I’m often looking for visual support on topics such as the socio-economic context in which the Internet appears, the evolution of the Web, the history of computer culture, and socio-technical theories and examples to study technological innovation, its problems and ethical challenges. The visual narratives are mostly uniform, and the graphic references are also gendered. Women’s work is most of the time misrepresented (no, those women in front of the big computers are not just models or assistants, they have full names and they are the official programmers and coders. Take a look at the work of Kathy/Kathryn Kleiman… Unexplored archives are waiting for us !).

When I visually interacted with Weaving wires 1 and read its source of inspiration (I actually used and referenced the image for one of my lectures), I realized once again the need to make visible the herstory (term coined in the 1960s as a feminist critique of conventional historiography) of technological innovation. Sometimes, in the rush of life in general (and in specific moments like the preparation of a lecture in my case), we forget to take some time and distance to convene other ways of exploring and sharing knowledge (with the students) and to recreate the modalities of approaching some essential topics for a better understanding of the socio-technical metamorphosis of our society.

Going beyond assumed landmarks

In order to understand hidden social realities, we might question our own landmarks. For me, “landmarks” could be both consciously (culturally) confirmed ideas and visual/physical evidence of the existence of boundaries or limits in our (representation of) reality. Hanna’s image proposes an insight into the importance of going beyond some established landmarks. This idea, as a result of the artistic experience, highlights some questions such as : where did the devices we use every day come from and whose labour created them? And in what others forms are these conditions extended through time and space, and for whom ? You might have some answers, references, examples, or even names coming to mind right now. 

In Weaving wires 1, and in Hanna’s artistic contribution, several essential points are raised. Some of them are often missing in discourses and practices of emerging technologies like AI systems : the recognition of the human labor that supports the material realities of technological tools, the intersection of race and gender, the roots of digital culture and industry, and the need to explore new visual narratives that reflect technology’s real conditions of production.
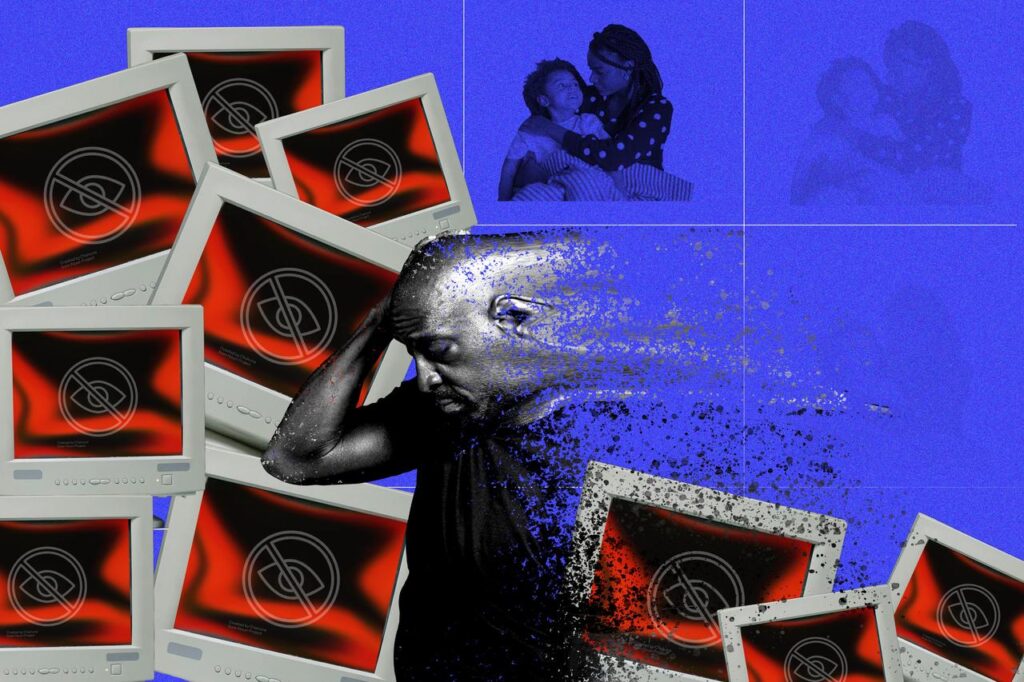
Fix, reconnect and reimagine

Hanna uses the digital collage (but also techniques such as juxtaposition, overlayering and/or distortion – she explains her approach with examples in her artist log). She explores ways to honor the stories she conjures up by rejecting colonial discourses. For me, in the case of Weaving wires 1, these wires connect to our personal experiences with technological devices and memories of the digital transformation of our society. They could also represent the need to imagine and construct together, as citizens, more inclusive (technological) futures.

A digital landscape is somewhere there, or right in front of us. Weaving wires 1 will be extended by Hanna in Weaving wives 2 to question the meaning of the valley landscape itself and its borders. For now, some other transversal questions appear (still inspired by her first image) about deterministic approaches to studying data-driven technology and its intersection with society: what fragments or temporalities of our past are we willing and able to deconstruct? Which ones filter the digital space and ask for other ways of understanding? How can we reconnect with the basic needs of our world if different forms of violence (physical and symbolic), in this case in human labor, are not only hidden, but avoided, neglected or unrepresented in the socio-digital imaginary?

It is such a necessary discussion to face our collective memory and the concrete experiences in between. Weaving wires 1 invites us to confront the oppressive cultural conditions of conception, creation and mediation of the technology industry’s approach to innovation.With this image, Hanna brings us a meaningful contribution. She deconstructs simplistic assumptions and visual perspectives to actually create ‘better images of AI’!

About the author

Laura Martinez Agudelo is a Temporary Teaching and Research Assistant (ATER) at the University Marie & Louis Pasteur – ELLIADD Laboratory. She holds a PhD in Information and Communication Sciences. Her research interests include socio-technical devices and (digital) mediations in the city, visual methods and modes of transgression and memory in (urban) art.   

This post was also kindly edited by Tristan Ferne – lead producer/researcher at BBC Research & Development.


If you want to contribute to our new blog series, ‘Through My Eyes’, by selecting an image from the Archival Images of AI collection and exploring what the image means to you, get in touch (info@betterimagesofai.org)

Explore other posts in the ‘Through My Eyes’ Series

https://thistle-oriole.pikapod.net/exploring-complexity-in-the-data-flock-by-joe-bourne/
https://thistle-oriole.pikapod.net/what-do-i-see-in-ways-of-seeing-by-zoya-yasmine/

Winners of public competition with Cambridge Diversity Fund announced

An image with the text 'Winners Announced!" at the top in maroon. Below it in slightly lighter purple text it states: 'Reihaneh Golpayegani for Women and AI' and 'Janet Turra for Ground Up and Spat Out'. Their two images are positioned on the image at a slant each in opposite directions. At the bottom, there is a maroon banner with the text 'University Diversity Fund' in white, the CFI logo in white, and the Better Images of AI logo.

At the end of 2024, we launched a public competition with Cambridge Diversity Fund calling for images that reclaimed and recentred the history of diversity in AI education at the University of Cambridge.

We were so grateful to receive such a diverse range of submissions that provided rich interpretations of the brief and focused on really interesting elements of AI history.

Dr Aisha Sobey set and judged the challenge, which was enabled by funding from Cambridge Diversity Fund. Entries were judged on meeting the brief, the forms of representation reflected in the image, appropriateness, relevance, uniqueness, and visual appeal.

We are delighted to announce the winners and their winning entries:

First Place Prize

Awarded to Reihaneh Golpayegani for ‘Women and AI’

The left side incorporates a digital interface, showing code snippets, search queries, and comments referencing Woolf’s ideas, including discussions about Shakespeare’s fictional sister, Judith. The overlay of coding elements highlights modern interpretations of Woolf’s work through the lens of data and AI.

The center depicts a dimly lit, minimalist room with a window, dessk, and wooden floors and cupboards. The right side features a collage of Cambridge landmarks, historical photographs of women, and a black and white figure in Edwardian attire. There is a map of Cambridge in the background, which is overlayed with images of old fountain pens and ink, books, and a handwritten letter.

This image is inspired by Virginia Woolf’s A Room of One’s Own. According to this essay, which is based on her lectures at Newnham College and Girton College, Cambridge University, two things are essential for a woman to write fiction: money and a room of her own. This image adds a new layer to this concept by bringing it into the Al era.

Just as Woolf explored the meaning of “women and fiction”, defining “women and AI” is quite complex. It could refer to algorithms’ responses to inquiries involving women, the influence of trending comments on machine stereotypes, or the share of women in big tech. The list can go on and involve many different experiences of women with AI as developers, users, investors, and beyond. With all its complexity, Woolf’s ideas offer us insight: Allocating financial resources and providing safe spaces-in reality and online- is necessary for women to have positive interactions with AI and to be well-represented in this field.

Download ‘Women and AI’ from the Better Images of AI library here

About the artist:

Reihaneh Golpayegani is a law graduate and digital art enthusiast. Reihaneh is interested in exploring the intersection of law, art, and technology by creating expressive artworks and pursuing my master’s studies in this area.

Commendation Prize

Awarded to Janet Turra for ‘Ground Up and Spat Out’

The outputs of Large Language Models do seem uncanny often leading people to compare the abilities of these systems to thinking, dreaming or hallucinating. This image is intended to be a tongue-in-cheek dig, suggesting that AI is at its core, just a simple information ‘meat grinder,’ feeding off the words, ideas and images on the internet, chopping them up and spitting them back out. The collage also makes the point that when we train these models on our biased, inequitable world the responses we get cannot possibly differ from the biased and inequitable world that made them.

Download ‘Ground up and Spat Out’ from the Better Images of AI library here.

About the artist:

Janet Turra is a photographer, ceramicist and mixed media artist based in East Cork, Ireland. Her fine arts career spans over 25 years, a career which has taken many turns in rhythm with the changing phases of her life. Continually challenging the concept of perception, however, her art has taken on many themes including self, identity, motherhood and more recently our perception of AI and how it relates to the female body. 

Background to the competition

Cambridge and LCFI researchers have played key roles in identifying how current stock images of AI can perpetuate negative gender and racial stereotypes about the creators, users, and beneficiaries of AI.

The winning entries will be used for outward-facing posting on social media, University of Cambridge websites, internal communications on student sites and Virtual Learning Environments. They will also be made available for wider Cambridge programs to use for their teaching and events materials. They are also both available in the Better Images of AI library here and here for anyone to freely download and use under a Creative Commons License.

“This project grew from the desire of CFI and multiple collaborations with Better Images of AI to have better images of AI in relation to the teaching and learning we do at the Centre, and from my research into the ‘lookism’ of generative AI image models. I am hopeful that the process has been valuable to illuminate different challenges of doing this kind of work and further that the images offer alternative and exciting perspectives to the representation of diversity in learning and teaching AI at the University.” – Aisha Sobey, University of Cambridge (Postdoctoral Researcher)

An additional collection of images from Hanna

As part of this project, collage artist and scholar, Hanna Barakat, was commissioned to design a collection of images which draw upon her work researching AI narratives and marginalised communities to uncover and reclaim diverse histories. You can find the collection in the Better Images of AI library and we’ll also be releasing an additional blog post which focuses on Hanna’s collection as well as the challenges/reflections on this competition brief.

Public Competition for Better Images of (teaching and learning) AI!

Ornage and red picture of people at computer terminals with networks overlaying them

Call for images: Reclaiming and Recentering the History of Diversity in AI Education at the University of Cambridge

Cambridge and LCFI researchers have played key roles in identifying how current stock images of AI can perpetuate negative gender and racial stereotypes about the creators, users, and beneficiaries of AI. Following on from this, a project has been set up to increase the visible diversity of the images used to represent AI teaching and events programs in Cambridge.

The first phase of the project was to commission exciting collage artist and emerging technologies scholar Hanna Bakarat to provide a set of images, drawing on her work of researching AI narratives to uncover and reclaim diverse histories.

We’re now delighted to collaborate to open up the challenge and to invite public submissions of ‘stock quality’ images by the 30th of December 2024 (11:59PM UTC). The competition can be entered by the University of Cambridge (UK) community, but also anyone who wishes to contribute to improving narratives about how teaching and learning about AI related fields can be conceptualised.

The recent release of the new Archival Images of AI Playbook means that even those with no artistic or design background can have a go, or existing designers and art students can bring their own ideas and add to making more inclusive and less exclusionary images.

In addition to our thanks for adding to the visual discourse, University of Cambridge have made. available a couple of prizes:

First Prize: £250

Commendation Prize: £100

Entries will be judged by representatives of Better Images of AI, LFCI and University of Cambridge.

Further Information

The Leverhulme Centre for the Future of Intelligence and the University Diversity Fund want to increase the diversity of the images that are used to represent AI-related teaching and event programmes in the University of Cambridge.

The entries will be judged on the following criteria:

  • How the images reflect the brief: ‘reclaiming and recentering the history of diversity in AI education in the University of Cambridge’
  • The inclusion of creative or surprising elements in the image
  • The appropriateness of the image to be used for teaching and events
  • The forms of representation included in the image
  • Aesthetic quality

Visual Guidelines

Please read the Guide to making Better Images of AI to see what tropes to avoid and what might make a good representation related to AI.

Image uses

These include images used for outward-facing posting on social media, University of Cambridge websites, internal communications on student sites and Virtual Learning Environments. They will also be made available for wider Cambridge programs to use for their teaching and events materials. Those agreed will also be added to the Better Images of AI website on a Creative Commons licence with artist attribution and available for wider public download.

Licences

You can use any techniques and source materials that work for your vision. However, all materials need to have the correct license for use and you need to have full ownership of the end product, so we recommend using images from the Creative Commons Portal with a ‘free to be used and remixed’ license’.
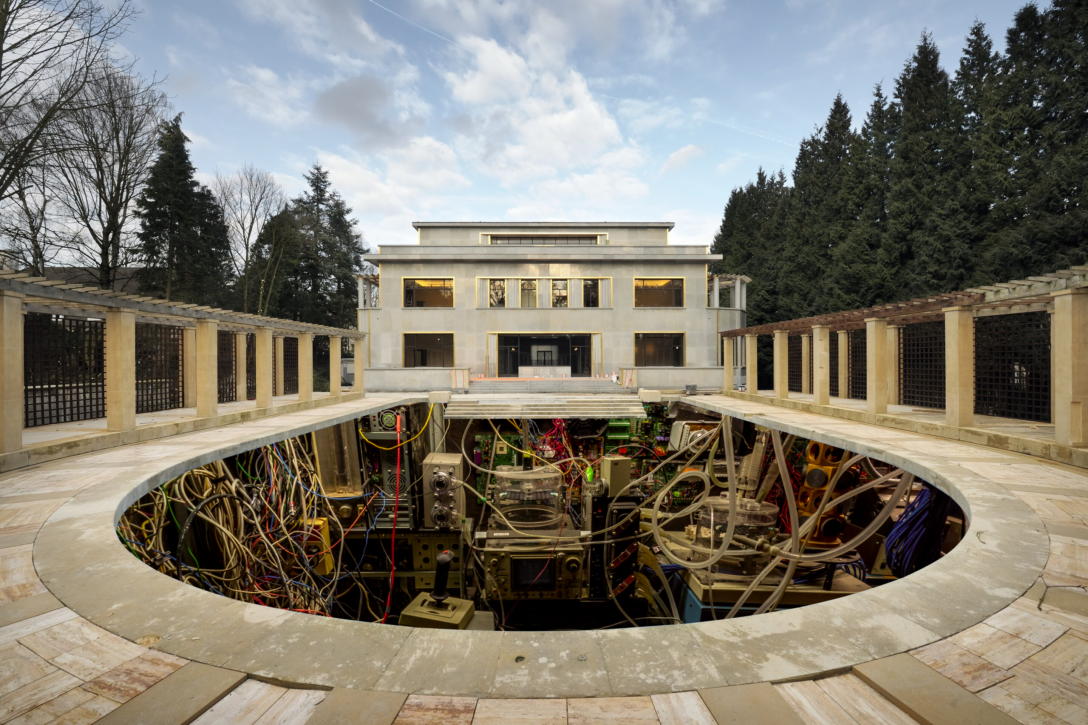
Privacy

Please also ensure to anonymise people if they are featured in images.

Techniques / style

Any techniques and approaches are welcome as long as they result in high quality digital images. This can include digital art, photography, collage, illustration and also invite artists to use different image techniques using the Archival Images of AI Playbook. We do have specifications around the use of AI image generators, see below.

AI generated Art

Although inclusion in the Better Images of AI library is not necessarily essential for the winning entry, the library will only accept submissions which use Adobe Firefly (which uses consented images, compensates artists and labels as AI generated), with licensed or original images as visual prompts.

Format

Entries must be in a .png file and submitted to info@betterimagesofai.org. The winning entries will be made available for open access use under a creative comms non-profit licence through the University of Cambridge, and ideally also in the Better Images of AI library. Entrants may also be contacted to include their image in the open-access collection with honourable mention. 
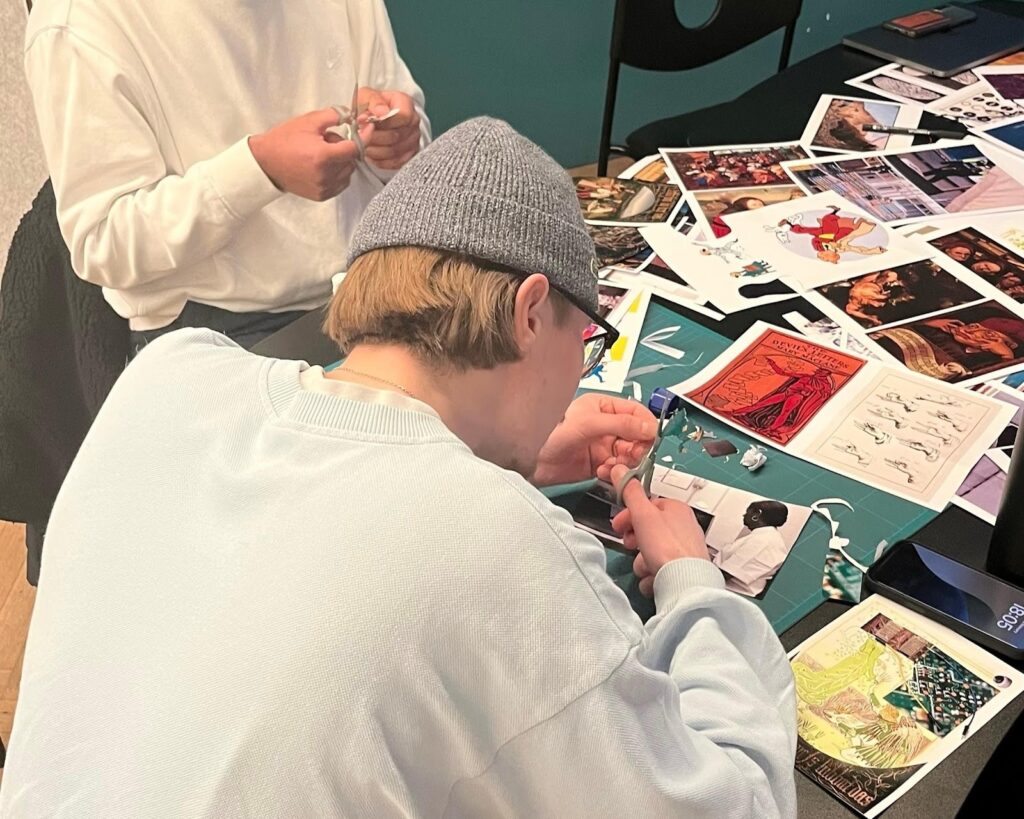
Key dates

Competition opens: 9th of December 2024 (9:00AM UTC)

Competition closes: 30th December 2024 (11:59PM UTC)

Decisions of winners announced: January 2025


Further Information

Please contact info@betterimagesofai.org.

Press release: New playbook released to enable creation of images of AI using free and open licence digital heritage collections from around the world


  • Archival Images of AI project enables the creation of meaningful and compelling images of AI
  • New playbook includes 38 pages of guidance and sources of free to use archive images
  • Showcases methods and tips for remixing archive images which can be used by anyone 
  • Inspirational artists have created free-to-use examples of their own interpretations of AI 

LONDON / AMSTERDAM 4th December 2024: As AI continues to make headlines and evolve in ways that impact the general public, global critical AI research community AIxDESIGN has released a research-informed playbook for remixing free and open licence images to create better images of artificial intelligence. It uses techniques that anyone can apply without the use of AI image generators.

Producing accurate images of AI – whether this is technically accurate or suitable for any given narrative or situation, is not always easy without an illustrator or access to a wide variety of images that can be easily edited or remixed. AIxDESIGN, in partnership with Netherlands Institute for Sound & Vision with inspiration from Better Images of AI and support from We and AI have released a playbook as a guide to address this challenge by working with free images from consented archives around the world and artists immersed in expressing their experiences and understanding of the technology.

Archival Images of AI Playbook

The playbook includes vital information about the use of archive images as well as details about the creation and representation of artificial intelligence through visual narratives. The project builds on the principles outlined in Better Images of AI: A Guide for Users and Creators that explain why accuracy is important when it comes to communicating these technologies to the wider public. 

By making poor choices about how AI is visualised, communications from media to marketing often risk misinforming or misleading the public about how it works, what it means and the impact it can have. The playbook offers new ways to interpret images of AI by engaging with cultural archives to explore historical and social context. It also has sources of visual stimuli and motifs that can be used freely and with open licences by anyone seeking to illustrate their writing or communicate AI news and reflection. 
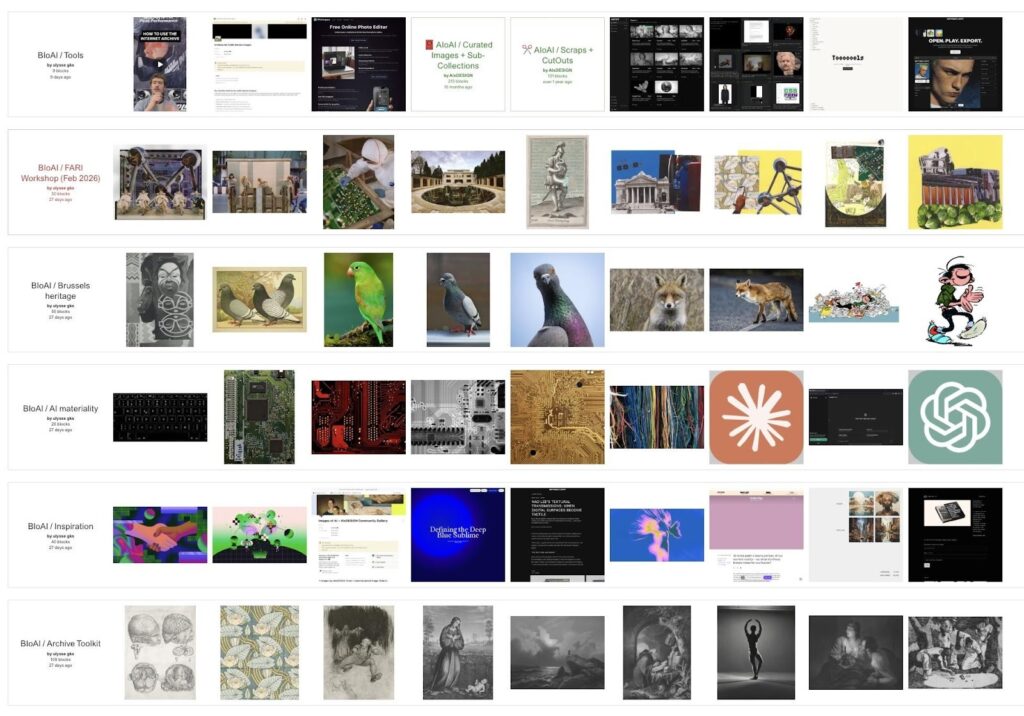
A highly creative and reflective selection of artists and researchers have contributed to the guide to offer tutorials and examples, including: 

Hanna Bakarat, researcher, activist and collage artist. She’s been deep in researching narratives of AI and exploring collage as an act of resistance. 
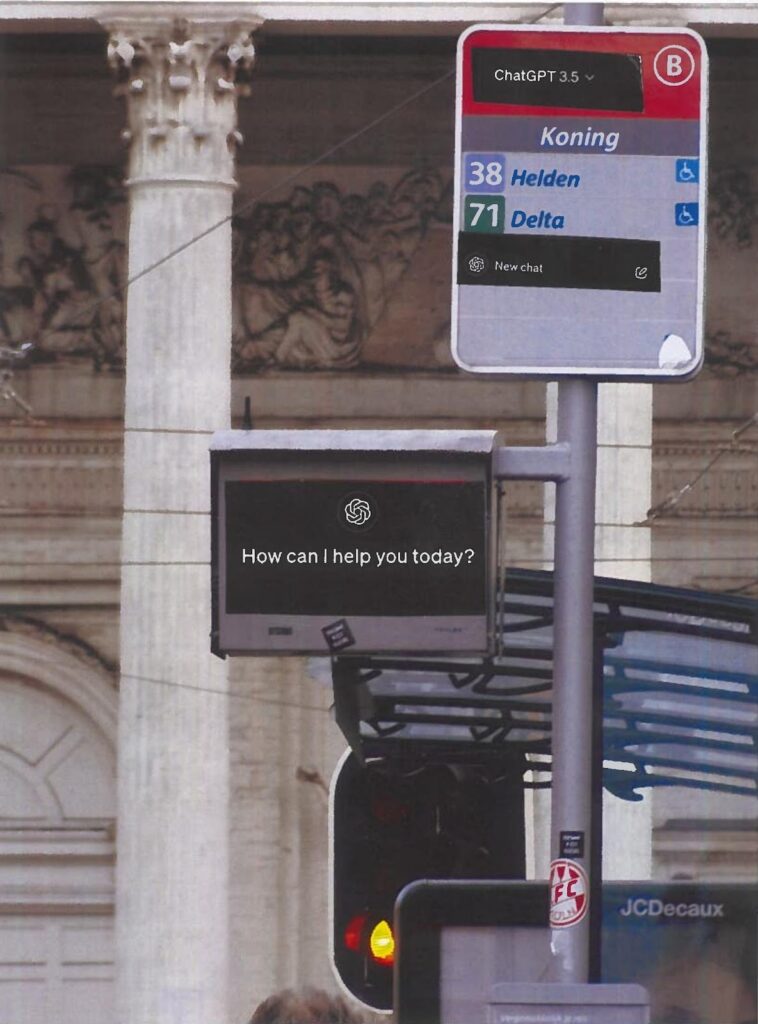
Cristóbal Ascencio, a Mexican visual artist. As a photographer, his practice explores new forms of image making such as virtual reality, data manipulation and photogrammetry. 

Zeina Saleem, graphic designer interested in data beautification and the aesthetics of algorithmic distortion. 

Dominika Čupková, interdisciplinary artist and researcher connecting the dots between AI, art, design and feminism.

Nadia Piet, Nadia is an independent researcher, designer, and co-founder and creative director of AIxDESIGN. 

The playbook is available for anyone to download and is accompanied by detailed artist logs available at https://aixdesign.co/posts/archival-images-of-ai. Readers can explore the works’ origins and development and input from Eryk Salvaggio, Cees Martens, Isabel Beirigo, Monique Groot, Danny van Zuijlen, Alice Isaac, Anne Fehres and Luke Conroy.

The playbook is launched at an interactive event where attendees have an opportunity to test and play with the techniques and interact with the artists. 

A varied and powerful selection of over 25 of the images created by the artists will be added to the free Better Images of AI image library where any individual or publication can use the images for free. 

The playbook can be downloaded at https://aixdesign.co/posts/archival-images-of-ai and https://thistle-oriole.pikapod.net/archival-images-of-ai-playbook/.

About Netherlands Sound & Vision

The Netherlands Institute for Sound & Vision is a knowledge institute in the field of media culture and audiovisual archiving. It specialises in cultural programming, educational offering and research that makes media heritage available, searchable and relevant. Learn more at https://www.beeldengeluid.nl/en. 

About AIxDESIGN 

​​​​​AIxDESIGN (AIxD) is a global community of designers, researchers, creative technologists, and activists using AI in pursuit of creativity, justice and joy and living lab exploring participatory, slow, and more-than-corporate AI. Learn more at aixdesign.co.

About Better Images of AI Better Images of AI is a global non-profit collaboration which curates and commissions stock images that avoid perpetuating unhelpful myths about artificial intelligence, downloadable for free. It provides guidelines and research and creates a space for imaging and creating more inclusive, transparent and realistic visual representations of AI themes and technologies, avoiding overused cliches and alienating, disempowering tropes. It was launched in 2021 with input from a global community of researchers, practitioners and institutions including BBC R&D and coordinated by We and AI.

📚Book Review: Screening Big Data: Films That Shape Our Algorithmic Literacy  

Drawing on films and documentaries about big data, machine learning and AI, including analysis of the sociological and critical theory of AI, ‘Screening Big Data: Films That Shape Our Algorithmic Literacy‘ by Gerald Sim discusses the role of popular media in the formation of algorithmic literacy. 

In this blog post, Jenn Chubb explains how Sim’s book provides a rich and vital analysis of the socio-political dimensions of stories and visuals about AI which challenge audiences to think more carefully about the motivations and interests behind tech-driven media.

Having spent the past few years researching stories about AI and forgotten or overlooked aspects of AI literacy, I am delighted to read Gerald Sim’s book ‘Screening big data: films that shape our algorithmic literacy.’ I have seen all of the films he discusses and have only begun to scratch the surface of the messages they propagate. In this book, Sim goes further and demonstrates in a sophisticated way how films and documentaries about AI are directing the public response. He calls for the reader to identify the influence of these stories, guiding the reader to decode the motivations and interests behind tech-driven stories. 

For those of us concerned about the imagery associated with AI, there is so much to learn from this book. In addition to framing the book in terms of ‘cinema’s reliance on visuality’, Sim writes that “research in science communication has long held that visual literacy is crucial.” In fact, the images we see on screen are an important part of how the public form opinions about technology because they are often ideologically framed and carefully curated. Understanding this requires a critical “visual literacy” and countervisuality that media scholars, drawing on film theory, use to challenge the seemingly transparent portrayals of technology in the media.

The book cover of ‘Screening Bid Data: Films That Shape Our Algorithmic Literacy’ by Gerald Sim

I will start by saying that Sim has a politically sharp lens, and skillfully makes connections between culture, technology, and politics, challenging the reader to question whose interests popular culture serves. The films in question are close readings of; ‘Minority Report’, ‘Moneyball’, ‘The Social Dilemma’ and ‘Coded Bias’, and they make for great case studies. If I am being picky, the latter documentaries carry even greater responsibility not to adopt problematic framings, which Sim acknowledges. Yet according to Sim there is a commonality; they are reflective of a network of media and technology institutions which are exerting political power in favour of their own interests. 

Screening Big Data begins with a pointed example. It’s not an example from science fiction (in fact, Sim is clear that his focus is on narrow AI and algorithms, not the stuff of superintelligence or AGI). Instead, the book begins with the example of polling data, used to exemplify that algorithms have a political and human backbone. This is a useful device, because in the same way, films don’t just entertain; they propagate powerful ideologies. For Sim, stories aren’t neutral, they’re influential and drive public attitudes, spark policy discussions, and even sway governmental perspectives. Films, documentaries, and media coverage become, as Sim frames it, cultural drivers of ideology. It is particularly refreshing to me that Screening Big Data avoids Hollywood’s usual focus on superintelligent AI tropes, such as those seen in ‘Ex Machina’ or ‘Blade Runner.’ As he rightly points out there has been great work on this by scholars working on the Global AI Narratives project and more. Instead, Sim examines narrow forms of AI and machine learning – e.g. the systems currently impacting society, from facial recognition to predictive policing. These technologies, what Cathy O’Neill called “Weapons of Math Destruction”, shape real, everyday lives in ways that go largely unexamined. 

Algorithmic and social imaginaries 

From this position, Sim borrows from Science and Technology (STS) literature and Frankfurt School of critical theory to consider the effects of film on public perception. With respect to the former, Sim argues that films contribute to what sociologists call ‘algorithmic imaginaries’ or more simply put, the ways in which one might conceptualise and understand the potential and risks of algorithms. He draws on the works of scholars like Sheila Jasanoff and Taina Bucher to explore how these cultural narratives reinforce ideas about AI’s role in society. Sim’s account of the imaginary is rich, a lesson in algorithmic literacy itself.

However, Sim also notes the narrow focus of these portrayals, which often sidelines the broader societal impacts in favour of dramatic dystopian futures or reductive narratives. As Sim implies, the stories or scenes which reinforce polarisation are often the ones that get ‘stuck’ in cultural time and space. ‘Minority Report’ is a prime example of this, often praised for its predictive depictions of technology, that of spatial computing, biometric scanners, and gesture-based interfaces, much of which has endured and entered the real world today. Such depictions stick in the public consciousness, framing technology in polarising terms – either a dystopian threat or as an empowering tool. 

Technomedia industrial complex 

I mentioned in my introduction that Sim’s argument is framed in such a way that suggests these films are reflective of a network of media and technology institutions exerting political power in favour of their own interests. He explores the ‘technomedia industrial complex’, a web of media and tech institutions, in which companies like Google, Netflix, and Facebook wield significant power. This is really at the heart of his book and I am convinced by his articulation of the films as vehicles which ‘peddle industry ideology’, technological fantasy (however prescient) and documentaries that simplify complex issues especially concerning science communication. 

One such ideology has a long history –  Films like ‘Moneyball’, for example, depict data as a ‘moral and virtuous truth,’ and present data scientists as objective crusaders while downplaying the biases and ethical questions surrounding AI. This framing resonates with me – Sim has chosen examples which exemplify the assumption that data scientists are objective number crunchers, which, he states, provides ‘cover from scrutiny’. Apparently, it’s the qualitative aspect that needs fixing, (isn’t that always the case?) – the human is qualitative, the machine is quantitative – and the human fails. Social science is in question, hard science is not. As a qualitative type who relies on ‘anecdotes and adhoc thinking’ (..!..), I am convinced that these narratives reinforce the longstanding two cultures debate. So too, they cause us to reflect on how we imagine the role of the scientist… (Clue, are they really all data geeks who can’t possibly grasp ethics…?)

One might think that including two documentaries would make for an interesting counterpoint to the stuff of fiction. However while both raise technological literacy about pervasive technologies they also arise from the techlash. Sim explains that the documentary ‘The Social Dilemma’, dramatises the dangers of algorithms but risks framing technology as something beyond human control, an idea that allows tech companies to shirk responsibility. I could not be in more agreement concerning the framing of this documentary which opens with an apology for opening Pandora’s box by the very people who opened it and plays into the tropes that humans have no control whatsoever. Meanwhile, Coded Bias’ which rightly tackles facial recognition biases can be criticised for simplifying complex geopolitical issues by focusing on surveillance concerns in countries like China without the same scrutiny on Western practices. The extent to which this is entirely supportive of our algorithmic literacy is then rightly questioned.

What difference does it make?

“The narrow truth about whether traditional film genres have been superseded may seem insignificant, but their continued relevance provides good reason to be wary of techno-determinist braggadocio and of how easy it is to be caught in the slipstream of techno-optimist celebration and techno-libertarian currents.” 

I think it’s important to note that Sim is not critical of the films for their artistic merit. He is simply calling for reflection on how they impact us. If I had to criticise, Sim’s book could focus more on the social and subtle emotional cues in the films. For instance, the dominance of white men narrating, or the manipulative musical scores directing our emotions towards the binary positions he warns us about. I might also look for further contrast in the cases used – for instance to seek counterpoints in the framings of AI across commercial vs ‘art-house’ films where intention will be very different. Perhaps that is where we might find strong examples to guide a more considered, responsible and nuanced approach to storytelling.

But that really is another story. His provocation extends beyond simply understanding AI. While critical, it is optimistic and stands for civic and public mobilisation and a shift toward resistance such as that described by scholars Dan McQuillan and Kate Crawford toward disingenuous mantras of tech companies. In fact, I take comfort in the ways that Sim frames his view of the collective response to AI. 

“If you would indulge in some optimism of a different sort, I might venture that what the integrity of genres reveals, is that we are more resilient to capitalist atomization than we realise.” 

These films direct our individual and collective response to technology, subtly encouraging acceptance or resistance. To respond requires education of algorithmic technology and an avoidance of its reification. We do well to scrutinise the technopolitics of storytelling and to critically engage with the media we consume to reveal the political and economic interests going on behind the scenes. This book is a crucial read for anyone interested in the hype of AI, and should be indispensable to anyone researching or teaching the socio-political and cultural aspects of AI in Higher Education.

Dr Jenn Chubb is a Lecturer in the Department of Sociology at the University of York, UK. Jenn’s research explores the societal and ethical implications of science and technology with a particular focus on the public perception of AI across the domains of science policy, education, health and the creative industries.

Sim, G. (2024). Screening Big Data: Films that Shape Our Algorithmic Literacy. Taylor & Francis.

You can hear more about the book on the New Books Network podcast.

👤 Behind the Image with Ying-Chieh from Kingston School of Art

This year, we collaborated with Kingston School of Art to give MA students the task of creating their own better images of AI as part of their final project. 

In this mini-series of blog posts called ‘Behind the Images’, our Stewards are speaking to some of the students that participated in the module to understand the meaning of their images, as well as the motivations and challenges that they faced when creating their own better images of AI. Based on our assessment criteria, some of the images will also be uploaded to our library for anyone to use under a creative commons licence. 

In our first post, we go ‘Behind the Images’ with Ying-Chieh Lee about her images, ‘Can Your Data Be Seen’ and ‘Who is Creating the Kawaii Girl?’. Ying-Chieh hopes that her art will raise awareness of how biases in AI emerge from homogenous datasets and unrepresentative groups of developers who can create AI to marginalise members of society, like women. 

You can freely access and download ‘Who is Creating the Kawaii Girl’ from our image library by clicking here.

‘Can Your Data Be Seen’ is not available in our library as it did not match all the criteria due to challenges which we explore below. However, we greatly appreciate Ying-Chieh letting us publish her images and talking to us. We are hopeful that her work and our conversation will serve as further inspiration for other artists and academics who are exploring representations of AI.

Can you tell us a bit about your background, and what drew you to the MA at Kingston University?

Ying-Chieh originally comes from Taiwan and has been creating art since she was about 10 years old. In her undergraduate, Ying-Chieh studied sculpture and then worked for a year. Whilst working, Ying-Chieh really missed drawing so decided to start freelance illustration but she wanted to develop her art skills further which led Ying-Chieh to Kingston School of Art. 

Could you talk me through the different parts of your images and the meaning behind them?

‘Can Your Data Be Seen?’

‘Can Your Data Be Seen?’ shows figures representing different subjects in datasets, but the cast light illustrates how only certain groups are captured in the training of AI models. Furthermore, the uniformity and factory-like depiction of the figures criticises how AI datasets often quantify the rich, lived experiences of humans into data points which do not capture the nuances and diversity of many human individuals. 

Ying-Chieh hopes that the image highlights the homogeneity of AI datasets and also draws attention to the invisibility of certain individuals who are not represented in training data. Those who are excluded from AI datasets are usually from marginalised communities, who are frequently surveilled, quantified and exploited in the AI pipeline, but are excluded from the benefits of AI systems due to the domination of privileged groups in datasets. 

‘Who’s Creating the Kawaii Girl’

In ‘Who’s Creating the Kawaii Girl’, Ying-Chieh shows a young female character in a school uniform which represents the Japanese artistic and cultural ‘Kawaii’ style. The Kawaii aesthetic symbolises childlike innocence, cuteness, and the quality of being lovable. Kawaii culture began to rise in Japan in the 1970s through anime, manga and merchandise collections – one of the most recognisable is the Hello Kitty brand. The ‘Kawaii’ aesthetic is often characterised by pastel colours, rounded shapes, and features which evoke vulnerability, like big eyes and small mouths. 

In the image, Ying-Chieh has placed the Kawaii Girl in the palm of an anonymous, sinister figure – this suggests a sense of vulnerability and power over the Girl. The faint web-like pattern on the figures and the background symbolises the unseen influence that AI has on how media is created and distributed that often reinforce stereotypes or facilitates exploitation. The image criticises the overwhelmingly male-dominated AI industry who frequently use technology and content generation tools to reinforce ideologies about women being controlled and subservient to men. For example, there has been a rise in nonconsensual deep fake pornography created by AI tools and also regressive stereotypes about gender roles being reinforced by information provided by large language models, like ChatGPT. Ying-Chieh hopes that ‘Who’s Creating the Kawaii Girl’ will challenge people to think about how AI can be misused and its potential to perpetuate harmful gender stereotypes that sexualise females. 

What was the inspiration/motivation for creating your image, ‘Can Your Data Be Seen’ and ‘Who’s Creating the Kawaii Girl?’? 

At the outset, Ying-Chieh wasn’t very familiar with AI or the negative uses and implications of the technology. To explore how it was being used, she looked on Facebook and found a group that was being used to share lots of offensive images of women which were generated by AI. When interrogating the group further, she realised that the group was not small, indeed, it had a large number of active users –  which were mostly men. This was Ying-Chieh’s initial inspiration for the image, ‘Who’s Creating the Kawaii Girl?’. 

However, this Facebook group also prompted Ying-Chieh to think deeper about how the users were able to generate these sexualised images of women and girls so easily. A lot of the images represented a very stereotypical model of attractiveness which prompted her to think about how the underlying datasets of these AI models were most probably very unrepresentative which reinforced stereotypical standards of beauty and attractiveness. 

Was there a specific reason you focussed on issues like data bias and gender oppression related to AI?

Gender equality has always been something that Ying-Chieh has been passionate about, but she had never considered how the issue related to AI. She came to realise how its relationship wasn’t that different to other industries which oppress women because AI is fundamentally produced by humans and fed by data that humans have created. Therefore, the problems with AI being used to harm women are not isolated in the technology, but rooted in systemic social injustices that have long mistreated and misrepresented women and other marginalised groups.

Ying-Chieh’s sketch of the AI ‘bias loop’

In her research stages, Ying-Chieh explored the ‘bias loop’ which represents how AI models are trained on data selected by humans or derived from historical data which will create biased images. At the same time, the images created by AI will serve as new training data, which will further embed our historical biases into future AI tools. The concept of the ‘bias loop’ resonated with Ying-Chieh’s interest in gender equality and made her concerned for the uses and developments of AI which privileging some groups at the expense of others, especially where this repeats itself and causes inescapable cycles of injustice. 

Can you describe the process for creating this work?

Ying-Chieh started from developing some initial sketches and engaging in discussions with Jane, the programme coordinator, about her work. As you can see below, ‘Whos’ Creating the Kawaii Girl’ has evolved significantly from its initial sketch but ‘Can Your Data Be Seen?’ has remained quite similar to Ying-Chieh’s original design. 

The initial sketches of ‘Can Your Data Be Seen?’ (left) and ‘Who’s Creating the Kawaii Girl?’

Ying-Chieh also engaged in some activities during classes which helped her to learn more about AI and its ethical implications. One of these games, ‘You Say, I Draw’ involved one student describing an image and the other student drawing the image purely relying on their partner’s description without knowing what they were drawing.

This game highlighted the role that data providers and prompters play in the development of AI and challenged Ying-Chieh to think more carefully about how data was being used to train content generation tools. During the game, she realised that the personality, background, and experiences of the prompter really influenced what the resulting image looked like. In the same way, the type of data and the developers creating AI tools can really influence the final outputs and results of a system. 

An image of the results from the ‘You Say, I Draw’ activity

Better Images of AI aims to counteract common stereotypes and misconceptions about AI. How did you incorporate this goal into your artwork? 

Ying-Chieh’s aim was to explore and address biases present in AI models in order to contribute to the Better Images of AI mission so that the future development of AI can be more diverse and inclusive. She hopes that her illustrations will make it easier for the public to understand issues about biases in AI which are often inaccessible or shielded from wider comprehension.

Her images draw more attention to how AI’s training data is bias and how AI is being used to reinforce gender stereotypes about women. From this, Ying-Chieh hopes that further action can be taken to improve data collection and processing methods as well as more laws and rules about limits to image generation where it exploits or harms individuals. 

What have been the biggest challenges of creating a ‘better image of AI’? Did you encounter any challenges in trying to represent AI in a more nuanced and realistic way? 

Ying-Chieh spoke about her challenges in trying to strike the right balance between designing images that could be widely used and recognised by audiences as related to AI but also not falling into any common tropes that misrepresented AI (like robots, descending code, the colour blue). She also found it difficult to not make images too metaphorical to the extent that they may be misinterpreted by audiences.

Based on our criteria for selecting images, we were pleased to accept, ‘Who’s Creating the Kawaii Girl?’, but had the difficult decision to not upload ‘Can Your Data Be Seen’ based on the fact that it didn’t communicate and conceptualise AI enough. What do you think of this feedback and was it something that you considered in the process? 


Ying-Chieh shared that she had been continuous that her images would not be easily recognisable as communicating ideas about AI throughout the design process. She made some efforts to counteract this, for example, on ‘Can Your Data Be Seen’ she made the figures all identical to represent data points and the lighter coloured lines on the faces and bodies of the figures represent the technical elements behind AI image recognition technology.

How has working on this project influenced your own views on AI and its impact? 

Before starting this project, Ying-Chieh said that her opinion towards AI had been quite positive. She was largely influenced by things that she had seen and read in the news about how AI was going to benefit society. However, from her research on Facebook, she has become increasingly aware that this is not entirely true. There are many dangerous ways that AI can be used which are already lurking in the shadows of our daily lives.

 What have you learned through this process that you would like to share with other artists or the public?

The biggest takeaway from this project for Ying-Chieh is how camera angles, zooming, or object positioning can strongly influence the message that an image conveys. For example, in the initial sketches of ‘Can Your Data Be Seen’, Ying-Chieh explored how she could best capture the relationship of power through different depths of perspective.  

Various early sketches of ‘Can Your Data Be Seen’ from different depths of perspective

Furthermore, when exploring ideas about how to reflect the oppressive nature of AI, Ying-Chieh enlarged the shadow’s presence in the frame for ‘Who’s Creating the Kawaii Girl’. By doing this, the shadow reinforces the strong power that elite groups have over the creation of content about marginalised groups which is often hidden and kept secret from wider knowledge. 

Ying-Chieh’s exploration of how the photographer’s angle can reflect different positions of power and vulnerability

Ying-Chieh Lee (she/her) is a visual creator, illustrator, and comic artist from Taiwan. Her work often focuses on women-related themes and realistic, dark-style comics.


Better Images of AI’s Partnership with Kingston School of Art

An image with a light blue background that reads, 'Let's Collab!' at the top, the word 'Collab' underlined in burgandy. Below that, it says 'Better Images of AI x Kingston School of Art' with 'Kingston School of Art' in teal. Below the text is an illustration of two hands high-fiving, with black sleeves and white hands. Around the hands are burgundy stars.

This year, we were pleased to partner with Kingston’s School of Art to run an elective for their MA Illustration, Animation, and Graphic Design students to create their own ‘better images of AI’. Following this collaboration, some of the student’s images have been published in our library for anyone to use freely. Their images focus on communicating different ideas about the current state of AI – from the connection between the technology and gender oppression to breaking down the interactions between humans and AI chatbots.

In this blog post, we speak to Jane Cheadle who is the course leader for the MA Animation course at Kingston School of Art about partnering with Better Images of AI for the elective. The MA is a new course and it is focussed on critical and research-led animation design processes.

If you’re interested in running a similar module/elective or incorporating Better Images of AI’s work into your university course, we would love to hear from you – please contact info@betterimagesofai.org.

How did the collaboration with Better Images of AI come about?

AI is having an impact on various industries and the creative domain is no exception. Jane explains how she and the staff in the department were asked to work towards developing a strategy addressing the use of AI in the design school. At the same time, Jane was also in contact with Alan Warburton – a creator that works with various technologies, including computer generated imagery, AI, virtual reality, and augmented reality to develop art. Alan introduced Jane to Better Images of AI and she became interested in the work that we are doing, and how this linked to their future strategy for the use of AI in the design school.

Therefore, instead of solely creating rules about the use of AI in the school, Jane thought that working with the students to explore the challenges, limits, and benefits of the technology would be more meaningful as it would provide better learning opportunities for the students (as well as herself!) about this topic. 

Where does the elective fit within the school’s curriculum?

Kingston University’s Town House Strategy aims to prepare graduates for advances in technology which will alter our future society and workplaces. The strategy aims to equip students with enhanced entrepreneurial, digital, and creative problem-solving skills so they can better advance their careers and professional practice. As part of this strategy, Kingston University encourages collaboration and partnership with businesses and external bodies to help advance student’s knowledge and awareness of the different aspects of the working world.

As part of this, the Kingston School of Art runs a cross-disciplinary design module open to students from three different MA courses (Graphic Design, Illustration, and Animation). In this module, students are asked to think about the role of the designer now, and what it might look like in the future. The goal is to prompt students to situate their creative practice within the contemporary paradigms of precarity and uncertainty, providing space for students to understand and address issues such as climate literacy, design education, and the future of work. There are multiple electives within this module and each works with a partner external to the university.

Better Images of AI were fortunate enough to be approached by Jane to be the external partner for their elective. This elective was run by Jane as well as researcher and artist, Maybelle Peters. Jane explains that this module had a dual aim: firstly, to allow students to develop better images of AI which could be published to our library. But also, secondly, to educate students about AI and its impact on society. For Jane, it was important that when exploring AI, this was applied to the student’s own practice and positionality so they could understand how AI is influencing the creative industry as well as political, power structures more broadly.

How did the elective run?

Jane shares that there was a real divide amongst the students about their familiarity with AI and its wider context. Some students had been dabbling with AI tools and wanted to develop a position on its creative and ethical use. Meanwhile, others were not using AI at all and expressed being somewhat weary of it, alongside a real sense of amorphous fear around automated image generation and other capabilities that impact the markets for their creative works.

Better Images of AI worked with the Kingston School of Art to provide a brief for the elective, and students also used our Guide to help them understand the problems with current stock imagery that is used to illustrate AI so they could avoid these common tropes in their own work.

Following this, the students worked in special interest groups to research different aspects of AI. Each group then used this research to develop practical workshops to run with the wider class. This enabled the students to develop their own better images of AI based on what they had learnt from leading and participating in workshops and research tasks. Better Images of AI also visited Kingston School of Art to provide guidance and feedback to the students in the development stages of their images.

Some of the images that were submitted as part of the elective can be seen below. Each image shows a thoughtful approach and are so varied in nature – some are super low-fi and others are hilarious – but all the students drew upon their own design/drawing/making skills to develop their unique images. 

Why did you think it was important to partner with Better Images of AI for this elective?

As designers and image makers, we agreed that there is a responsibility to accurately and responsibly represent aspects of the world, such as AI. It was important to allow students to work with real constraints and build towards a future that they want to live in. While the brief provided to the students was to create images that accurately represent what AI looks like right now, much of the student workshops focussed on what kind of AI they wanted to see, what safeguards need to be put in place, and what power relations we might need to change in order to get there.

Jane Cheadle (she/they) is an animator, researcher and educator. Jane is currently senior lecturer and MA Animation course leader in the design school at Kingston School of Art. Both of Jane’s practice and research are cross-disciplinary and experimental with a focus on drawing, collaboration and expanded animation.  


We are super thankful to Jane and Maybelle as well as the Kingston School of Art for incorporating Better Images of AI into their elective. We are so appreciative to all the students who participated in the module and shared their work with us. Jane is excited to hopefully run the elective again and we are looking forward to more work together with the students and staff at Kingston School of Art.

This blog post is the first in a series of posts about Better Images of AI collaboration with the Kingston School of Art. In a series of mini interview blog posts, we speak to three students that participated in the elective and designed their own better images of AI. Some of the student’s images even feature in our library – you can view them here.

Visuals of AI in the Military Domain: Beyond ‘Killer Robots’ and towards Better Images?

In this blog post, Anna Nadibaidze explores the main themes found across common visuals of AI in the military domain. Inspired by the work and mission of Better Images of AI, she argues for the need to discuss and find alternatives to images of humanoid ‘killer robots’. Anna holds a PhD in Political Science from the University of Southern Denmark (SDU) and is a researcher for the AutoNorms project, based at SDU.

The integration of artificial intelligence (AI) technologies into the military domain, especially weapon systems and the process of using force, has been the topic of international academic, policy, and regulatory debates for more than a decade. The visual aspect of these discussions, however, has not been analysed in depth. This is both puzzling, considering the role that images play in shaping parts of the discourses on AI in warfare, and potentially problematic, given that many of these visuals, as I explore below, misrepresent major issues at stake in the debate.

In this piece I provide an overview of the main themes that one may observe in visual communication in relation to AI in international security and warfare, discuss why some of these visuals raise concerns, and argue for the need to engage in more critical reflections about the types of imagery used by various actors in the debate on AI in the military.

This blog post is based on research conducted as part of the European Research Council funded project “Weaponised Artificial Intelligence, Norms, and Order” (AutoNorms), which examines how the development and use of weaponised AI technologies may affect international norms, defined as understandings of ‘appropriateness’. Following the broader framework of the project, I argue that certain visuals of AI in the military, by being (re)produced via research communication and media reporting, among others, have potential to shape (mis)perceptions of the issue.

Why reflecting upon images of AI in the military matters

As with the field of AI ethics more broadly, critical reflections on visual communication in relation to AI appear to be minimal in global discussions about autonomous weapon systems (AWS)—systems that can select and engage targets without human intervention—which have been ongoing for more than a decade. The same can be said for debates about responsible AI in the military domain, which have become more prominent in recent years (see, for instance, the initiative of the Responsible AI in the Military Domain Summit held first in 2023, with another edition due in 2024).

Yet, examining visuals deserves a place in the debate on responsible AI in the military domain. It matters because, as argued by Camila Leporace on this blog, images have a role in constructing certain perceptions, especially “in the midst of the technological hype”. As pointed out by Maggie Mustaklem from the Oxford Internet Institute, certain tropes in visual communication and reporting about AI disconnect the technological developments in that area and how people, in particular the broader public, understand what the technologies are about. This is partly why the AutoNorms project blog refrains from using the widely spread visual language of AI in the military context and uses images from the Better Images of AI library as much as possible.

Main themes and issues in visualizing military applications of AI

Many of the visuals featured in research communication, media reporting, and publications about AI in the military domain speak to the tropes and clichés in images of AI more broadly, as identified by the Better Images of AI guide.

One major theme is anthropomorphism, as we often see pictures of white or metallic humanoid robots that appear holding weapons, pressing nuclear buttons, or marching in troops like soldiers with angry or aggressive expressions, as if they could express emotions or be ‘conscious’ (see examples here and here).

In some variations, humanoids evoke associations with science fiction, especially the Terminator franchise. The Terminator is often referenced in debates about AWS, which feature in a substantial part of the research on AI in international relations, security, and military ethics. AWS are often called ‘killer robots’, both in academic publications and media platforms, which seems to encourage the use of images of humanoid ‘killer robots’ with red eyes, often originating from stock image databases (see examples here, here, and here). Some outlets do, however, note in captions that “killer robots do not look like this” (see here and here).

Actors such as campaigners might employ visuals, especially references from pop culture and sci-fi, to get people more engaged and as tools to “support education, engagement and advocacy”. For instance, Stop Killer Robots, a campaign for an international ban on AWS, often uses a robot mascot called David Wreckham to send their message that “not all robots are going to be as friendly as he is”.

Sci-fi also acts as a point of reference for policymakers, as evidenced, for example, by US official discourses and documents on AWS. As an illustration, some of these common tropes were visually present at the conference “Humanity at the Crossroads: Autonomous Weapons Systems and the Challenge of Regulation” which brought together diplomats, civil society, academia, and other actors to discuss the potential international regulation of AWS in April 2024 in Vienna.

Half-human half-robot projected on the wall and a cut-out of a metallic robot greeting participants at the entrance of the Vienna AWS conference. Photos by Anna Nadibaidze.

The colour blue also often features in visual communication about AI in warfare, together with abstract depictions of running code, algorithms, or computing technologies. This is particularly distinguishable in stock images used for blogs, conferences, or academic book cover designs. As Romele and Rodighiero write on this blog, blue might be used because it is calming, soothing, and also associated with peace, encouraging some accepting reaction from viewers, and in this way promoting certain imaginaries about AI technologies.

Examples of covers for recently published academic books on the topic of AI in international security and warfare.

There are further distinct themes in visuals used alongside publications about AI in warfare and AWS. A common trope features human soldiers in an abstract space, often with a blue (and therefore calming) background or running code, wearing a virtual reality headset and presumably looking at data (see examples here and here). One such visual was used for promotional material of the aforementioned REAIM Summit, organised by the Dutch Government in 2023.

Screenshot of the REAIM Summit 2023 website homepage (www.reaim2023.org). The image is credited to the US Naval Information Warfare Center Pacific, public domain.

Finally, many images feature military platforms such as uncrewed aerial vehicles (UAVs or drones) flying alone or in swarms, robotic ground vehicles, or quadruped animal-shaped robots, either depicted alone or together with human soldiers. Many of them are prototypes or models of existing systems tested and used by the United States military, such as the MQ-9 Reaper (which does not classify as an AWS). Most often, these images are taken from the visual repository of the US Department of Defense, given that the photos released by the US government are in the public domain and therefore free to use with attribution (see examples here, here, and here). Many visuals also display generic imagery from the military, for instance soldiers looking at computer screens, sitting in a control room, or engaging in other activities (see examples here, here, and here).

Example of image often used to accompany online publications about AWS. Source: Cpl Rhita Daniel, US Marine Corps, public domain.

However, there are several issues associated with some of the common visuals explored above. As AI researcher and advocate for an AWS ban Stuart Russell points out, references to the Terminator or sci-fi are inappropriate for the debate on AI in the military because they suggest that this is a matter for the future, whereas the development and use of these technologies is already happening.

Sci-fi references and humanoids might also give the impression that AI in the military is about replacing humans with ‘conscious’ machines that will eventually fight ‘robot wars’. This is misleading because the debate surrounding the integration of AI into the military is mostly not about robots replacing humans. Armed forces around the world plan to use AI for a variety of purposes, especially as part of humans interacting with machines, often called ‘teaming’. The debate and actors participating in it should therefore focus on the various legal, ethical, and security challenges that might arise as part of these human-machine interactions, such as a distributed form of agency.

Further, images of ‘killer robots’ often invoke a narrative of ‘uprising’ which is common in many works of popular culture and where humans lose control of AI, as well as determinist views where humans have little influence over how technology impacts society. Such visual tropes overshadow (human) actors’ decisions to develop or use AI in certain ways, as well the political and social contexts surrounding those decisions. Portraying weaponised AI in the form of robots turning against their creators problematically presents this is an inevitable development, instead of highlighting choices made by developers and users of these technologies.

Finally, many of the visuals tend to focus on the combat aspect of integrating AI in the military, especially on weaponry, rather than more ‘mundane’ applications, for instance in logistics or administration. Sensationalist imagery featuring shiny robots with guns or soldiers depicted in a theoretical battlefield with a blue background risks distracting from technological developments in security and warfare, such as the integration of AI into data analysis or military decision-support systems.

Towards better images?

It should be noted that many outlets have moved on from using ‘killer robot’ imagery and sci-fi clichés when publishing about AI in warfare. Some more realistic depictions are being increasingly used. For instance, a recent symposium on military AI published by the platform Opinio Juris features articles illustrated with generic photos of soldiers, drones, or fighter jets.

Images of military personnel looking at data on computer screens are arguably not as problematic because they convey a more realistic representation of the integration of AI into the military domain. But this still means often relying on the same sources: stock imagery and public domain websites such as the US government’s collections. It also means that AI technologies are often depicted in a military training or experimental setting, rather than a context where they could potentially be used, such as an actual conflict, not hidden with a generic blue background.

There are some understandable challenges, such as researchers not getting a say in the images used for their books or articles, or the reliance on free, public domain images, which is common in online journalism. However, as evidenced by the use of sci-fi tropes in major international conferences, a reflection on what are ‘responsible’ and ‘appropriate’ visuals for the debate on AI in the military and AWS is lacking.

Images of robot commanders, the Terminator, or soldiers with blue flashy tablets miss the point that AI in the military is about changing dynamics of human-machine interaction, which involve various ethical, legal, and security implications for agency in warfare. As with images of AI more broadly, there is a need to expand the themes in visuals of AI in security and warfare, and therefore also the types of sources used. Better images of AI would include humans who are behind AI systems and humans that might be potentially affected by them—both soldiers and civilians (e.g. some images and photos depict destroyed civilian buildings, see here, here, or here). Ultimately, imagery about AI in the military should “reflect the realistically messy, complex, repetitive and statistical nature of AI systems” as well as the messy and complex reality of military conflict and the security sphere more broadly.

The author thanks Ingvild Bode, Qiaochu Zhang and Eleanor Taylor (one of our Student Stewards) for their feedback on earlier drafts of this blog. 

Better Images of AI’s Student Stewards

Better Images of AI is delighted to be working with Cambridge University’s AI Ethics Society to create a community of Student Stewards. The Student Stewards are working to empower people to use more representative images of AI and celebrate those who lead by example. The Stewards have also formed a valuable community to help Better Images of AI connect with its artists and develop its image library. 

What is Cambridge University’s AI Ethics Society? 

The Cambridge University AI Ethics Society (CUAES) is a group of students from the University of Cambridge who share a passion for advancing the ethical discourse surrounding AI. Each year, the society choses a campaign to support and introduces its members to the issues that these organisations are trying to solve through events and workshops. In 2023, CUAES supported Stop Killer Robots. This year, the Society chose to support Better Images of AI. 

The Society’s Reasons for Supporting Better Images of AI 

The CUAES committee really resonated with Better Images of AI’s mission. The impact that visual media can have on public discourse about AI has been overlooked – especially in academia where there is a focus on written word. Nevertheless, stock images of humanoid robots, white men in suits and the human brain all embed certain values and preconceptions about what AI is and who makes it. CUAES believes that Better Images of AI can help cultivate more thoughtful and constructive discussions about AI. 

Members of the CUAES are privileged enough to be fairly well-informed about the nuances of AI and its ethical implications. Nevertheless, the Society has recognised that even its own logo of a robot incorporates reductive imagery that misrepresents the complexities and current state of AI. Therefore, from oversights in its own decisions, CUAES saw that further work needed to be done.

CUAES is eager to share the importance of Better Images of AI to industry actors, but also members of the public whose perceptions will likely be shaped the most by these sensationalist images. CUAES hopes that by creating a community of Student Stewards, they can disseminate Better Images of AI’s message widely and work together to revise their logo to better reflect the Society’s values. 

The Birth of the Student Steward Initiative

Better Images of AI visited the CUAES earlier this year to introduce members to its work and encourage students to think more critically about how AI is represented. During the workshop, participants were given the tough task to design their own images of AI – we saw everything from illustrations depicting how generative AI models are trained to the duality of AI being symbolised by the ying and yang. The students who attended the workshop were fascinated by Better Images of AI’s mission and wanted to use their skills and time to help – this was the start of the Student Steward community. 

A few weeks after this workshop, individuals were invited to a virtual induction to become Student Stewards so they could introduce more nuanced understandings of AI to the wider public. Whilst this initiative has been borne out of CUAES, students (and others) from all around the globe are invited to join the group to shape a more informed and balanced public perception of AI.

The Role of the Student Stewards

The Student Stewards are on the frontline of spreading Better Images of AI’s mission to journalists, researchers, communications professionals, designers, and the wider public. Here are some of the roles that they champion: 

  1. The Guidance Role: if our Student Stewards see images of AI that are misleading, unrepresentative or harmful, they will attempt to contact authors and make them aware of the Better Images of AI Library and Guide. The Stewards hope that they can help to raise awareness of the problems associated with the images used and guide authors towards alternative options that avoid reinforcing dangerous AI tropes. 
  1. The Gratitude Role: we realise that it is equally as important to recognise instances where authors have used images from the Better Images of AI library. Images from the library have been spotted in international media, adopted by academic institutions and utilised by independent writers. Every decision to opt for more inclusive and representative images of AI plays a crucial role in raising awareness of the nuances of AI. Therefore, our Stewards want to thank authors for being sensitive to these issues and encourage the continuous of the library. 
  1. Connecting with artists: the stories and motivations behind each of the images in our library are often so interesting and thought provoking. Our Student Stewards will be taking the time to connect with artists that contribute images to our library. By learning more about how artists have been inspired to create their works, we can better appreciate the diverse perspectives and narratives that these images provide to wider society. 
  1. Helping with image collections: Better Images of AI carefully selects the images that are chosen to be published in its library. Each image is scrutinised against the different requirements to ensure that they avoid reinforcing harmful stereotypes and embody the principles of honesty, humanity, necessity and specificity. Our Student Stewards will be assisting with many of the tasks that are involved from submission to publication, including liaising with artists, data labelling, evaluating initial submissions, and writing image descriptions. 
  1. Sharing their views: Each of our Student Stewards come with different interests related to AI and its associated representations, narratives, benefits and challenges. We are eager for our students to share their insights on our blog to introduce others to new debates and ideas in these domains.

As Better Images of AI is a non-profit organisation, our community of Stewards operate on a voluntary basis but this does allow for flexibility around your other commitments. Stewards are free to take on additional tasks based on their own availability and interests and there are no minimum time requirements for undertaking this role – we are just grateful for your enthusiasm and willingness to help! 

If you are interested in becoming a Student Steward at Better Images of AI, please get in touch. You do not need to be affiliated with the University of Cambridge or be a student to join the group.

Open Call for Artists | Apply by 25th September

A! x Design Open call poster - We now invite Artists from EU and affiliated countries to join the Open Call

We and AI have teamed up with AIxDesign to commission three artists to encourage a better understanding of AI. Thanks to AI4Media’s support, each of the successful artists will be offered a €1,500 stipend for their contributions. The resulting images will be added to the Better Images of AI gallery for free and public use.

The main aim is to create a set of imagery that avoids perpetuating unhelpful myths about artificial intelligence (AI) by inviting artists from different backgrounds to develop better images while tackling questions such as:

  • Is the image representing a particular part of the technology or is it trying to tell a wider story?
  • Does it help people understand the technology and is it an accurate representation?

Each commissioned artist will work independently to create images, meeting two times with the project team to present concepts, ask questions, and receive feedback as we iterate towards the final images.

If you find this challenge exciting, take a look at the 🔗open call and apply by 25th September (midnight, CET)!

The wonderful team at AIxDESIGN are also running a series of info sessions throughout September in case you want to know more:

  • 7th September, 6pm CET / 12pm EST / 9am PST
  • 14th September, 11am CET / 6pm Philippines
  • 21st September, 6pm CET / 12pm EST / 9am PST

To join one of the info sessions, follow the “Open call and application” button above and find the RSVP links under “Project timeline”.

Since 2021, We and AI have been curating informative and engaging images through the Better Images of AI project. Better Images of AI challenges common misconceptions about AI, thereby enabling more fruitful discussions. Our continued public engagement initiatives and research have shown that images for responsible and explainable AI are still hard to come by, and we always welcome artists to help solve this problem. The challenges posed in the open call result from research conducted in collaboration with AI4Media and funded by AHRC.

AIxDESIGN are a self-organised community of over 8,000 computationally curious people who work in the open and are dedicated to conducting critical AI design research for people (not profit). We warmly welcome their alliance, and their continued work informing AI with feminist thought and a philosophy of care.

We also applaud AI4Media’s efforts not only to encourage and enable the development and adoption of AI systems across media industries, but also to engage with how the media can better represent AI.

Image by Alan Warburton / © BBC / Better Images of AI / Nature / CC-BY 4.0

Illustrating Data Hazards

A person with their hands on a laptop keyboard is looking at something happening over their screen with a worried expression. They are white, have shoulder length dark hair and wear a green t-shirt. The overall image is illustrated in a warm, sketchy, cartoon style. Floating in front of the person are three small green illustrations representing different industries, which is what they are looking at. On the left is a hospital building, in the middle is a bus, and on the right is a siren with small lines coming off it to indicate that it is flashing or making noise. Between the person and the images representing industries is a small character representing artificial intelligence made of lines and circles in green and red (like nodes and edges on a graph) who is standing with its ‘arms’ and ‘legs’ stretched out, and two antenna sticking up. A similar patten of nodes and edges is on the laptop screen in front of the person, as though the character has jumped out of their screen. The overall image makes it look as though the person is worried the AI character might approach and interfere with one of the industry icons.

We are delighted to start releasing some useful new images donated by the Data Hazards project into our free image library. The images are stills from an animated video explaining the project, and offer a refreshing take on illustrating AI and data bias. They take an effective and creative approach to making visible the role of the data scientist and the impact of algorithms, and the project behind the images uses visuals in order to improve data science itself. Project leaders Dr Nina Di Cara and Dr Natalie Zelenka share some background on Data Hazards labels, and the inspiration behind the animation behind the new images.

Data science has the potential to do so much for us. We can use it to identify new diseases, streamline services, and create positive change in the world. However, there have also been many examples of ways that data science has caused harm. Often this harm is not intended, but its weight falls on those who are the most vulnerable and marginalised. 

Often too, these harms are preventable. Testing datasets for bias, talking to communities affected by technology or changing functionality would be enough to stop people from being harmed. However, data scientists in general are not well trained to think about ethical issues, and even though there are other fields that have many experts on data ethics, it is not always easy for these groups to intersect. 

The Data Hazards project was developed by Dr Nina Di Cara and Dr Natalie Zelenka in 2021, and aims to make it easier for people from any discipline to talk together about data science harms, which we call Data Hazards. These Hazards are in the form of labels. Like chemical hazards, we want Data Hazards to make people stop and think about risk, not to stop using data science at all. 

An person is illustrated in a warm, cartoon-like style in green. They are looking up thoughtfully from the bottom left at a large hazard symbol in the middle of the image. The Hazard symbol is a bright orange square tilted 45 degrees, with a black and white illustration of an exclamation mark in the middle where the exclamation mark shape is made up of tiny 1s and 0s like binary code. To the right-hand side of the image a small character made of lines and circles (like nodes and edges on a graph) is standing with its ‘arms’ and ‘legs’ stretched out, and two antenna sticking up. It faces off to the right-hand side of the image.
Yasmin Dwiputri & Data Hazards Project / Better Images of AI / Managing Data Hazards / CC-BY 4.0

By making it easier for us all to talk about risks, we believe we are more likely to see them early and have a chance at preventing them. The project is open source, so anyone can suggest new or improved labels which mean that we can keep responding to new and changing ethical landscapes in data science. 

The project has now been running for nearly two years and in that time we have had input from over 100 people on what the Hazard labels should be, and what safety precautions should be suggested for each of them. We are now launching Version 1.0 with newly designed labels and explainer animations! 

Chemical hazards are well known for their striking visual icons, which many of us see day-to-day on bottles in our homes. By having Data Hazard labels, we wanted to create similar imagery that would communicate the message of each of the labels. For example, how can we represent ‘Reinforces Existing Bias’ (one of the Hazard labels) in a small, relatively simple image? 

Icon

Description automatically generated
Image of the ‘Reinforces Existing Bias’ Data Hazard label

We also wanted to create some short videos to describe the project, that included a data scientist character interacting with ‘AI’ and had the challenge of deciding how to create a better image of AI than the typical robot. We were very lucky to work with illustrator and animator Yasmin Dwiputri, and Vanessa Hanschke who is doing a PhD at the University of Bristol in understanding responsible AI through storytelling. 

We asked Yasmin to share some thoughts from her experience working on the project:

“The biggest challenge was creating an AI character for the films. We wanted to have a character that shows the dangers of data science, but can also transform into doing good. We wanted to stay away from portraying AI as a humanoid robot and have a more abstract design with elements of neural networks. Yet, it should still be constructed in a way that would allow it to move and do real-life actions.

We came up with the node monster. It has limbs which allow it to engage with the human characters and story, but no facial expressions. Its attitude is portrayed through its movements, and it appears in multiple silly disguises. This way, we could still make him lovable and interesting, but avoid any stereotypes or biases.

As AI is becoming more and more present in the animation industry, it is creating a divide in the animation community. While some people are praising the endless possibilities AI could bring, others are concerned it will also replace artistic expressions and human skills.

The Data Hazard Project has given me a better understanding of the challenges we face even before AI hits the market. I believe animation productions should be aware of the impact and dangers AI can have, before only speaking of innovation. At the same time, as creatives, we need to learn more about how AI, if used correctly, and newer methods could improve our workflow.”

Yasmin Dwiputri

Now that we have the wonderful resources created we have been able to release them on our website and will be using them for training, teaching and workshops that we run as part of the project. You can view the labels and the explainer videos on the Data Hazards website. All of our materials are licensed as CC-BY 4.0 and so can be used and re-used with attribution. 

We’re also really excited to see some on the Better Images of AI website, and hope they will be helpful to others who are trying to represent data science and AI in their work. A crucial part of AI ethics is ensuring that we do not oversell or exaggerate what AI can do, and so the way we visualise images of AI is hugely important to the perception of AI by the public and being able to do ethical data science! 

Cover image by Yasmin Dwiputri & Data Hazards Project / Better Images of AI / AI across industries / CC-BY 4.0

Launch of a Guide for Users and Creators of Images of AI

Some screenshots of the new Better Images of AI Guide fr Users and Creators

On 24 January, the Better Images of AI project launched a Guide for Users and Creators of images of AI at a reception in London. The aim of the Guide is to lay out some key findings from Dr Kanta Dihal’s research Better Images of AI: Research-Informed Diversification of Stock Imagery of Artificial Intelligence, in a format which makes it easy for users, creators and funders of images relating to AI to refer to. 

Mark Burey, Head of Marketing and Communications at the Alan Turing Institute, welcomed an audience of AI communicators, researchers, journalists, practitioners and ethicists. The Alan Turing Institute, the UK’s national institute for data science and artificial intelligence, hosted the event and is one of the Better Images of AI’s key founding supporters.

Dr Kanta Dihal at the Leverhulme Centre for the Future of Intelligence, the University of Cambridge, introduced the Guide, summarised the contents, and gave an overview of the research project. 

Dr Kanta Dihal presents the new Better Images of AI guide at the Turing Institute

This Guide presents the results of a year-long study into alternative ways of creating images of AI. The research, led by Dr Dihal, included roundtable and workshop conversations with over 100 experts from a range of different fields. Participants from media and communications, the tech sector, policy, research, education and the arts dug down into the issues surrounding how we communicate visually and appraised the utility and impact of the images already published in the Better Images of AI library.

Dr Dihal took the opportunity to thank the many research participants in attendance, as well as the team at We and AI who coordinated the Arts and Humanities Research funded project, and expressed appreciation to BBC R&D for donations in kind.

Finishing the presentations was Tania Duarte, who managed the research project team at We and AI and who also coordinates the global community which makes up the Better Images of AI collaboration. Tania highlighted the contributions of the volunteers and non-profit organisations who have contributed to the mission to explore how to create more realistic, varied and inclusive images of AI. Their drive to address various issues caused by the misconceptions fuelled by current trends in visual messaging about AI has been inspiring and informative.

Tania expressed the hope that recommendations from Dr Dihal’s new research will motivate funders and sponsors to support the Better Images of AI project to be able to meet the demand for more images. The Guide describes the need expressed by participants’ images of a greater diversity of perspectives, covering more topics, and offering more image choices within those topics. This need is also voiced by the users of the gallery, a selection of which Tania shared during the presentation, many of which have now used all the images and have yet to easily find more.

Logos of various organisations and publications which have used images from the Better Images of AI library
Organisations which have used images from the Better Images of AI library

The Q&A with the audience became a fascinating discussion with the expert audience, with topics including the use of AI-generated images, typing robots to illustrate ChatGPT and the design of assistive robots.

A pdf version of Better Images of AI: A Guide for Users and Creators is now available to download here.

You can download images free on Creative Commons licences here.

For more detailed advice on creating specific briefs and working with designers, the team at Better Images of AI can be commissioned to work on visual communications projects.

Once again, we thank the research participants, attendees, project team and wider community for helping to provide this Guide, which we hope will help increase the provision and use of better images of AI!

What do children think AI looks like?

Selection of Post-It notes representing childrens views of AI

The BBC Research and Development team asked hundreds of children this question as part of their Get Curious event at the Manchester Science Festival. The event aimed to help children and families understand what AI is and share the interesting ways that it is used at the BBC.

“What do you think AI looks like?”

That was the question we posed to hundreds of children and families passing through the 2022 Manchester Science Festival at the Science and Industry Museum. Representing the work of BBC R&D, we set up shop in the main hall, primed with demos of intelligent wildlife cameras used on BBC productions, and interactive games that explain how AI works.

However, one task was something that all ages could have a go at. We handed each passerby a post it note, asked them to draw what they thought artificial intelligence looked like, and encouraged them to stick it on our wall of AI images.

As well as being an artsy refuge from the busy museum, this collective mind map-come-collaborative art project had a purpose. We wanted to to see how early unhelpful AI image tropes set in, and explore what inspiration can be taken from the youngest of all generations in creating Better Images of AI.

So, with an empty wall, we started collecting drawings.

With such a range of ages and understanding of artificial intelligence, a lot of this exercise involved the team helping kids understand what AI is and where they might come across it. Getting a 7-year-old to understand what you meant by AI called for a lot of obvious reference points. Talking about apps on smartphones, and voice assistants like Alexa both proved to be useful, and of course, robots! As a result, plenty of sketches of iPads, smart speakers and wacky androids lined the wall.

Some drawings were also inspired by our other activities demonstrating AI. Many latched on to the idea of birds and smart cameras from our wildlife identification demo. A few also tried to represent the confusion seen when AI comes across something it is not trained to recognise.

The older children at the festival were also curious about what was going on under the hood. “But how does it actually work?”. These explanations and discussions prompted more literal interpretations of what AI looks like. An overworked laptop, computer chips and even sketches of the streams of coded data.

A number of drawings pulled from the biological tropes of AI, including the classic disembodied brain to make a comparison with human intelligence. Another sketch used a DNA double helix, presumably to represent a kind of ‘programmed’ intelligence. Other less helpful tropes also emerged; to one participant, the answer to “what do you think AI looks like?” was the Meta logo.

My favourite image of AI from the festival came from a father trying to explain AI to his son. “AI is just like…” He paused, before suggesting:

“Magic?”

The two then sketched an image that perfectly encapsulated the wonder of AI, along with the mystery that many feel when faced with results from ‘black box’ algorithms. A rabbit appearing from a magician’s hat. 

At the end of the day, we were left with a wall containing over one hundred creative images of AI. I was also left with two conclusions. Firstly, people’s images of AI are shaped heavily by how AI has been explained to them. If the explanation contains certain tropes, so will their understanding of what AI looks like.

Secondly, asking children, families, and other non-technical people the simple question of “what do you think AI looks like?” showed how curious the public really are about AI. The imaginative responses to this question provide fresh inspiration of what to do — and what not to do — when creating images of AI.

About the Authors

Ben Hughes is a research engineer at BBC R&D. His work in AI and ML has involved research in music information retrieval and creating experiences for explaining machine learning to the general public. The latter work has led to school workshops and outreach on AI education.

Tristan Ferne is the lead producer for the Internet Research & Future Services team where he develops and runs projects that use technology and design to prototype the future of media. He has over 15 years experience in R&D for the web, TV and radio. 

Learn more about this project

This project was conducted as part of a BBC R&D’s Get Curious event at the Manchester Science Festival. The event aimed to help children and families understand what AI is and share the interesting ways that it is used at the BBC.

Three new Better Images of AI research workshops announced

LCFI Research Project l FINAL WORKSHOPS ANNOUNCED! Calling all journalists, AI practitioners, communicators and creatives! (Event poster in Better Images of AI blue and purple colours, with logos)

Three new workshops have been announced in September and October by the Better Images of AI project team. We will once again bring a range of AI practitioners and communicators together with artists and designers working in different creative fields,  to explore in small groups how to represent artificial intelligence technologies and impacts in more helpful ways.

Following a first insightful initial workshop in July, we’re inviting anyone in relevant fields to apply to join the remaining workshops,- taking place both online and in person. We are particularly interested in hearing from journalists who write about AI. However if you are interested in critiquing and exploring new images in an attempt to find more inclusive, varied and realistic visual representations of AI, we would like to hear from you!

Our next workshops will be held on:

  • Monday 12 September, 3.30 – 5.30pm UTC+1 – ONLINE
  • Wednesday 28 September, 3 – 5pm UTC+1 – ONLINE
  • Thursday 6 October, 2:30 – 4:30pm UTC+1 – IN PERSON – The Alan Turing Institute, British Library 96 Euston Road London NW1 2DB

If you would like to attend or know anyone in these fields, email research@betterimagesofai.org, specifying which date. Please include some information about your current field and ideally a link to an online profile or portfolio.

The workshops will look at approaches to meet the criteria of being a ‘better image of AI’, identified by stakeholders at earlier roundtable sessions. 

The discussions in all four workshops will inform an Arts and Humanities Research Council-funded research project undertaken by the Leverhulme Centre for the Future of Intelligence, the University of Cambridge and organised by We and AI. 

Our first workshop was held on 25 July, and brought together over 20 individuals from creative arts, communications, technology and academia to discuss sets of curated and created images of AI and to explore the next steps in meeting the needs identified in providing better images of AI moving forward. 

The four workshops follow a series of roundtable discussions, which set out to examine and identify user requirements for helpfully communicating visual narratives, metaphors, information and stories related to AI. 

The first workshop was incredibly rich in terms of generating creative ideas and giving feedback on gaps in current imagery. Not only has it surfaced lots of new concepts for the wider Better Images of AI to work on, but the series of workshops will also form part of a research paper to be published in January 2023. This process is really critical to ensuring that our mission to communicate AI in more inclusive, realistic and transparent ways is informed by a variety of stakeholders and underpinned by good evidence.

Dagmar Monett, Head of the Computer Science Department at Berlin School of Economics and Law and one of the July workshop attendees, said: “”Better Images of AI also means better AI: coming forward in AI as a field also means creating and using narratives that don’t distort its goals nor obscure what is possible from its actual capacities. Better Images of AI is an excellent example of how to do it the right way.”

The academic research project is being led by Dr Kanta Dihal, who has published many related books, journal articles and papers related to emerging technology narratives and public perceptions.

The workshops will ultimately contribute to research-informed design brief guidance, which will then be made freely available to anyone commissioning or selecting images to accompany communications – such as news articles, press releases, web communications, and research papers related to AI technologies and their impacts. 

They will also be used to identify and commission new stock images for the Better Images of AI free library.

To register interest: Email our team at research@betterimagesofai.org, letting us know which date you’d like to attend and giving us some information about your current field as well as a link to your LinkedIn profile or similar.

Dreaming Beyond AI

Dreaming Beyond AI is a multi-disciplinary and collaborative web-based project bringing together artists, researchers, activists, and policymakers to create new narratives and visions around AI technologies. The project aims to enable understanding of the impact AI technologies have on inequity, and questioning mainstream AI narratives as well as imposed visions of the future.

I spoke to Nushin Yazdani, Raziye Buse Çetin and Iyo Bisseck about their approaches to visualizing different aspects of AI and the challenge of imagining plural and positive visions of our future with technology.


Alexa: How would you describe “Dreaming Beyond AI” in your own words?

Iyo: Fluidity.

Nushin: Liquidity.

Nushin: Maybe also: Making the interdependencies visible, going away from this top-down, either-or. That’s what we’re aiming for: The pluriverse of ideas, visions, and narratives.

Buse: The process of collaboration is also something that we paid attention to and thought about how we can do it differently. We thought about how can we embody the values we are preaching, like intersectionality, and inclusivity, against patriarchal white supremacist work culture that is focused on productivity and past record of institutionalized success. We have been lucky enough to receive support for this project. I have been invited by Nushin to the project although I  had not been involved with projects at the intersection of tech & art before; so when we were choosing our collaborators and artists we also asked how can we extend the same values and trust, how can we minimize our attachment to patriarchal, capitalist parameters of “success” and “reliability”?

Alexa: That was also my impression, that it’s less than a website and more like a platform that invites people to contribute…

Buse: I am a bit cautious with the word “platform”. I mean we’re still using this term but trying to find another, similar to a “container”, a “space”, a recipient for people to come together in a way that makes their work, contributions, stories, and standpoints visible.

Nushin: The wish or idea for us is – I can speak for the whole group I think – this is not something that we only invite people to but that people can also approach us with their ideas and their wishes. We can make it, as Buse said, like a container, so everybody can fill it, not just us. Not in a kind of exclusive way but more everybody is invited to contribute.

Alexa: I am intrigued by this “container” term, it appears a lot, also as kind of a metaphor for technology in general. Compared to this idea of technology as a stick, a weapon, this tool thingy – the opposite would be the container. There is this sci-fi author, Ursula LeGuin. You told me that her essay “The carrier bag theory of fiction” from 1986 was one of the foundational inspirations for the project. Could you tell me more about how it matters to you?

Ursula Le Guin
Picture of Sci-Fi author Ursula Le Guin (by: Marian Wood Kolisch, Oregon State University,CC BY-SA 2.0, via Wikimedia Commons)

Buse: Of course! Ursula LeGuin says that maybe the first technology that we had was not a weapon but a recipient, a carrier bag in which we could collect our things, because we were living as nomads, going from place to place. What is a more important invention than this?

We thought that this approach is missing when we talk about technology in the sense of “go fast and break things” and “disrupt” and aggressively change the market, predict and optimize, etc. We need to come back and go deeper into creating space for other visions.

Scene from “2001 - A space odyssey” - The monkeys found a bone and start hitting each other
Scene from “2001 – A space odyssey” – The monkeys find a bone and start hitting each other

When we think about what is considered a technology, I feel it’s very much gendered and intertwined with capitalism and this myth of weapons. If you look at the most developed AI applications it’s in the domain of the military. The military applications of technology basically drive where technology is going overall. And I go into a little bit of a spiritual realm with this but for me it also makes me think of masculine and feminine energy. Not in the sense of gender but maybe like “yin and yang” in Eastern spiritual traditions. In the sense that one is outwards looking and outwards going, achieving, going to Mars, etc. While the other is mostly… magnetic, receptive, and reflective, and creates nothingness but space within that nothingness… nurturing like nature, the Earth, and similar archetypes.

Alexa: When you said the words “magnetic” and “receptive” and “fluidity” I really felt the links to the visuals! These concepts are very well reflected in the designs. What was the process of transforming the visual concepts into the actual design and 3D graphics?

Iyo: It was a bit complicated because we wanted our design to be accessible in a way. The real question was how to create an experience while still letting the opportunity for people that are not comfortable with technology just try it. We talked about relationality and ll the things being related and connected. We wanted to avoid the image of the brain to represent AI because it lacks the potential for transformation. I talk about fluidity because we really like the water as a way to be one at the moment and alone at another moment, and have the possibility to connect and disconnect and see it through time.

Nushin: Maybe I can add to the water imagery a little bit. There is such a whole body of knowledge but our idea is to elevate some drops of knowledge that we think are in this context missing but really important to showcase which are other narratives of what AI could be. Of what technology could be for us. Showing specific drops of ideas that come from this whole collective knowledge of the world, from different places. Showing knowledge that is maybe not the knowledge of academia or what the industry accepts as proper knowledge.

Screenshot of "Dreaming Beyond AI"
Screenshot of “Dreaming Beyond AI” (experiential Pluriverse view)

Alexa: Was there concrete inspiration in terms of visual vibe?

Nushin: As Buse said, this idea of Ursula Le Guin’s contrary to this vision of what is technology as something that has corners or is fixed or is a concrete thing.. we tried to turn it around visually and bring it closer to nature and making it this thing that is maybe not hard and pointy and hurtful but more something that is soft and can adjust to things that are coming, is flexible…

Buse: We also want to help and support people to understand what AI is. The project aimyths.org is a great inspiration for that too. Understanding what is actually happening, questioning, beyond technology. For example when we’re discussing “algorithmic bias” it’s a question of social justice and inequity in our systems, and not only something that is in the interpersonal realm. And we were thinking about how to design a space where everything can coexist. We thought of visiting the website as a journey for the navigator. The first frame when you enter the website represents the status quo. Then you go into the Pluriverse – that’s also a reference that we like, it is a term that comes from Arturo Escobar’s thinking. How things are connected to each other, the patterns in each water drop. It’s basically linked to the topic that we are exploring.

Alexa: I am curious about your thoughts regarding the designs/moods of the different sections/aspects (e.g. “Intelligence”, “Patterns”)! How did you come up with the specific designs and colour schemes? What were you aiming to communicate?

Buse: In general we wanted the visual imagery to be “reminiscent” of the themes (e.g. “AI violence”, “intelligence” etc.) that we were exploring. When this is not easy or when we were actually trying to question, unpack, (re)define the usual interpretations of these concepts we sometimes also opted for what would be perceived as “the opposite” or “not usual” way of depicting the concept in question. Different colours, patterns, and images are also visual cues about how the word, concept, or idea makes us feel because we believe “knowledge” doesn’t exclude feeling. 

Iyo: To represent the themes, I collaborated with Nushin and Buse who gave me names of moods, and feelings, to get an idea of the theme. The idea behind this was not to represent them in a frontal way, but that forms a basis for a more general interpretation.

We can go over each of these theme designs one by one. I can tell you about the words of the moods and feelings and talk a bit about the choice of images.

Patterns

Iyo: The first idea of this repeating pattern is that of the enclosure, which to some extent can lock in repeating, normalized patterns. Then what I appreciated while trying it is the great transparency of this theme.

Once inside, it is one of the places where you can see the landscape the most, and where this landscape communicates with the grid. In this representation, there was the idea of being able to go further, to have a view of one’s environment while making explicit the trap that this can create.

Machine Vision & Feeling

Iyo: For this texture, I was instructed to have something related to the eye.

I was inspired by the representation of thermal cameras to represent the machine vision.

These thermal cameras are also used in research laboratories to recognize emotions. Although this use is questionable, I found that the graphic universe that emerged could correspond to Machine vision and feeling.

Intelligence

Iyo: I believe that this visual is not definitive. Intelligence is complex, dynamic and contextual. That’s why we opted for vagueness in this visual.

AI Violence

Iyo: For this theme, I was given the word pink. I thought of technology that is sold as inherently progressive and innocent – en rose – and the violence it creates being hidden inside this rose-tinted vision.

Refusal

Iyo: For this theme, I took the cross to symbolize refusal. Repetition of the motif, affirmation of this refusal, inevitable refusal. Technological refusal is generally a taboo, again because it is widely considered inherently progressive. The cross is strong and straightforward and also provoking. I wanted to amplify our right to refuse. 

AI & Relationality

Buse: Rhizome, mycelium networks, connectedness.

Planet Earth & Outrastructure

Iyo: The texture of this theme is related to the earth, the inspirations were around something earthy and mossy.

Future-Present Vibrations

Iyo: For this, the words were: “colourful, fun”. The chosen visual is optimistic and vibrant.

Alexa: For me, there is always a tension between representing AI or technology as it is like now versus visions of the future and the technology we want to have. With the BIOAI image database, we have some red flags. That would be e.g. really futuristic depictions in this very common sci-fi aesthetic. But I feel that there is also a big need for better visions, better futures of technology and of AI especially. I feel that your project is also about preferable futures and the images and the aesthetics are trying to provide an alternative. Was there some tension as well in representation or being afraid of becoming too futuristic or was that something that you wanted?

Nushin: I think we’re all brought up with these images of what technology could be. Either: “Robots are gonna rule us”, this very dystopic Black mirror vision. Or: AI is gonna solve humanity’s problems, like it is now depicted as a major option to “solve” the climate crisis. It’s already such a big step to get away from this imagery and see them as just possible depictions but not the ones that definitely have to come. And it’s so much harder to show plural and positive visions that could be there. It seems the dystopian vision is so much easier to depict and imagine, since we see it in the media so much. I think that’s actually pretty crazy that it’s so much easier to imagine all these things that could go wrong than actually collectively working on what we could imagine.

Buse: the intention is not only to create this repertoire of positive visions but basically try to open a space and a place where people can feel good in their bodies to be able to imagine something else. I think that’s hard when you’re just in front of your laptop and you’re stuck in a kind of trauma response which is either freeze, fight or flight. Because we are disconnected from our bodies, feelings and sensations in an auto-pilot mode and our neurocognitive, neurobiological “weaknesses” are exploited via dark patterns, all the scrolling, notifications, design that pushes you to feel urgency, urge to buy…. You’re overstimulated then, you can’t be like “Oh, let me imagine something positive about the future” – I don’t think that it’s possible on autopilot mode. This is usually how we serve “information” (again in a very limited conception of information). Even though you don’t look at anything or read anything just looking at the “Dreaming Beyond AI” Website on a big screen if you have one, listening to the sound and making the meditations at the beginning; first of all it calms you down and brings you back to your body. And ideally, hopefully, this would just make you feel something, maybe relaxed enough to be able to envision something else, relaxed enough to ask yourself some questions. Maybe it would make something resonate with you so that you can join us in imagining or just feel inspired.

Alexa: An open question. What do you wish for the media representation of AI, do you have short-cut solutions that people could implement to make it better?

Iyo: What is really interesting for me is the process to make it, more than the results. When we think about Artificial Intelligence and Machine Learning there’s a lot about the result and efficiency. What’s interesting to me is adding a reflection on the data extraction process. Who extracts them? Where is it extracted from? Who owns the data? What type of data is extracted in what context? For what purpose?  What I find important is really the whole process of digitization and extraction of our data. To analyze it and observe the existence of domination relationships in this process in order to find alternatives to do otherwise. Even before questioning their efficiency.

Alexa: Showing more of the process behind it and how it’s made?

Iyo: Yes, but also allow its democratization. To allow people to create, understand, select and own their data because behind these issues there are questions of power. So what I would like to see in relation to the media representation of AI is really that this representation can be created by a large number of people, especially by people marginalized by the existing representations.

Alexa: Buse, Nushin and Iyo – Thank you so much for the interview!


Nushin Yazdani (Concept, Curation)
Nushin Isabelle Yazdani is a transformation designer, artist, and AI design researcher. She works with machine learning, design justice, and intersectional feminist practices, and writes about the systems of oppression of the present and the possibilities for just and free futures. At Superrr Lab, Nushin works as a project manager on creating feminist tech policies. With her collective dgtl fmnsm, she curates and organizes community events at the intersection of technology, art, and design. Nushin has lectured at various universities, is a Landecker Democracy Fellow and a member of the Design Justice Network. She has been selected as one of 100 Brilliant Women in AI Ethics 2021.

Raziye Buse Çetin (Concept, Curation)
R. Buse Çetin is an AI researcher, consultant, and creative. Her work revolves around the ethics, impact, and governance of AI systems. Buse’s work aims to demystify the intersectional impact of AI technologies through research, policy advocacy, and art. Watch: Buse’s TEDx talk “Why is AI a Social Justice Issue?”.

Iyo Bisseck (Webdesign & Development)
Iyo Bisseck is a Paris-based designer, researcher, artist and coder extraordinaire. She holds a BA in media interaction design from ECAL in Lausanne and an MA in virtual and augmented reality research from Institut Polytechnique Paris. Interested in the biases showing the link between technologies and systems of domination, she explores the limits of virtual worlds to create alternative narratives.

Sarah Diedro Jordão (communications strategy)
Sarah Diedro Jordão is a communications strategist, a social justice activist, and a podcast producer. She was formerly a UN Women and Youth Ambassador, has served as a strategic advisor to the North-South Center of the Council of Europe on intersectionality in policymaking. Sarah currently works as a freelance consultant in storytelling, communications strategy, event moderation, and educational workshop creation.

AIHub: An Intro to Better Images of AI

AI generated image of a coffee cup, with 'AI' written on the top

The AIHub coffee corner captures the musings of AI experts over a short conversation. As a Founding Supporter of Better Images of AI, and having previously advised on using relevant images to promote AI research (in our guide to avoid hype), it made sense to use the opportunity to discuss better images of AI!

The representation of AI in the media has long been a problem, with blue brains, white robots, and flying maths – usually completely unrelated to the content of the article – featuring heavily. We were therefore please to support Better Image of AI’s gallery of free-to-use images which they hope will increase public understanding around the different aspects of AI, and enable more meaningful conversations.

In this piece from our coffee corner, Sabine Hauert chaired a discussion with Michael Littman, Carles Sierra, Anna Tahovska and Oskar von Stryk, surrounding how exactly we might together bring better images to a wider audience.

THE DISCUSSION:

Sabine: There are lots of aspects we can consider when thinking about AI images: 
1. How can we source or design better images for AI? 
2. How should AI be represented pictorially in articles, blogs etc? 
3. What’s the problem with images in AI? 
4. What do we need to consider when thinking about portraying AI in images?

Oskar: Another question to consider is: 
5. What is the purpose of the image, and what is the context in which the image appears? 

I think this makes a big difference actually. Some things need to be contextualised, we need to consider the purpose of the article, and so on. In my experience with the media, 50% of the time they report technically incorrectly, or at least partially incorrectly. This seems to be a kind of “law of nature”, an invariant. As a result, the only difference that you care about is whether an article portrays a positive or a negative attitude towards the AI topics mentioned. I always say, “OK, I don’t care too much about the incorrectness from a scientific point of view, as it seems quite unavoidable; if it’s a positive mood I can go with it”. So I think we need contextualisation, to determine whether the picture is useful.

Carles: In terms of designing images, I was thinking about a similar concept to a hackathon but for a design school. Teams of designers, or individual designers, could propose images which represented different views or concepts within AI. It could be connected to an award. I would approach young people in design schools with concrete proposals, and have those as the object of the hackathon.

Do you have an idea of the concepts we are missing?

Carles: I mean, we need to think about what kind of AI we are representing. Maybe solving a particular problem, or explaining a problem and some of the techniques that are being used for that. And then, after we give the designers a short explanation of that concept, we ask them to bring back some designs.

Sabine: With robotics it’s slightly easier because you can show a robot, or you can show a robot doing something. The AI one is a challenge because a lot of it is abstract. It could be that a lot of these images are slightly abstract. Would the media pick those up as something they use for their articles? Or, do we need more people in our AI images?

I was recently trying to find pictures for a report that we’re working on and I was desperately looking for pictures of people using robots for applications, and it’s really hard to get images that include the people plus the technology. You either have an abstract technology, or you have the application. You never really have that interface. So, maybe we need to stage this – photographers that spend a week taking photos of people working with the technology.

Oskar: What I actually like are comics – short cartoons which have two or three elements and a small conversation which points out something very clearly or even drastically. I have collected a number of these. They can portray a point very well. Again, what’s the purpose? If it’s a journalist writing an article about an aspect of AI then of course they look for a picture that’s attractive to a general audience, just to get them attracted to the article, no matter if the relation to the article is relevant or not. From a more scientific point of view, for scientifically oriented contexts, I like these cartoons which really highlight key issues.

Sabine: Schematics to explain the concepts then. Maybe we need some better schematics just to explain the basic concepts of AI.

What are the challenges you face as a researcher? If a journalist needs a pretty picture of your own research to put at the top, what do you usually send them?

Oskar: Sometimes I have photographers come to my lab and we take nice pictures of the robots and people. The problem with robots is that people look at the hardware and don’t see the software which makes the intelligence. So, I always try to make the software more visible – usually this typically involves using big screens where we visualise the inside of the robot’s “brain”, for example. We show the localisation and how the environment is perceived, and so on.

Michael: I was going to say graphs because that’s how I want to communicate. But, that’s not great…

Sabine: Maybe it’s not impossible to show a graph. We just need someone who’s an expert in data visualisation who could make them look really pretty. In the way that it looks almost like a picture. Maybe there’s ways we can beautify figures so that they are acceptable as an image in the media.

Anna: In our institute we are lucky because we have a graphical designer employed here. So, we can put them in touch with the researchers and they can discuss the topic and she can create graphics or photographs. It’s great for us because we run a lot of projects and these have a lot of graphical elements. Also, there are a lot of articles we need images for, so it’s very beneficial to have something like this in-house.

Sabine: The New York Times does this with their articles. They have an artist who makes really abstract pictures for these articles, that can represent just a little bit of it, but it does the job. More artist engagement is a good idea.

Oskar: Actually, graphs can be interesting as well. For example, see the work of David Kriesel, who was a former member of a RoboCup team in the Humanoid league. He was the one who detected this famous xerox scanner error, and he’s also invited as a speaker at Chaos Computer Club. He does data analysis of lots of things, for example he’s looked at Coronavirus data, and he did an analysis of the German train company, the Deutsche Bahn. He has postings on LinkedIn which are very highly rated. His talks on YouTube on data analysis get many views, so I think if you combine data with interesting insights and conclusions, you can make it attractive to a large audience.

Anything we should ban? Brains, the Terminator…

Oskar: When I talk to a general audience about robots, it’s a good sign if they think about industrial robots, but usually they think about the Terminator. And if it’s not terminating their life, it’s terminating their workplace, they may fear.

Sabine: I have noticed robotics being used a lot as a portrayal for AI even if the topic has nothing to do with robotics. I always find that interesting because there is a bit of a separation between robotics and AI depending on what field of AI you’re looking at. And yet, the robots get used a lot as images. I guess because it’s a bit more visual.

Any final thoughts on how we could source good images?

Carles: I agree with Anna. I think we should approach graphic designers and schools and give them a purpose – it could be a final year assignment to get a variety of images.

Oskar: Maybe we could get a list of key statements where there are typically misunderstandings around AI and robotics. We could explain the background to the designers, and they could come up with a graphical visualisation.

You can see more of AIHub’s work on their website, and more from the Better Images of AI gallery here.

Buzzword Buzzkill: Excitement & Overstatement in Tech Communications

An illustration of three „pixelated“ cupboards next to each other with open drawers, the right one is black

The use of AI images is not just an issue for editorial purposes. Marketing, advertising and other forms of communication may also want or need to illustrate work with images to attract readers or to present particular points. Martin Bryant is the founder of tech communications agency Big Revolution and has spent time in his career as an editor and tech writer. 

“AI falls into that same category as things like cyber security where there are no really good images because a lot of it happens in code,” he says. “We see it in outcomes but we don’t see the actual process so illustration falls back on lazy stereotypes. It’s a similar case with cyber security, you’ll see the criminal with the swag bag and face mask stooped over a keyboard and with AI there’s the red-eyed Terminator robot or it’s really cheesy robots that look like sixties sci-fi.”

The influence of sci-fi images in AI is strong and one that can make reporters and editors uncomfortable with their visal options. “ “Whenever I have tried to illustrate AI I’ve always felt like I am short changing people because it ends up being stock images or unnecessarily dystopian and that does a disservice to AI. It doesn’t represent AI as it is now. If you’re talking about the future of AI, it might be dystopian, but it might not be and that’s entirely in our hands as a species how we want AI to influence our lives,” Martin says. “If you are writing about killer robots then maybe a Terminator might be OK to use but if you’re talking about the latest innovation from DeepMind then it’s just going to distort the public understand of AI either to inflate their expectations of what is possible today or it makes them fearful for the future.” 

I should be open here about how I know Martin. We worked together for the online tech publication The Next Web where he was my managing editor and I was UK editor some years ago. We are both very familiar with the pressures of getting fast-moving tech news out online, to be competitive with other outlets and of course to break news stories. The speed at which we work in news has an impact on the choices we can make.

“If it’s news you need to get out quickly, then you just need to get it out fast and you are bound to go for something you have used in the past so it’s ready in the CMS (Content management system – the ‘back end’ of a website where text and images are added.),” Martin says. “You might find some robots or in a stock image library there will be cliches and you just have to go with something that makes some sense to readers. It’s not ideal but you hope that people will read the story and not be too influenced by the image – but a piece always needs an image.”

That’s an interesting point that Martin is making. In order to reach a readership, lots of publications rely on social media to distribute news. It was crowded when we worked together and it sometimes feels even more packed today. Think about the news outlets you follow on Twitter or Facebook, then add to this your friends, contacts and interesting people you like to follow and the amount of output they create with links to news they are reading and want to comment upon. It means we are bombarded with all sorts of images whenever we start scrolling and to stand out in this crowd, you’re going to need something really eye-catching to make someone slow down and read. 

“If it’s a more considered feature piece then there’s maybe more scope for a variety of images, like pictures of the people involved, CEOs, researchers and business leaders,” Martin says. “You might be able to get images commissioned or you can think about the content of the piece to get product pictures, this works for topics like driverless cars. But there is still time pressure and even with a feature, unless you are a well-resourced newsroom with a decent budget, you are likely to be cutting corners on images.” 

Marketing exciting AI

It’s not just the news that is hungry for images of AI. Marketing, advertising and other communications are also battling for our attention and finding the right image to pull in readers, clicks or getting people to use a product is important. Important, but is it always accurate? Martin works with and has covered news of countless startup companies, some of which use AI as a core component of their business proposition. 

“They need to think about potential outcomes when they are communicating,” he says “Say there is a breakthrough in deep neural AI or something it’s going to be interesting to academics and engineers, the average person is not going to get that because a lot of it requires an understanding of how this technology works and so you often need to push startups to think about what it could do, what they are happy with saying is a positive outcome.” 

This matches the thinking of many discussions I have had about art and the representation of AI. In order to engage with people, it can be easier to show them different topics of use and influence from agriculture to medical care or dating. These topics are far more familiar to a wider audience than a schematic for an adversarial network. But claiming an outcome can also be a thorny issue for some company leaders.

“A lot of startup founders from an academic background in AI tend to be cautious about being too prescriptive about how their technology could be used because often if they have not fully productised their work in an offering to a specific market,” Martin explains. “They need to really think about optimistic outcomes about how their tech can make the world better but not oversell it. We’re not saying it’s going to bring about world peace, but if they really think of examples of how the AI can help people in their everyday lives this will help people engage with making the leap from a tech breakthrough they don’t understand to really getting why it’s useful.” 

Overstating AI

AI now appears to be everywhere. It’s a term that has broken out from academia, through engineering and into business, advertising and mainstream media. This is great, it can mean more funding, more research, progress and ethical monitoring and attention. But when tech gets buzzy, there’s a risk that it will be overstated and misconstrued. 

“There’s definitely a sense of wanting to play up AI,” Martin says. “There’s a sense that companies have to say ‘look at our AI!’ when actually that might be overselling what is basic technology behind the scenes. Even if it’s more developed than that, they have to be careful. I think focusing on outcomes rather than technologies is always the best approach. So instead of saying ‘our amazing, groundbreaking AI technology does this’ – focusing on what outcomes you can deliver that no one else can because of that technology is far more important. 

As we have both worked in tech for so long, the buzzword buzzkill is a familiar situation and one that can end up with less excitement and more of an eyeroll. Martin shared some past examples we could learn from, “It’s so hilarious now,” he says. “A few years ago everything had to have a location element, it was the hot new thing and now the idea of an app knowing your location and doing something relevant to it is nothing. But for a while it was the hottest thing. 

“Gamification was a buzzword too. Now gamification is a feature in lots and lots of apps, Duolingo is a great example but it’s subtly used in other areas  but for a while startups would pitch themselves saying ‘we are the gamified version of X’.”

But the overuse of language and their accompanying images is far from over and it’s not just AI that suffers. “Blockchain keeps rearing its head,” Martin points out. “It’s Web3 now, slightly further along the line but the problem with Web3 and AI is that there’s a lot of serious and thoughtful work happening but people go ahead with ‘the blockchain version of X or web3 version of Y’ and because it’s not ready yet or it’s far too complicated for the mainstream, it ends up disillusioning people. I think you see this a bit with AI too but Web3 is the prime example at the moment and it’s been there in various forms for a long time now.” 

To avoid bad visuals and buzzword bingo in the reporting of AI, it’s clear through Martin’s experience that outcomes are a key way of connecting with readers. AI can be a tricky one to wrap your head around if you’re not working in tech, but it’s not that hard when it’s clearly explained.”It really helps people understand what AI is doing for them today rather than thinking of it as something mysterious or a black box of tricks,” Martin says. “That box of tricks can make you sound more competitive but you can’t lie to people about it and you need to focus on outcomes that help people understand clearly what you can do. You’ll not only help people’s understanding of your product but also the general public’s knowledge of   what AI can really do for them.”

Humans (back) in the Loop

Pictures of Artificial Intelligence often remove the human side of the technology completely, removing all traces of human agency. Better Images of AI seeks to rectify this. Yet, picturing the AI workforce is complex and nuanced. Our new images from Humans in the Loop attempt to present more of the positive side, as well as bringing the human back into the centre of AI’s global image. 

The ethicality of AI supply chains is not something newly brought under fire. Yet, separate from the material implications of its production, the ‘new digital assembly line’, which Mary L. Gray and Siddarth Suri explore in their book Ghost Work, holds a much more immediate (and largely unrecognised) human impact. In particular, the all-too-frequent exploitation characterising so-called ‘Clickwork’. Better Images of AI has recently coordinated with award-winning social enterprise Humans in the Loop to attempt to rectify this endemic removal of the human from discussions; with a focus on images concerning the AI supply chain, and the field of artificial intelligence more broadly.

‘Clickwork’, more appropriately referred to as ‘data work’ is an umbrella term, signifying a whole host of human involvements in AI production. One of the areas in which human input is most needed is that of data annotation, an activity that provides training data for Artificial Intelligence. What used to be considered “menial” and “low-skilled” work is today a nascent field with its own complexities and skills requirements,  involving extensive training. However, tasks such as this, often ‘left without definition and veiled from consumers who benefit from it’ (Gray & Suri, 2019), result in these individuals finding themselves relegated to the realm of “ghost work”.

While the nature of ‘ghost work’ is not inherently positive or negative, the resultant lack of protection which these data workers are subject to can produce some highly negative outcomes. Recently Time Magazine uncovered some practices which were not only being hidden, but deliberately misrepresented. The article collates testimonies from Sama employees, contracted as outsourced Facebook content moderators. These testimonials reveal a workplace characterised by ‘mental trauma, intimidation, and alleged suppression’. The article ultimately concludes that through the hidden quality of this sector of the supply chain, Facebook profits through exploitation, and through the exportation of trauma away from the West and instead toward the developing world.

So how can we help to mitigate these associated risks of ‘ghost work’ within the AI supply chain? It starts with making the invisible, visible. As Noopur Raval (2021) puts it, to collectively ‘identify and interrupt the invisibility of work’ constitutes an initial step towards undermining the ‘deliberate construction and maintenance of “screens of invisibility”‘. To counter the prevalent images of AI, circulated as an extension of ‘AI imperialism’ within the West- an idea further engaged with by Karen Hao (2022)– which remove any semblance of human agency or production, and conceal the potential for human exploitation, we were keen to show the people involved in creating the technology.

These people are very varied and not just the homogenous Silicon Valley types portrayed in popular media. They include silicon miners, programmers, data scientists, product managers, data workers, content moderators, managers and many others from all around the globe; these are the people who are the intelligence behind AI. Our new images from Humans in the Loop attempt to challenge wholly negative depictions of data work, whilst simultaneously bringing attention to the exploitative practices and employment standards within the fields of data labelling and annotation. There is still, of course, work to do, as the Founder, Iva Gumnishika detailed in the course of our discussion with her. The glossy, more optimistic look at data work which these images present must not be taken as licence to excuse the ongoing poor working conditions, lack of job stability, or exposure to damaging or traumatic content which many of these individuals are still facing.

As well meeting our aim of portraying the daily work at Humans in the Loop and to showcase the ‘different faces behind [their] projects’, our discussions with the Founder gave us the opportunity to explore and communicate some of the potential positive outcomes of roles within the supply chain. These include the greater flexibility which employment such as data annotation might allow for, in contrast to the more precarious side of gig-style working economies.

In order to harness the positive potential of new employment opportunities, especially those for displaced workers, Human in the Loop’s navigates major geopolitical factors impacting their employees (for example the Taliban government in Afghanistan, the embargoes on Syria, and more recently the war in Ukraine). Gumnishika also described issues connected with this brand of data work such as convincing ‘clients to pay dignified wages for something that they perceive as “low-value work”’ and attempting to avoid the ‘race to the bottom’ within this arena. Another challenge is in allowing the workers themselves to acknowledge their central role in the industry, and what impact their work is having. When asked what she would identify as the central issue within present AI supply chain structures, her emphatic response was that ‘AI is not as artificial as you would think!’. The cloaking of the hundreds of thousands of people working to verify and annotate the data, all in the name of selling products as “fully autonomous”, and possessing “superhuman intelligence”, only acts to the detriment of its very human components. By including more of the human faces behind AI, as a completely normal/necessary part of it, Gumnishka hopes to trigger the unveiling of AI’s hidden labour inputs. In turn, by sparking widespread recognition of the complexity, value, and humanity behind work such as data annotation and content moderation–as in the case of Sama– the ultimate goal is an overhaul of data workers’ employment conditions, wages and acknowledgement as a central part of AI futures. 

In our gallery we attempt to represent both sides of data work, and Max Gruber, another contributor to the Better Images of AI gallery, engages with the darker side of gig-work in greater depth through his work, included in our main gallery and below. It presents ‘clickworkers’ as they predominantly are currently – precariously paid workers in a digital gig economy, performing monotonous work for little to no compensation. His series of photographs depict 3D printed figures, stationed in front of their computers to the uncomfortable effect of quite literally illustrating the term “human resources”, as well as the rampant anonymity which perpetuates exploitation in the area. The figure below ‘Clickworker 3d-printed’ is captioned as ‘anonymized, almost dehumanised’, the obscuration of the face and identical ‘worker’ represented in the background of the image, all cementing the individual’s status as unacknowledged labour in the AI supply chain. 

Max Gruber / Better Images of AI / Clickworker 3d-printed / CC-BY 4.0

We can contrast this with the stories behind Human in the Loop’s employees.

Nacho Kamenov & Humans in the Loop / Better Images of AI / Data annotators labeling data / CC-BY 4.0

This image, titled ‘Data annotators labelling data’ immediately offers up two very real data workers, faces clear and contribution to the production of AI clearly outlined. The accompanying caption details the function of data annotation, when it is needed, what purpose it serves; there is no masking, no hidden element to their work, as previously.

Gumnishka shares that some of the people who appear on the images have continued their path as migrants and refugees to other European countries, for example the young woman in the blog cover photo. Others have other jobs (one of the pictures shows an architect although now having found work in her field, continues to come to training and is part of the community. For others like the woman in the colourful scarf, it becomes their main source of livelihood and they are happy to pursue it as a career.

Through adding the human faces back into the discussions surrounding artificial intelligence we see not just the Silicon Valley or business-suited tech workers we occasionally see in pictures, but the vast armies of workers across the world, many of them women, many of them outside of the West.

The image below is titled ‘A trainer instructing a data annotator on how to label images’. This helps address the lack of clarity on what exactly datawork entails, and the level of training, expertise and skill required to carry it out. This image engages directly with this idea, showing some of the extensive training required in visible action, in this case by the Founder herself.

a young woman sitting in front of a computer in an office while another woman standing next to her is pointing at something on her screen
Nacho Kamenov & Humans in the Loop / Better Images of AI / A trainer instructing a data annotator on how to label images / CC-BY 4.0 (Also used as cover image)

Although these images do not of course accurately represent the experience of all data workers, in combination with the increasing awareness of conditions enabled by contributions such as the recent Times article, or the work by Gray and Suri, by Kate Crawford in her book Atlas of AI, and with the counterbalance provided by Max Gruber’s images, the addition of the photographs from Humans in the Loop provides inspiration for others. 

We hope to keep adding images of the real people behind AI, especially those most invisible at present. If you work in AI, could you send us your pictures, and how could you show the real people behind AI? Who is still going unnoticed or unheard? Get involved with the project here: https://betterimagesofai.org/contact.

Avoiding toy robots: Redrawing visual shorthand for technical audiences

Two pencil drawn 1960s style towy robots being scribbled out by a pencil on a pale blue background

Visually describing AI technologies is not just about reaching out to the general public, it also means getting things marketing and technical communication right. Brian Runciman is the Head of Content – British Computer Society (BCS) The Chartered Institute of IT. His audience is not unfamiliar with complex ideas, so what are the expectations for accompanying images? 

Brian’s work covers the membership magazine for BCS as well as a publicly available website full of news, reports and insights from members. The BCS membership is highly skilled, technically minded and well read – so the content on site and in the magazine needs to be appealing and engaging.  

“We view our audience as the educated layperson,” Brian says. “There’s a base level of knowledge you can assume. You probably don’t have to explain what machine learning or adversarial networks are conceptually and we don’t go into tremendous depth because we have academic journals that do this.” 

Of course writing for a technical audience also means Brian and his colleagues will get smart feedback when something doesn’t quite fit expectations. “With a membership of over 60 thousand, there are some that are very engaged with how published material is presented and quite rightly,” Brian says. “Bad imagery affects the perception of what something really is.”

So what are the rules that Brian and his writers follow? As with many publications there is a house style that they try to keep to and this includes the use of photography and natural imagery. This is common among news publications that choose this over illustration, graphics or highly manipulated images. In some cases this is used to encourage a sense of trust in the readership that images are accurate and have not been changed. This also tends to mean the use of stock images. 

“Stock libraries need to do better,” Brian observes. “When you’re working quickly and stuff needs to be published, there’s not a lot of time to make image choices and searching stock libraries for natural imagery can mean you end up with a toy robot to represent things that are more abstract.”

“Terminators still come up as a visual shorthand,” he says. “But AI and automation designers are often just working to make someone’s use of a website a little bit slicker or easier. If you use a phone or a website to interact with an automated process it does what it is supposed to do and you don’t really notice it – it’s invisible and you don’t want to see it. The other issue is that when you present AI as a robot people think it is embodied. Obviously, there is a crossover but in process automation, there is no crossover, it’s just code, like so much else is.”

Tone things down and make them relatable 

Brian’s decades-long career in publishing means he has some go-to methods for working out the best way to represent an article. “I try to find some other aspect of the piece to focus on,” he says. “So in a piece about weather modelling, we could try and show a modelling algorithm but the other word in the headline is weather and an image of this is something we can all relate to.” 

Brian’s work also means that he has observed trends in the use of images. “A decade or so ago it was more important to show tech,” he says. “In a time when that was easily represented by gadgets and products this was easier than trying to describe technologies like AI. Today we publish in times when people are at the heart of tech stories and those people need to look happy.”

Pictures of people are a good way to show the impact of AI and its target users, but it also raises other questions about diversity – especially if the images are predominantly of middle aged white men. “It’s not necessary,” says Runciman. “We have a lot of head shots of our members that are very diverse. We have people from minorities, researchers who are not white or middle aged – of which there are loads. When people say they can’t find diverse people for a panel I find it ridiculous, there are so many people out there to work with. So we tend to focus on the person who is working on a technology and not just the AI itself.”

The use of images is something that Brian sees every day for work, so what would be on his wish list when it comes to better images of AI? “No cartoon characters and minimal colour usage – something subtle,” he muses. “Skeletal representations of things – line representations of networks, rendered in subtle and fewer colours.” This nods at the cliches of blue and strange bright lights that you can find in a simple search for AI images, but as Brian points out, there are subtler ways of depicting a network and images for publishing that can still be attractive without being an eyesore.

Why Metaphors matter: How we’re misinforming our children about data

An abstract illustration with fluid words spelling Data, Oil, Fluid and Leak

Have you ever noticed how often we use metaphors in our day-to-day language? The words we use matter, and metaphorical language paints mental pictures imbued with hidden and often misplaced assumptions and connotations. In looking at the impact of metaphorical images to represent the technologies and concepts covered within the term artificial intelligence, it can be illuminating to drill down into one element of AI – that of data.

Hattusia recently teamed up with Jen Persson at Defend Digital Me and The Warren Youth Project to consider how the metaphors we attach to data impacts UK policy, amalgamating in a data metaphors report.

In this report, we explore why and how public conversations about personal data don’t work. We suggest what must change to better include children for the sustainable future of the UK national data strategy.

Our starting point is the influence of common metaphorical language: how does the way we talk about data affect our understanding of it? In turn, how does this inform policy choices, and how children feel about the use of data about them in practice?

Still from a video showing Alice Thwaite being interviewed
Watch the full video and interview here

Metaphors are routinely used by the media and politicians to describe something as something else. This brings with it associations made in response in the reader or recipient. We don’t only see the image but receive the author’s opinion or intended meaning on something.

Metaphors are very often used to influence the audience’s opinion. This is hugely important because policymakers often use metaphors to frame and understand problems – the way you understand a problem has a big impact on how you respond to it and construct a solution.

Looking at children’s policy papers and discussions about data in Parliament since 2010, we worked with Julia Slupska to identify three metaphor groups most commonly used to describe data and its properties.

We found that ​​a lot of academic and journalistic debates frame data as ‘the new oil’, for example; while some others describe it as toxic residue or nuclear waste. The range of metaphors used by politicians is more narrow and rarely as critical.

Through our research, we’ve identified the three most prominent sets of metaphors for data used in reports and policy documents. These are:

  • Fluid: data can flow or leak
  • A resource/fuel: data can be mined, can be raw, data is like oil
  • Body or bodily residue: data can be left behind by a person like footprints; data needs protecting

In our workshop at The Warren Youth Project , the participants used all of our identified metaphors in different ways. Some talked about the extraction of data being destructive, while others compared it to a concept that follows you around from the moment you’re born. Three key themes emerged from our discussions:

  • Misrepresentation: the participants felt that data was often inaccurate, or used by third parties as a single source of truth in decision-making. In these cases, there was a sense that they had no control over how they were perceived by law enforcement and other authority figures.
  • Power hierarchies and abuses of power: this theme came out via numerous stories about those with authority over the participants having seemingly unfettered access to their data, thus enforcing opaque processes, leaving the participants powerless and with no control.
  • The use of data ‘in your best interest’: there was unease expressed over data being used or collected for reasons that were unclear and defined by adults, leaving children with a lack of agency and autonomy.

When looking into how children are framed in data policy, we found they are most commonly represented as criminals or victims, or simply missing in the discussion. The National Data Strategy makes a lot of claims of how data can be of use to society in the UK, but only mentions children twice and mostly talks about data like it is a resource to be exploited for economic gain.

The language in this strategy and other policy documents is alienating and dehumanises children into data points for the purpose of predicting criminal behaviour or to attempt to protect them from online harm. The voices of children themselves are left out of the conversation entirely. We propose new and better ways to talk about personal data.

To learn more about our research, watch this video (produced by Matt Hewett) in which I discuss the findings. It breaks down exactly what the three groups were, how the experiences which young people and children had related to data linked back to those three groups, and how changing the metaphors we use when we talk about data could be key to inspiring better outcomes for the whole of society.

We also recommend looking at the full report on the Defend Digital Me website here

From Black Box to Algorithmic Veil: Why the image of the black box is harmful to the regulation of AI

An abstract image containing stylized black cubes and a half-transparent veil infront of a night street scene

The following is based on an excerpt of the upcoming book “Self-imposed Algorithmic Thoughtlessness and the Automation of Crime Control”, Nomos/Hart 2022 by Lucia Sommerer


Language is never innocent: words possess a secondary memory, which in the midst of new meanings mysteriously persists.

Roland Barthes1

The societal, as well as the scholarly discussion about new technologies, is often characterized by the use of metaphors and analogies. When it comes to the legal classification of new technologies, Crootof even speaks of a ‘battle of analogies’2. Metaphors and analogies offer islands of familiarity when legally navigating through the floods of complex technological evolution. Metaphors often begin where the intuitive understanding of new technologies ends.3 The less familiar we feel with a technology, the greater our need for visual language as a set of epistemic crutches. The words that we choose to describe our world, however, have a direct influence on how we perceive the world.4 Wittgenstein even argues that they represent the boundaries of our world.5 Metaphors and analogies are never neutral or ‘innocent’, as Barthes puts it, but come with ‘baggage’6, i.e. metaphors in the digital realm are loaded with the assumptions of the analogue world from which the imagery is borrowed.7 Consider the following question about one of the most widespread metaphors on the subject of algorithms, the black box:

What do you see before your inner eye, when you hear the term ‘black box’?

Some people may think of a monolithic, robust, opaque, dark and square figure.

What few people will see is humans.

This demonstrates both the strengths and the weaknesses of the black box image and thus its Janus-headedness. In the discussion about algorithms, the black box narrative was originally intended as a ‘wake-up call’8 to direct our attention – through memorable visual language – towards certain risks of algorithmic automation; namely towards the risks of a loss of (human) control and understandability. The black box terminology successfully fulfils this task.

But it also threatens to obscure our view of the people behind algorithmic systems and their value judgements. The black box image conceals an opportunity to control the human decisions behind an algorithmic system and falsely suggests that algorithms are independent of human prejudices. By drawing attention to one problem area of the use of algorithms (non-transparency), the black box narrative threatens to distract from others (controllability, hidden human value judgements, lack of neutrality). The term black box hides the fact that algorithms are complex socio-technical systems9 that are based on a multitude of different human decisions10. Further, by presenting algorithmic technology as a monolithic, unchangeable and incomprehensible black box, connotations such as ‘magical’ and ‘oracular’ often arise.11 Instead of provoking criticism, such terms often lead to awe and ultimately surrender to the opacity of the black box. Our options for dealing with algorithms are reduced to ‘use vs. do not use’. Opportunities that would allow for nuances in the human design process of the black box go unnoticed. The inner processes of the black box as a system are sealed off from humans and attributed an inevitability that strongly resembles the inevitability of the forces of nature; forces that can be ‘tamed’ but never systematically controlled.12 The black box narrative also ascribes such problematic inevitability to negative side effects such as the discriminatory effects of an algorithm. This view diverts attention away from the very human-made sources of algorithmic discriminatory behaviour (e.g. selection of training data). The black box narrative in its most widespread form – namely as an unreflected catchphrase – paradoxically achieves the opposite of what it is intended to do; namely, to protect us from a loss of control over algorithms.

In reality it is, however, possible to disclose a number of human value judgements that stand behind even supposed black box algorithm, for example, through logging requirements in the design phase or output testing.

The challenge posed by the regulation of algorithms, therefore, is more appropriately described as an ‘algorithmic veil’ than a black box; an ‘algorithmic veil’ that is placed over human decisions and values. One advantage of the metaphor of the veil is that it almost inherently invites us to lift it. A black box, on the other hand, does not contain such a prompt. Quite the opposite: a black box indicates that an attempt to gain any insight whatsoever is unlikely to succeed. The metaphors we use in the discussion about algorithms, therefore, can directly influence what we think is possible in terms of algorithm regulation. By conjuring up the image of the flowing fabric of an algorithmic veil, which only has to be lifted, instead of a massive black box, which has to be broken open, my intention is not to minimize the challenges of algorithm regulation. Rather, the veil should be understood as an invitation to society, programmers and scholars: instead of talking about what algorithms ‘do’ (as if they were independent actors), we should talk about what the human programmers, statisticians, and data scientists behind the algorithm do. Only when this perspective is adopted can algorithms be more than just ‘tamed’, i.e., systematically controlled by regulation.


1 Roland, Writing Degree Zero, New York 1968, 16.
2 Thomson-DeVeaux FiveThirtyEight v. 29.5.2018, https://perma.cc/YG65-JAXA.
3 So-called cognitive metaphor, cf. Drewer, Die kognitive Metapher als Werkzeug des Denkens. Zur Rolle der Analogie bei der Gewinnung und Vermittlung wissenschaftlicher Erkenntnisse, Tübingen 2003.
4 Lakoff/Johnson, Metaphors We Live By, Chicago 2003; Jäkel, Wie Metaphern Wissen schaffen: die kognitive Metapherntheorie und ihre Anwendung in Modell-Analysen der Diskursbereiche Geistestätigkeit, Wirtschaft, Wissenschaft und Religion, Hamburg 2003.
5 Wittgenstein, Tractatus Logico-Philosophicus – Logisch-Philosophische Abhandlung, Berlin 1963, Satz 5.6.
6 Lakoff/Wehling, „Auf leisen Sohlen ins Gehirn.“ Politische Sprache und ihre heimliche Macht, 4. Aufl., Heidelberg 2016, 1 ff. speak of the so-called ‘Issue Defining Frame’.
7 See for example how metaphors differently relate to the data we unconsciously leave behind on the Internet: data as the ‘new oil’ (Mayer-Schönberger/Cukier, Big Data – A Revolution that will transform how we live, work and think, New York 2013, 20), ‘data waste’ (Harford, Significance 2014, 14 (15)) or ‘data extortion’ (Singer/Maheshwari The New York Times v. 25.4.2017, https://perma.cc/9VF8-J7F7). A metaphor’s starting point has great significance for the outcome of a discussion, as Behavioral Economics Research under the heading of ‘Anchoring’ has shown, see Kahneman, Thinking, Fast and Slow, London 2011, 119 ff.
8 In this sense, Pasquale, The Black Box Society – The Secret Algorithms That Control Money and Information, Cambridge et al. 2015.
9 Cf. Simon, in: Floridi (Hrsg.), The Onlife Manifesto – Being Human in a Hyperconnected Era, Heidelberg et al. 2015, 145 ff., 146; for the corresponding work of the Science & Technology Studies see Simon, Knowing Together: a Social Epistemology for Socio-Technical Epistemic Systems, Diss. Univ. Wien, 2010, 61 ff. m.w.N..
10 See Lehr/Ohm, UCDL Rev. 2017, 653 (668) (‘Out of the ether apparently springs a fully formed “algorithm”’) .
11 Elish/boyd, Communication Monographs 2017, 1 (6 ff.);Garzcarek/Steuer, Approaching Ethical Guidelines for Data Scientists, arXiv 2019, https://perma.cc/RZ5S-P24W (‘algorithms act very similar to ancient oracles’); science fiction framing and a reference to the book/film Minority Report, in which human oracles predict murders with the help of technology, are also frequently found; see Brühl/Steinke Süddeutsche Zeitung v. 4.3.2019, https://perma.cc/6J55-VGCX; Stroud Verge v. 19.2.2014, http://perma.cc/T678-AA68.
12 Similarly, as early as 20 years ago, Nissenbaum, Science and Engineering Ethics 1996, 25 (34).

Title image by Alexa Steinbrück

How do blind people imagine AI? An interview with programmer Florian Beijers

A human hand touching a glossy round surface with cloudy blue texture that resembles a globe
Florian Beijers

Note: We acknowledge that there is no one way of being blind and no one way of imagining AI as a blind person. This is an individual story. And we’re interested in hearing more of those! If you are blind yourself and want to share your way of imagining AI, please get in touch with us. This interview has been edited for clarity.

Alexa: Hi Florian! Can you introduce yourself?

Florian: My name is Florian Beijers. I am a Dutch developer and accessibility auditor. I have been fully blind since birth, I use a screen reader. And I give talks, write articles and give interviews like this one.

Alexa: Do you have an imagination of Artificial Intelligence?

Florian: I was born fully blind so I have never actually learned to see images, neither do I do this in my mind or in my dreams. I think in modalities I can somehow interact with in the physical world. This is sound, tactile images, sometimes even flavours or scents. When I think of AI, it really depends on the type of AI. If I think of Siri I just think of an iPhone. If I think of (Amazon) Alexa, I think of an Amazon Echo.

It really depends on what domain the AI is in

I am somehow proficient in knowing how AI works. I generally see scrolling code or a command line window with responses going back and forth. Not so much an actual anthropomorphic image of, say, Cortana or like these Japanese Anime. It really depends on what domain the AI is in.

Alexa: When you read news articles about AI and they have images there, do you skip these images or do you read their alt text?

Florian: Often they don’t have any alts, or a very generic alt like “image of computer screen” or something like that. Actually, it’s so not on my radar. When you first asked me that question about one week ago – “Hey we’re researching images of AI in the news” – I was like: Is that a thing?

(laughter)

Florian: I had no clue that that was even happening. I had no idea that people make up their own images for AI. I know in Anime or in Manga, there’s sometimes this evil AI that’s actually a tiny cute girl or something.

I had no idea that people make up their own images for AI

Alexa: Oh yes, AI images are a thing! Especially the images that come from these big stock photo websites make up such a big part of the internet. We as a team behind Better Images of AI say: These images matter because they shape our imagination of these technologies. Just recently there was an article about an EU commission meeting about AI ethics and they illustrated it with an image of the Terminator …

(laughter)

Alexa: … I kid you not, that happens all the time! And a lot of people don’t have the time to read the full article and what they stick with is the headline and the image, and this is what stays in their heads. And in reality, the ethical aspects mentioned in the article were about targeted advertisements or upload filters. Stuff that has no physical representation whatsoever and it’s not even about evil, conscious robots. But this has an influence on people’s perception of AI: Next time they hear somebody say “Let’s talk about the ethics of AI”, they think of the Terminator and they think “I have nothing to add to this discussion” but actually they might have because it’s affecting them as well!

Florian: That is really interesting because in 9 out of 10 times this just goes right by me.

Alexa: You are quite lucky then!

Florian: Yes, I am kind of immune to this kind of brainwashing.

Alexa: But you know what the Terminator looks like?

Florian: Yeah, I mean I’ve seen the movie. I’ve watched it once with audio description. But even if I am not told what it looks like I make it a generic robot with guns…

Alexa: Do you own a smart speaker?

Florian: Yes. I currently have a Google Home. I am looking into getting an Amazon Alexa Echo Dot as well. I enjoy hacking on them as well like creating my own skills for them.

Alexa: In the past, I did some research on how voice assistants are anthropomorphised and how they’re given names, a gender, a character and whole detailed backstories by their makers. All this storytelling. And the Google Assistant stood out because there’s less of this storytelling. They didn’t give it a human name, to begin with.

Two smart speakers: A Google home and an Amazon Echo. Image: Jonas Nordström CC BY 2.0

Florian: No it’s just “Google”. It’s like you are literally talking to a corporation.

Alexa: Which is quite transparent! I like it. Also in terms of gender, they have different voices, at least in the US, they are colour-coded instead of being named “female” or “male”.

Florian: It’s a very amorphous AI, it’s this big block of computing power that you can ask questions to. It’s analogous to what Google has always been: The search giant, you can type things into it and it spits answers back out. It’s not really a person.

Alexa: Yeah, it’s more like infrastructure.

Florian: Yeah, a supercomputer.

Alexa: I wondered if you were using a voice assistant like Amazon Alexa that is more heavily anthropomorphised and has all this character. How would you imagine this entity then?

Florian: Difficult. Because I know kind of how things work AI-wise, I played with voice assistants in the past. That makes it really hard to give it the proper Hollywood finish of having an actual physical shape.

Alexa: Maybe for you, AI technology has a more acoustic face than a visual appearance?

Florian: Yes! The shape it has is the shape it’s in. The physical device it’s coming from. Cortana is just my computer, Siri is just my phone.

The shape AI has is the shape it’s in

Alexa: Would you say that there is a specific sound to AI?

Florian: Computers have been talking to me ever since I can remember. This is essentially just another version of that. When Siri first started out it used the voice from VoiceOver (the iOS screen reader). Before Siri got its own voice it used a voice called Samantha, that’s a voice that’s been in computers since the 1990s. It’s very much normal for devices to talk at me. That’s not really a special AI thing for me.

A sound example of a screen reader

Alexa: When did you start programming?

Florian: Pretty much since I was 10 years old when I did a little HTML tutorial that I found on the web somewhere. And then off and on through my high school career until I switched to studying informatics. I’ve been a full-time developer since 2017.

Computers have been talking to me ever since I can remember

Alexa: I think how I first got in touch with you on Twitter was via a post you did about screenreaders for programmers, there was a video and I was mind-blown how fast everything is.

Florian: It’s tricky! Honestly, I haven’t mastered it to the point where other blind programmers have. I use a Braille display, which is a physical device that shows you line by line in Braille. I use that as a bit of a help. I know people, especially in the US, who don’t use Braille displays. Here in Europe it’s generally a bit better arranged in terms of getting funding for these devices, because these devices are prohibitively expensive, like 4000-6000 Euros. In the Netherlands, the state will pay for those if you’re sufficiently beggy and blindy. Over in the US, that’s not as much of a given. A lot of people tend not to deal with Braille. Braille literacy is down as a result of that over there.

I use a Braille display to get more of a physical idea of what the code looks like. That helps me a lot with bracket matching and things like that. I do have to listen out for it as well otherwise things just go very slowly. It’s a bit of a combination of both.

Alexa: So a Braille display is like an actual physical device?

Florian: It’s a bar-shaped device on which you can show a line of Braille characters at a time. Usually, it’s about 40 or 80 characters long. And you can pan and scroll through the currently visible document.

I use a Braille display to get more of a physical idea of what the code looks like

Alexa: How do you get the tactile response?

Florian: It’s like tiny little pins that go up and down. Piezo cells. The dots for the Braille characters come up and fall as new characters replace them. It’s a refreshable line of Braille cells.

A person's hands using a Braille display on a desk next to a regular computer keyboard
A person using a braille display. Image: visualpun.ch, CC BY-SA 2.0, https://www.flickr.com/photos/visualpunch/

Alexa: Would that work for images as well? Could you map the pixels to those cells on a Braille display?

Florian: You could and some people have been trying that. Obviously the big problem there is that the vast majority of blind people will not know what they’re looking at, even if it’s tactile. Because they lack a complete frame of reference. It’s like a big 404.

(laughing)

Florian: In that sense, yes you could. People have been doing that by embossing it on paper. Which essentially swells the lines and slopes out of a particular type of thick paper, which makes it tactile. This is done for example for mathematical graphs and diagrams. It wouldn’t be able to reproduce colour though.

Alexa: You are a web accessibility expert. What are some low hanging fruits that people can pick when they’re developing websites?

Florian: If you want to be accessible to everyone, you want to make sure that you can navigate and use everything from the keyboard. You want to make sure that there is a proper organizational hierarchy. Important images need to have an alt text. If there’s an error in a form a user is filling out, don’t just make it red, do something else as well, because of blind and colourblind people. Make sure your form fields are labelled. And much more!

Alexa: Florian, thank you so much for this interview!


Links

Florian on Twitter: @zersiax
Florian’s blog: https://florianbeijers.xyz/
Article: “A vision of coding without opening your eyes”
Article: “How to Get a Developer Job When You’re Blind: Advice From a Blind Developer Who Works Alongside a Sighted Team” on FreeCodeCamp.org
Youtube video “Blindly coding 01”:  https://www.youtube.com/watch?v=nQCe6iGGtd0
Audio example of a screen reader output: https://soundcloud.com/freecodecamp/zersiaxs-screen-reader

Other links

Accessibility on the web: https://developer.mozilla.org/en-US/docs/Learn/Accessibility/What_is_accessibility
Screen reader: https://en.wikipedia.org/wiki/Screen_reader
Refreshable Braille display: https://en.wikipedia.org/wiki/Refreshable_braille_display
Paper embossing: https://www.perkinselearning.org/technology/blog/creating-tactile-graphic-images-part-3-tips-embossing

Cover image:
“Touching the earth” by Jeff Kubina from Columbia, Maryland, CC BY-SA 2.0 https://creativecommons.org/licenses/by-sa/2.0, via Wikimedia Commons

AI images – an ecosystem problem with a collaborative solution

A handmade sketch of four figures throwing shadows that look like neural networks

Images of AI have been a problem rattling around my mind for many years. As a degree student studying AI, I naturally read a tonne of articles where the writing was excellent but the images did not match.

For decades as a reporter and editor covering technology stories, AI news would come and go but I was limited and frustrated by the options I had to illustrate stories. Now as an MA Illustration student I find myself returning to the problem and working on creating options so that other editors and picture desks have more to work with. It’s not a blame game, there is an ecosystem that desperately needs fresh input to break a cycle of cliches.

It’s not a blame game, there is an ecosystem that desperately needs fresh input to break a cycle of cliches.

Put in brief terms, many reporters don’t choose images to go with their stories, picture editors don’t always have anything other than stereotypes to put on their stories, photographers are often commissioned to shoot work that reinforces those stereotypes. The bottom line is that readers and content consumers get white robots, terminators and flying maths because it takes time and money, focus and expertise to change this and while good media outlets still need to attract readers by publishing quickly, they often take what they can get and move on.

Being one person working to try and change a visual language sometimes felt like an exercise in hubris. Frankly, it feels lonely! I have interviewed so many people, chatted with AI practitioners and other artists, and searched for other people working to solve the problem or change the ratio of images.

Work that affects society and is pushing for a visual cultural shift needs to be done collaboratively – which is precisely how I love to work.

Better Images of AI means I am not chasing this on my jack jones. The project brings together people of passion and expertise. We all know the problem and we can move beyond griping about it and actually work on solutions. Working with BBC R&D and Better Images of AI means working collaboratively. You can banish the idea of an artist who hides in the attic making paintings for years alone. Work that affects society and is pushing for a visual cultural shift needs to be done collaboratively – which is precisely how I love to work.

I have written more about my frustrations and my journey in a previous blog post which talks about the challenge of embodying AI. If you make work about AI or have ideas that would contribute to the stock photography and rendering work, make sure you get in touch.

I’ve been consulting with BBC R&D to work with artists as this project progresses and bring editorial and artistic views to help steer things. The first artist has been commissioned by BBC R&D, the wonderful Alan Warburton who is excellent in his execution, visionary in his ideas generation and a total pro to work with. You should follow his work.

In the coming year I hope to be able to work with more artists to explore this field and eventually, image by image, I think we can create images that will start to change how people perceive this technology and draw away from those images that for so many years have been one of my points of editorial frustration.

Press release: Better Images of AI launches a free stock image library of more realistic images of artificial intelligence


  • Non-profit collaboration starts to make and distribute more accurate and inclusive visual representations of AI
  • Follows research showing that current popular images of AI using themes like white human-like robots and glowing brains and blue backgrounds create barriers to understanding of technology, trust, and diversity
  • Available for technical, science, news and general media and marketing communications

December 14, 2021 08:00 AM Coordinated Universal Time (UTC)

LONDON, UK. Today sees the launch of Better Images of AI Image Library, which makes available the first commissioned and curated stock images of artificial intelligence (AI) in response to various research studies which have substantiated concerns about the negative impacts of the existing available imagery.

betterimagesofai.org is a collaboration between various global academics, artists, diversity advocates, and non-profit organisations. It aims to help create a more representative and realistic visual language for AI systems, themes, applications and impacts. It is now starting to provide free images, guidance and visual inspiration for those communicating on AI technologies. 

At present, the available downloadable images on photo libraries, search engines, and content platforms are dominated by a limited range of images, for example, those based on science fiction inspired shiny robots, glowing brains and blue backgrounds. These tropes are often used as inspiration even when new artwork is commissioned by media or tech companies.

The first few images to be released on the library showcase different approaches to visually communicating technologies such as computer vision and natural language processing and to communicating themes such as the role of ‘click workers’ who annotate data use in machine learning training and other human input to machine learning.

A photographic rendering of a young black man standing in front of a cloudy blue sky, seen through a refractive glass grid and overlaid with a diagram of a neural network
Image by Alan Warburton / © BBC / Better Images of AI / Quantified Human / Licenced by CC-BY 4.0
Two digitally illustrated green playing cards on a white background, with the letters A and I in capitals and lowercase calligraphy over modified photographs of human mouths in profile.
Alina Constantin / Better Images of AI / Handmade A.I / Licenced by CC-BY 4.0
A banana, a plant and a flask on a monochrome surface, each one surrounded by a thin white frame with letters attached that spell the name of the objects
Max Gruber / Better Images of AI / Banana / Plant / Flask / Licenced by CC-BY 4.0

Better Images of AI is coordinated by We and AI and includes research, development and artistic input from BBC R&D, with academic partners Leverhulme Centre for the Future of Intelligence. Founding supporters of the initiative include the Ada Lovelace Institute, The Alan Turing Institute, The Institute for Human-Centred AI, Digital Catapult, International Centre for Ethics in the Sciences and Humanities (IZEW), All Tech is Human, Feminist Internet and the Finnish Center for Artificial Intelligence (FCAI). These organisations will advise on the creation of images, ensuring that social and technical considerations and expertise underpin the creation and distribution of compelling new images.

Octavia Reeve, Interim Lead, Ada Lovelace Institute said:

“The images that depict AI play a fundamental role in shaping how we perceive it. Those perceptions shape the ways AI is built, designed, used and adopted. To ensure these technologies work for people and society we must develop more representative, inclusive, diverse and realistic images of AI. The Ada Lovelace Institute is delighted to be a Founding Supporter of the Better Images of AI initiative.”

Dr. Kanta Dihal, Senior Research Fellow at the Leverhulme Centre for the Future of Intelligence, University of Cambridge said:

“Images of white plastic androids, Terminators, and blue brains have been increasingly widely criticized for misinforming people about what AI is, but until now there has been a huge lack of suitable alternative images. I am incredibly excited to see the Better Images of AI project leading the way in providing these alternatives.”

Dr. Charlotte Webb, Co-founder of Feminist Internet said: 

“The images we use to describe and represent AI shape not only how it is understood in the public imaginary, but also how we build, interact with and subvert it. Better Images is trying to intervene in the picturing of AI so we can expand beyond the biases and lack of imagination embedded in today’s stock imagery.”  

Professor Teemu Roos, Finnish Center for Artificial Intelligence, University of Helsinki said:

Images are not just decoration – especially in today’s fast-paced media environment, headlines and illustrations count at least as much as the actual story. But while it’s easy to call out bad stock photos, it’s very hard to find good alternatives. I’m extremely happy to see an initiative like the Better Images of AI filling a huge gap in the way we can communicate about AI without perpetuating harmful misconceptions and mystification of AI.

David Ryan Polgar, Founder and Director of All Tech Is Human said:

“Visual representation of artificial intelligence greatly influences our overall conception of how AI is impacting society, along with signalling inclusion of who is, and who should be, involved in the process. Given the ubiquitous nature of AI and its broad impact on most every aspect of our lives, Better Images of AI is a much-needed shift away from the intimidatingly technical and often mystical portrayal of AI that assumes an unwarranted neutrality. AI is made by humans and all humans should feel welcome to participate in the conversation around it.”

Tania Duarte, Co-Founder of We and AI said:

“We have found that misconceptions about AI make it hard for people to be aware of the impact of AI systems in their lives, and the human agency behind them. Myths about sentient robots are fuelled by the pictures they see, which are overhyped, futuristic, colonial, and distract from the real opportunities and issues. That’s why We and AI are so pleased to have coordinated this project which will build greater public engagement with AI, and support more trustworthy AI.”

The Better Images of AI project has so far been funded by volunteers at We and AI and BBC R&D, and now invites sponsors, donations in kind and other support in order to grow the repository and ensure that more images from artists from underrepresented groups, and from the global south can be included. 

Better Images of AI invites interest from organisations who wish to know more about the briefs developed as part of the project and to get involved in working with artists to represent their AI projects. They also wish to make contact with artists and art organisations who are interested in joining the project.

Contact

For further information: info (at) betterimagesofai.org

For funding offers: tania.duarte (at) weandai.org

Website: https://www.betterimagesofai.org

Twitter: https://twitter.com/ImagesofAI

Notes

We and AI are a UK non-profit organisation engaging, connecting and activating communities to make AI work for everybody. Their volunteers develop programmes including the Race and AI Toolkit, and AI Literacy & AI in Society workshops. They support a greater diversity of people to get involved in shaping the impact and opportunities of AI systems.
Website: https://weandai.org/ Email: hello (at) weandai.org

Better Images of AI’s first Artist: Alan Warburton

A photographic rendering of a young black man standing in front of a cloudy blue sky, seen through a refractive glass grid and overlaid with a diagram of a neural network

In working towards providing better images of AI, BBC R&D are commissioning some artists to create stock pictures for open licence use. Working with artists to find more meaningful and helpful yet visually compelling ways to represent AI has been at the core of the project.

The first artist to complete his commission is London-based Alan Warburton. Alan is a multidisciplinary artist exploring the impact of software on contemporary visual culture. His hybrid practice feeds insight from commercial work in post-production studios into experimental arts practice, where he explores themes including digital labour, gender and representation, often using computer-generated images (CGI). 

His artwork has been exhibited internationally at venues including BALTIC, Somerset House, Ars Electronica, the National Gallery of Victoria, the Carnegie Museum of Art, the Austrian Film Museum, HeK Basel, Photographers Gallery, London Underground, Southbank Centre and Channel 4. Alan is currently doing a practice-based PhD at Birkbeck, London looking at how commercial software influences contemporary visual cultures.

Warburton’s first encounters with AI are likely familiar to us all through the medium of disaster and science fiction films that presented assorted ideas of the technology to broad audiences through the late 1990s and early 2000s. 

As an artist, Warburton says it is over the past few years that technological examples have jumped out for him to help create his work. “In terms of my everyday working life, I suppose that rendering – the process of computing photorealistic images – has always been an incredibly slow and complex process but in the last four or five years various pieces of software that are part of the rendering  process have begun to incorporate AI technologies in increasing degrees,” he says. “AI noise reduction or things like rotoscoping are affected as the very mundane labour-intensive activities involved in the work of an animator and visual effects artists or image manipulator have been sped up. 

“AI has also affected me in the way it has affected everyone else through smart phone technology and through the way I interact with services provided by energy companies or banks or insurance people. Those are the areas that are more obscured, obtuse or mysterious because you don’t really see the systems. But with image processing software I have an insight into the reality of how AI is being used.” 

Warburton’s knowledge of software and AI tools has ensured that he is able to critically analyse which tools are beneficial. “I have been quite discriminatory in the way I use AI tools. There’s workflow tools that speed things up as well as image libraries and 3D model libraries. But the latter ones provide politically charged content even though it’s not positioned as such. Presets available in software will give you white skinned caucasian bodies and allow you to photorealistically simulate people but, for example, there’s hair simulation algorithms that default to caucasian hair. There’s this variegated tapestry of AI software tools, libraries, databases that you have to be discriminatory in the use of or be aware of the limitations and bias and voice those criticisms.” 

The artist’s personal use of technology is also careful and thought through. “I don’t have my face online,” he says. “There’s no content of me speaking online, I don’t have photographs online. That’s slightly unusual for someone who works as an artist and has necessary public engagement as part of my job, but I’m very aware that anything I put online can be used as training data –  if it’s public domain (materials available to the public as a whole, especially those not subject to copyright or other legal restrictions) then it’s fair game.

“Whilst my image is unlikely to be used for nefarious ends or contribute directly to a problematic database, there’s a principle that I stick to and I have stuck to for a very long time. There’s some control over my data, my presence and my image that I like to police although I am aware that my data is used in ways that I don’t understand. Keeping control over that data requires labour, you have to go through all of the options in consent forms and carefully select what you are willing to give away and not. Being discriminatory about how your data is used to construct powerful systems of control and AI is a losing game. You have to some extent to accept that your participation with these systems relies on you giving them access to your data.”

When it comes to addressing the issues of AI representation in the wider world, Warburton can see the issues that need to be solved and acknowledges that there is no easy answer. “Over the past five or ten years we have had waves of visual interpretations of our present moment,” he says. “Unfortunately many of those have reached back into retro tropes. So we’ve had vaporwave and post-internet aesthetics and many different Tumblr vibes trying to frame the present visual culture or the technological now but using retro imagery that seemed regressive. 

“We don’t have a visual language for a dematerialised culture.”

“We don’t have a visual language for a dematerialised culture. It’s very difficult to represent the culture that comes through the conduit of the smartphone. I think that’s why people have resorted to these analogue metaphors for culture. We may have reached the end of these attempts to describe data or AI culture, we can’t use those old symbols anymore and yet we still don’t have a popular understanding of how to describe them. I don’t know if it’s even possible to build a language that describes the way data works. Resorting to metaphor seems like a good way of solving that problem but this also brings in the issue of abstraction and that’s another problem.”

Alan’s experience and interest in this field of work have led to some insightful and recognisable visualisations of how AI operates and what is involved, which can act as inspiration for other artists with less knowledge of the technology. Future commissions from BBC R&D for the Better Images of AI project will enable other artists to use their different perspectives to help evolve this new visual language for dematerialised culture.

Nel blu dipinto di blu; or the “anaesthetics” of stock images of AI

Most of the criticism concerning stock images of AI focuses on their cliched and kitschy subjects. But what if a major ethical problem was not in the subjects but rather in the background? What if a major issue was, for instance, the abundant use of the color blue in the background of these images? This is the thesis we would like to discuss in detail in this post.

Stock images are usually ignored by researchers because they are considered the “wallpaper” of our consumer culture. Yet, they are everywhere. Stock images of emerging technologies such as AI (but also quantum computing, cloud computing, blockchain, etc.) are widely used, for example, in science communication and marketing contexts: conference announcements, book covers, advertisements for university masters, etc. There are at least two reasons for us to take these images seriously.

The first reason is “ethical-political” (Romele, forthcoming). It is interesting to note that even the most careful AI ethicists pay little attention to the way AI is represented and communicated, both in scientific and popular contexts. For instance, a volume of more than 800 pages like the Oxford Handbook of Ethics of AI (Dubber, Pasquale, and Das 2020) does not contain any chapter dedicated to the representation and communication, textual or visual, of AI; however, the volume’s cover image is taken from iStock, a company owned by Getty Images. 1 The subject of it is a classic androgynous face made of “digital particles” that become a printed circuit board. The most interesting thing about the image, however, is not its subject (or figure, as we say in art history) but its background, which is blue. I take this focus on the background rather than the figure from the French philosopher Georges Didi-Huberman (2005) and, in particular, from his analysis of Fra Angelico’s painting.

Fresco “Annunciation” by Fra Angelico in San Marco, Florence (Public domain, via Wikimedia Commons)

Didi-Huberman devotes some admirable pages to Fra Angelico’s use of white in his fresco of the Annunciation painted in 1440 in the convent of San Marco in Florence. This white, present between the Madonna and the Archangel Gabriel, spreads not only throughout the entire painting but also throughout the cell in which the fresco was painted. Didi-Huberman’s thesis is that this white is not a lack, that is, an absence of color and detail. It is rather the presence of something that, by essence, cannot be given as a pure presence, but only as a “trace” or “symptom”. This thing is none other than the mystery of the Incarnation. Fra Angelico’s whiteness is not to be understood as something that invites absence of thought. It is rather a sign that “gives rise to thought,”2 just as the Annunciation was understood in scholastic philosophy not as a unique and incomprehensible event, but as a flowering of meanings, memories, and prophecies that concern everything from the creation of Adam to the end of time, from the simple form of the letter M (Mary’s initial) to the prodigious construction of the heavenly hierarchies. 

A glimmering square mosaic with dark blue and white colors consisting of thousands of small pictures

The image above collects about 7,500 images resulting from a search for “Artificial Intelligence” in Shutterstock. It is an interesting image because, with its “distant viewing,” it allows the background to emerge on the figure. In particular, the color of the background emerges. Two colors seem to dominate these images: white and blue. Our thesis is that these two colors have a diametrically opposed effect to Fra Angelico’s white. If Fra Angelico’s white is something that “gives rise to thought,” the white and blue in the stock images of AI have the opposite effect.

Consider the history of blue as told by French historian Michel Pastoureau (2001). He distinguishes between several phases of this history: a first phase, up to the 12th century, in which the color was almost completely absent; an explosion of blue between the 12th and 13th centuries (consider the stained glass windows of many Gothic cathedrals); a moral and noble phase of blue (in which it became the color of the dress of Mary and the kings of France); and finally, a popularization of blue, starting with Young Werther and Madame Bovary and ending with the Levi’s blue jeans industry and the company IBM, which is referred to as the Big Blue. To this day, blue is the statistically preferred color in the world. According to Pastoureau, the success of blue is not the expression of some impulse, as could be the case with red. Instead, one gets the impression that blue is loved because it is peaceful, calming, and anesthetizing. It is no coincidence that blue is the color used by supranational institutions such as UN, UNESCO, and European Community, as well as Facebook and Meta, of course. In Italy, the police force is blue, which is why policemen are disdainfully called “Smurfs”.

If all this is true, then the problem with stock AI images is that, instead of provoking debate and “disagreement,” they lead the viewer into forms of acceptance and resignation. Rather than equating experts and non-experts, encouraging the latter to influence innovation processes with their opinions, they are “screen images”—following the etymology of the word “screen,” which means “to cover, cut, and separate”. The notion of “disagreement” or “dissensus” (mésentente in French) is taken from another French philosopher, Jacques Rancière (2004), according to whom disagreement is much more radical than simple “misunderstanding (malentendu)” or “lack of knowledge (méconnaissance)”. These, as the words themselves indicate, are just failures of mutual understanding and knowledge that, if treated in the right way, can be overcome. Interestingly, much of the literature interprets science communication precisely as a way to overcome misunderstanding and lack of knowledge. Instead, we propose an agonistic model of science communication and, in particular, of the use of images in science communication. This means that these images should not calm down, but rather promote the flourishing of an agonistic conflict (i.e., a conflict that acknowledges the validity of the opposing positions but does not want to find a definitive and peaceful solution to the conflict itself).3 The ethical-political problem with AI stock images, whether they are used in science communication contexts or popular contexts, is then not the fact that they do not represent the technologies themselves. If anything, the problem is that while they focus on expectations and imaginaries, they do not promote individual or collective imaginative variations, but rather calm and anesthetize them.

This brings me to my second reason for talking about stock images of AI, which is “aesthetic” in nature. The term “aesthetics” should be understood here in an etymological sense. Sure, it is a given that these images, depicting half-flesh, half-circuit brains, variants of Michelangelo’s The Creation of Adam in human-robot version, etc., are aesthetically ugly and kitschy. But here I want to talk about aesthetics as a “theory of perception”—as suggested by the Greek word aisthesis, which means precisely “perception”. In fact, we think there is a big problem with perception today, particularly visual perception, related to AI. In short, I mean that AI is objectively difficult to depict and hence make visible. This explains, in our opinion, the proliferation of stock images.

We think there are three possible ways to depict AI (which is mostly synonymous with machine learning) today: (1) the first is by means of the algorithm, which in turn can be embedded in different forms, such as computer code or a decision tree. However, this is an unsatisfactory solution. First, because it is not understandable to non-experts. Second, because representing the algorithm does not mean representing AI: it would be like saying that representing the brain means representing intelligence; (2) the second way is by means of the technologies in which AI is embedded: drones, autonomous vehicles, humanoid robots, etc. But representing the technology is not, of course, representing AI: nothing actually tell us that this technology is really AI-driven and not just an empty box; (3) finally, the third way consists of giving up representing the “thing itself” and devoting ourselves instead to expectations, or imaginaries. This is where we would put most of the stock images and other popular representations of AI.4

Now, there is a tendency among researchers to judge (ontologically, ethically, and aesthetically) images of AI (and of technologies in general) according to whether they represent the “thing itself” or not. Hence, there is a tendency to prefer (1) to (2) and (2) to (3). An image is all the more “true,” “good,” and “aesthetically appreciable” the closer it is (and therefore the faithful it is) to the thing it is meant to represent. This is what we call “referentialist bias”. But referentialism, precisely because of what we said above, works poorly in the case of AI images, because none of these images can really come close to and be faithful to AI. Our idea is not to condemn all AI images, but rather to save them, precisely by giving up referentialism. If there is an aesthetics (which, of course, is also an ethics and ontology) of AI images, its goal is not to depict the technology itself, namely AI. If anything, it is to “give rise to thought,” through depiction, about the “conditions of possibility” of AI, i.e., its techno-scientific, social-economic, and linguistic-cultural implications.

Alongside theoretical work such as the one we discuss above, we also try to conduct empirical research on these images. We showed earlier an image that is the result of quali-quantitative analysis we have conducted on a large dataset of stock images. In this work, we first used the web crawler Shutterscrape, which allowed us to download massive numbers of images and videos from Shutterstock. We obtained about 7,500 stock images for the search “Artificial Intelligence”. Second, we used PixPlot, a tool developed by Yale’s DH Lab.5 The result is accessible through the link in the footnote.6 The map is navigable: you can select one of the ten clusters created by the algorithm and, for each of them, you can zoom and de-zoom, and choose single images. We also manually labeled the clusters with the following names: (1) background, (2) robots, (3) brains, (4) faces and profiles, (5) labs and cities, (6) line art, (7) Illustrator, (8) people, (9) fragments, and (10) diagrams.

On a black background thousands of small pixel-like images floating similar to the shape of a world map

Finally, there’s another little project of which we are particularly fond. It is the Instagram profile ugly.ai.7 Inspired by existing initiatives such as the NotMyRobot!8 Twitter profile and blog, ugly.ai wants to monitor the use of AI stock images in science communication and marketing contexts. The project also aims to raise awareness among both stakeholders and the public of the problems related to the depiction of AI (and other emerging technologies) and the use of stock imagery for it.

In conclusion, we would like to advance our thesis, which is that of an “anaesthetics” of AI stock images. The term “anaesthetics” is a combination of “aesthetics” and “anesthetics.” By this, we mean that the effect of AI stock images is precisely one that, instead of promoting access (both perceptual and intellectual) and forms of agonism in the debate about AI, has the opposite consequence of “putting them to sleep,” developing forms of resignation in the general public. Just as Fra Angelico’s white expanded throughout the fresco and, beyond the fresco, into the cell, so it is possible to think that the anaesthetizing effects of blue expand to the subjects, as well as to the entire media and communication environment in which these AI images proliferate.

Footnotes

  1. https://www.instagram.com/p/CPH_Iwmr216/. Also visible at https://www.oxfordhandbooks.com/view/10.1093/oxfordhb/9780190067397.001.0001/oxfordhb-9780190067397.
  2.  The expression is borrowed from Ricoeur (1967)
  3.  On the agonistic model, inspired by Chantal Mouffe’s philosophy, in science and technology, see Popa, Blok, and Wessenlink (2020)
  4. Needless to say, this is an idealistic distinction, in the sense that these levels are mostly overlapping: algorithm codes are colored, drones fly over green fields and blue skies that suggest hope and a future for humanity, and stock images often refer, albeit vaguely, to existing technologies (touch screens, networks of neurons, etc.)
  5.  https://github.com/YaleDHLab/pix-plot
  6. https://rodighiero.github.io/AI-Imaginary/# Another empirical work, which we did with other colleagues (Marta Severo —Paris Nanterre University, Olivier Buisson —Inathèque and Claude Mussou —Inathèque) consisted in using a tool called Snoop, developed by the French Audiovisual Archive (INA) and the French National Institute for Research in Digital Science and Technology (INRIA), and also based on an AI algorithm. While with PixPlot the choice of the clusters is automatic, with Snoop the classes are decided by the researcher and the class members are found by the algorithm. With Snoop, we were able to fine-tune PixPlot’s classes, and create new ones. For instance, we have created the class “white robots” and, within this class, the two subclasses of female and infantine robots.
  7. https://www.instagram.com/ugly.ai/
  8. https://notmyrobot.home.blog/

References

Dubber, M., Pasquale, F., and Das, S. 2020. The Oxford Handbook of Ethics of AI. Oxford: Oxford University Press. 

Pastoureau, M. 2001. Blue: The History of a Color. Princeton: Princeton University Press.

Popa, E.O., Blok, V. & Wessenlik, R. 2020. “An Agonistic Approach to Technological Conflict”. Philosophy & Technology.

Rancière, J. 2004. Disagreement: Politics and Philosophy. Minneapolis: Minnesota University Press.

Ricoeur, P. 1967. The Symbolism of Evil. Boston: Beacon Press.Romele, A. forthcoming. “Images of Artificial Intelligence: A Blind Spot in AI Ethics”. Philosophy & Technology.

Image credits

Title image showing the painting “l’accord bleu (RE 10)”, 1960 by Yves Klein, photo by Jaredzimmerman (WMF), CC BY-SA 3.0 https://creativecommons.org/licenses/by-sa/3.0, via Wikimedia Commons

About us

Alberto Romele is research associate at the IZEW, the International Center for Ethics in the Sciences and Humanities at the University of Tübingen, Germany. His research focuses on the interaction between philosophy of technology, digital studies, and hermeneutics. He is the author of Digital Hermeneutics (Routledge, 2020).

Dario Rodighiero is FNSF Fellow at Harvard University and Bibliotheca Hertziana. His research focuses on data visualization at the intersection of cultural analytics, data science, and digital humanities. He is also lecturer at Pantheon-Sorbonne University, and recently he authored Mapping Affinities (Metis Presses 2021).

The AI Creation Meme

A robot hand and a human hand reaching out with their fingertips towards each other

This blog post is based on Singler, B (2020) “The AI Creation Meme: A Case Study of the New Visibility of Religion in Artificial Intelligence Discourse” in Religions 2020, 11(5), 253; https://doi.org/10.3390/rel11050253


Few images are as recognisable or as frequently memed as Michelangelo’s Creazione di Adamo (Creation of Adam), a moment from his larger artwork that arches over the Sistine Chapel in Vatican City. Two hands, fingers nearly touching, fingertip to fingertip, a heartbeat apart in the moment of divine creation. We have all seen it reproduced with fidelity to the original or remixed with other familiar pop-culture forms. We can find examples online of god squirting hand sanitiser into Adam’s hand for a Covid-era message. Or a Simpsons cartoon version with Homer as god, reaching out towards a golden remote control. Or George Lucas reaching out to Darth Vader. This creation moment is also reworked into other mediums: the image has been remade with paperclips, satsuma sections, or embroidered as a patch for jeans. Some people have tattooed the two hands nearly touching on their skin, bringing it into their bodies. The diversity of uses and re-uses of the Creation of Adam speak to its enduring cultural impact.

The creation of Adam by Michelangelo
Photography of Michelangelo’s fresco painting “The creation of Adam” which forms part of the Sistine Chapel’s ceiling

My particular interest in the meme-ing of the Creation of Adam is because of its ‘AI Creation’ form, which I have studied by collecting a corpus of 79 indicative examples found online (Singler 2020a). As with some of the above examples, the focus is often narrowed to just the hands and forearms of the subjects. The representation of AI in my corpus came in two primary forms: an embodied robotic hand or a more ethereal, or abstract, ‘digital’ hand. The robotic hands were either jointed white metal and plastic hands or fluid metallic hands without joints – reminiscent of the liquid, shapeshifting, T-1000 model from Terminator 2: Judgement Day (1991). In examples with digital hands, they were either formed with points of light or vector lines. The human hands in the AI Creation Meme also had characteristics in common: almost all were male and Caucasian in skin tone. Some might argue that this replicates how Michelangelo and his contemporaries envisaged Adam and the Abrahamic god. But if we can re-imagine these figures in Simpson’s yellow or satsuma orange, then there are intentional choices being made here about race, representation, and privilege.

The colour blue was also significant in my sample. Grieser’s work (2017) on the popularity of Blue Brains in neuroscience imagery, which applies an “aesthetics of religion” approach, was relevant to this aspect of the AI Creation Meme. She argues that such colour choices and their associations – for instance, blue with “seriousness and trustworthiness”, the celestial and heavenly, and its opposition to dark and muted colours and themes – “target the level of affective attitudes rather than content and arguments” (Grieser 2017, p260). Background imagery also targeted affective attitudes: cosmic backgrounds of galaxies and star systems, cityscapes with skyscrapers, walls of binary text, abstract shapes in patterns such as hexagons, keyboards, symbols representing the fields that employ AI, and more abstract shapes in the same blue colour palette. The more abstract examples were used in more philosophical spaces, while the more business-orientated meme remixes were found more often on business, policy, and technology-focused websites, suggesting active choice in aligning the specific AI Creation meme with the location in which it was used. These were frequently spaces commonly thought of as ‘secular’ – technology and business publications, business consultancy firms, blog posts about fintech, bitcoin, eCommerce, or the future of eCommerce, or the future of work. What then of the distinction between the religious and the secular?

That the original Creation of Adam is a religious image is without question – although its obviously specific to a specific view of a monotheistic god. As a part of the larger work in the Sistine chapel, it was intended to “introduce us to the world of revelation”, according to Pope John Paul II (1994). But such images are not merely broadcasting a message; meaning-making is an interactive event where the “spectator’s well of previous experiences” interplays with the object itself (Helmers 2004, p 65). When approaching an AI Creation Meme, we bring our own experiences and assumptions, including the cultural memory of the original form of the image and its message of monotheistic creation. This is obviously culturally specific, and we might think about what a religious AI Creation Meme from a non-monotheistic faith would look like, as well as who is being excluded in this imaginary of the creation of AI. But this particular artwork has had impact across the world. Even in the most remixed form, we know broadly who is meant to be the Creator and who is the Created, and that this moment is intended to be the very act of Creation.

Some of the AI Creation Memes even give greater emphasis to this moment, with the addition of a ‘spark of life’ between the human hand and the AI hand. The cultural narrative of the ‘spark of life’ likely begins with the scientific works of Luigi Galvani (1737 – 1789). He experimented with animating dead frogs’ legs with electricity and likely inspired Mary Shelley’s Frankenstein. In the 19th Century, the ‘spark of life’ then became a part of the account of the emergence of all life on earth from the ‘primordial soup’ of “ammonia and phosphoric salts, lights, heat, electricity etc.” (Darwin 1871). Grieser also noted such sparks in her work on ‘Blue Brain’ imagery in neuroscience, arguing that such motifs can be seen as perpetuating the aesthetic forms of a “religious history of electricity”, which involves visualising conceptions of communication with the divine (Grieser 2017, p. 253).

Finding such aesthetics, informed by ideology, in what are commonly thought of as ‘secular’ spaces, problematises the distinction between the secular and the religious. In the face of solid evidence against a totalising secularisation and in favour of religious continuity and even flourishing, some interpretations of secularisation have instead focused on how religions have lost control over their religious symbols, rites, narratives, tropes and words. So, we find figures in AI discourse such as Ray Kurzweil being proclaimed ‘a Prophet’, or people online describing themselves as being “Blessed by the Algorithm” when having a particularly good day as a gig economy worker or a content producer, or in general (Singler 2020). These are the religious metaphors we also live by, to paraphrase Lakoff and Johnson (1980).

The virality of humour and memetic culture is also at play in the AI Creation Meme. I’ve mentioned some of the examples where the original Creation Meme is remixed with other pop culture elements, leading to absurdity (the satsuma creation meme is a new favourite of mine!). The AI Creation Meme is perhaps more ‘serious’ than these, but we might see the same kind of context-based humour being expressed through the incongruity of replacing Adam with an AI. Humour though can lead legitimation through a snowballing effect, as something that is initially flippant or humorous can become an object that is indicated towards in more serious discourse. I’ve previously made this argument in relation to New Religious Movements that emerge from jokes or parodies of religion (Singler 2014), but it is also applicable to religious imagery used in unexpected places that gets a conversation started or informs the aesthetics of an idea, such as AI.

The AI Creation meme also inspires thoughts of what is being created. The original Creation of Adam is about the origin of humanity. In the AI Creation Meme, we might be induced to think about the origins of post-humanity. And just as the original Creation of Adam leads us to think on fundamental existential questions, the AI Creation Meme partakes of posthumanism’s “repositioning of the human vis-à-vis various non-humans, such as animals, machines, gods, and demons” (Sikora 2010, p114), and it leads us into questions such as ‘Where will the machines come from?’, ‘What will be our relationship with them?’, and the apocalyptic again, ‘what will be at the end?’. Subsequent calls for our post-human ‘Mind Children’ to spread outwards from the earth might be critiqued as the “seminal fantasies of [male] technology enthusiasts” (Boss 2020, p39), especially as, as we have noted, the AI Creation Meme tends to show ‘the Creator’ as a white male.

However, there are opportunities in critiquing these tendencies and tropes; as with the post-human narrative, we can be alert to what Graham describes as the “contingencies of the boundaries by which we separate the human from the non-human, the technological from the biological, artificial from natural” (2013, p1). Elsewhere I have remarked on the liminality of AI itself and how we might draw on the work of anthropologists such as Victor Turner and Mary Douglas, as well as the philosopher Julia Kristeva, to understand how AI is conceived of, sometimes apocalyptically, as a ‘Mind out of Place” (Singler 2019) as people attempt to understand it in relation to themselves. Paying attention to where and how we force such liminal beings and ideas into specific shapes and what those shapes are can illuminate our preconceptions and biases.

Likewise, the common distinction between the secular and the religious is problematised by the creative remixing of the familiar and the new in the AI Creation Meme. For some, a boundary between these two ‘domains’ is a moral necessity; some see religion as a pernicious irrationality that should be secularised out of society for the sake of reducing harm. There can be a narrative of collaboration in AI discourse, a view that the aims of AI (the development and improvement of intelligence) and the aims of atheism (the end of irrationalities like religion) are sympathetic and build cumulatively upon each other. So, for some, illustrating AI with religious imagery can be anathema. Whether or not we agree with that stance, we can use the AI Creation Meme as an example to question the role of such images in how the public comes to trust or distrust AI. For some, AI as a god or as the ‘child’ of humankind is a frightening idea. For others, it is reassuring and utopian. In either case, this kind of imagery might obscure the reality of current AI’s very un-god-like flaws, the humans currently involved in making and implementing AI, and what biases these humans have that might lead to very real harms.


Bibliography

Boss, Jacob 2020. “For the Rest of Time They Heard the Drum.” In Theology and Westworld. Edited by Juli Gittinger and Shayna Sheinfeld. Lanham, MD: Rowman & Littlefield.

Darwin, Charles 1871. “Letter to Joseph Hooker.” in The Life and Letters of Charles Darwin, Including an Autobiographical Chapter. London, UK: John Murray, vol. 3, p. 18.

Graham, Elaine 2013. “Manifestations of The Post-Secular Emerging Within Discourses Of Posthumanism.” Unpublished Conference Presentation Given at the ‘Imagining the Posthuman’ Conference at Karlsruhe Institute of Technology, July 7–8. Available online: http://hdl.handle.net/10034/297162 (accessed 3 April 2020).

Grieser, Alexandra 2017. “Blue Brains: Aesthetic Ideologies and the Formation of Knowledge Between Religion and Science.” In Aesthetics of Religion: A Connective Concept. Edited by A. Grieser and J. Johnston. Berlin and Boston: De Gruyter.

Helmers, Marguerite 2004. “Framing the Fine Arts Through Rhetoric”. In Defining Visual Rhetoric. Edited by Charles Hills and Maguerite Helmers. Mahweh: Lawrence Erlbaum, pp. 63–86.

Lakoff, George, and Johnson, Mark (1980) Metaphors we Live by, Chicago, USA: University of Chicago Press

Pope John Paul II. 1994. “Entriamo Oggi”, homily preached in the mass to celebrate the unveiling of the restorations of Michelangelo’s frescoes in the Sistine Chapel, 8 April 1994, available at http://www.vatican.va/content/john-paul-ii/en/homilies/1994/documents/hf_jpii_ hom_19940408_restauri-sistina.html (accessed on 19 May 2020)

Sikora, Tomasz 2010. “Performing the (Non) Human: A Tentatively Posthuman Reading of Dionne Brand’s Short Story ‘Blossom’”. Available online: https://depot.ceon.pl/handle/123456789/2190 (accessed 30 March 2020).

Singler, Beth 2020. “‘Blessed by the Algorithm’: Theistic Conceptions of Artificial Intelligence in Online Discourse” In Journal of AI and Society. doi:10.1007/s00146-020-00968-2.

Singler, Beth 2019. “Existential Hope and Existential Despair in AI Apocalypticism and Transhumanism” in Zygon: Journal of Religion and Science 54: 156–76.

Singler, Beth 2014 “‘SEE MOM IT IS REAL’: The UK Census, Jediism and Social Media”, in Journal of Religion in Europe, (2014), 7(2), 150-168. https://doi.org/10.1163/18748929-00702005

AI WHAT’S THAT SOUND? Stories and Sonic Framing of AI

An artistically distorted image of colorful sound waves containing no robots or other clichee representation of AI

The ‘Better Images of AI’ project is so important, as typically, portrayals of AI can be seen to reinforce established and polarised views, which can distract from the pressing issues of today, but we rarely question how AI sounds…

We are researching the sonic framing of AI narratives. In this blog post, we ask, in what ways does a failure to consider the sonic framing of AI influence or undermine attempts to broaden public understanding of AI? Based on our preliminary impressions, we argue that the sonic framing of AI is just as important as other narrative features and propose a new programme of research. We use some brief examples here to explore this.

The role of sonic framing on AI narratives and public perception

Music is useful. We employ music every day to change how we feel, how we think, to distract us, to block out unwanted sound, to help us run faster, to relax, to help us understand, and to send signals to others. Decades of music psychology research have already parsed the many roles music can serve in our everyday lives. Indeed, the idea that music is ‘functional’ or somehow useful has been with us since antiquity. Imagine receiving a cassette tape in the post from someone filled with messages of love: music transmits information and messages. Music can also be employed to frame how we feel about things. Or, written another way, music can manipulate how we feel about certain people, concepts, or things. As such, when we decide to use music to ‘frame’ how we wish a piece of storytelling to be perceived, attention and scrutiny should be paid to the resonances and emotional overtones that music brings to a topic. AI is one such topic and a topic that is heavily subject to hype. This is arguably an inevitable condition of innovation at least at inception, but while the future with AI is so clearly shaped by stories told about AI, the music chosen may also ‘obscure views of the future.’

Affective AI and its role in storytelling

30 years ago, documentarian Michael Rabiger quite literally wrote the book on documentary filmmaking. Now in it’s 7th edition, Directing the Documentary explores the role and responsibility of the filmmaker in presenting factual narratives to an audience. Crucially, Rabiger discusses the use of music in documentary film saying it should never be used to ‘inject false emotion’ thus giving the audience an unreal or amplified or biased view of proceedings. What is the function of a booming calamitous impact sound signalling the obliteration of all humankind at the hands of a robot if not to inject falsified or heightened emotion? Surely this serves only to reinforce dominant narratives of fear and robot uprising – the likes of science fiction. If we are to live alongside AI, as we are already doing, we must consider ways to promote positive emotions to move us away from the human vs machine tropes which are keeping us, well, stuck.

Moreover, we wonder about the notions of authenticity, transparency and explainability. Despite attempts to increase AI literacy through citizen science and initiatives about AI explainability, documentaries and think pieces that promote public engagement with AI and purport to promote ‘understanding’ are often riddled with issues of authenticity or a lack of transparency doing precisely nothing to educate the public. Complex concepts like neural nets, quantum computing, Bayesian probabilistic networks etc. must be reduced (necessarily so) to a level whereby a non-specialist viewer can glean some understanding of the topic. In this course retelling of ‘facts’, composers and music supervisors have an even more crucial role in aiding nuanced comprehension; yet we find ourselves faced with the current trend for bombast, extravagance and bias when it comes to soundtracking AI. Indeed, as much as attention needs to be paid to those who are creating AI technologies to mitigate a creeping bias, attention also needs to be paid to those who are composing music for the same reasons.

Eerie AI?

Techno-pessimism is reinforced by portrayals of AI in visual and sound media – suggestive of a dystopian future. Eerie music in film, for instance, can reinforce a view of AI uprising or express some form of subtle manipulation by AI agents. Casting an ear over the raft of AI documentaries in recent years, we can observe the trend for approaches to sonic framing which reinforce dominant tropes. At the extreme, Mark Crawford’s original score from Netflix’s The Social Dilemma (which is a documentary/drama) is a prime example of this in action. A track titled ‘Am I Really That Bad?’ begins as a childish waltz before gently morphing into a disturbing carnival-esque horror soundtrack. The following track ‘Server Room’ is merely a texture full of throbbing basses, Hitchcock-style string screeches, atonal vibraphones, and rising tension that serves only to make the listener uncomfortable. Alternatively, ‘Theremin Lullaby’ offers up luscious utopian piano textures Max Richter would be proud of, before plunging us into ‘The Sliding Scale’, a cut that comes straight from Tron: Legacy with its chugging bass and blasts of noise and static. Interestingly, in a behind the scenes interview with the composer, we learn that the ‘expert’ cast of the Social Dilemma were interviewed and guided the sound design. However, the film received much criticism for being sensationalist and the cast themselves were criticised as former tech giant employees hiding in plain sight. If these unsubtle, polarised positions are the only sonic fayre on offer, we should be questioning who is shaping music and the extent to which it is being used to actively manipulate audience impressions of AI.
Of course, there are other forms of story and documentaries about AI which are less subject to dramatisation. Some examples exist where sound designers, composers and filmmakers are employing the capabilities afforded by music to help demonstrate complex ideas and support the experience of the viewer in a nuanced manner. A recent episode of the BBC’s Click programme uses a combination of image and music to demonstrate supervised machine learning techniques to great effect. Rather than the textural clouds of utopian AI or the dystopian future hinted (or screamed) at by overly dramatic Zimmer-esque scores, the composer Bella Saer and engineer Yoad Nevo create a musical representation of the images, providing positive and negative aural feedback for the machine learning process. Here, the music transforms into a sonic representation of the processes we are witnessing being played out on the screen. Perhaps this represents the kinds of narratives society needs.
Future research

We don’t yet have the answers, only impressions. It remains a live research and development question as to how far sonic framing influences public perception of AI and we are working on documentary as a starting point. As we move closer to understanding the influence of representation in AI discourse, it surely becomes a pressing matter. Just as the BBC is building and commissioning an image repository of more inclusive and representative images of AI, we hope to provoke discussion about how we can bring together creative and technology industries to reframe how we audibly communicate and conceptualise AI.

Still, a question remains about the stories being told about AI, who is telling them and how they are told. Going forward, our research will investigate and test these ideas, by interviewing composers and sound designers of AI documentaries. As for this blog, we encourage you to pay attention to how AI sounds in the next story you are told about AI or when you see an image. We call for practitioners to dig a little deeper when sonically framing AI.


About us

Dr Jenn Chubb (@JennChubb) is Research Fellow at the University of York, now with XR Stories. She is interested in all things ethics, science and stories. Jenn is researching sonic framing of AI in narratives and sense making. Jenn plays deliberately heavy and haunting music in a band called This House is Haunted.

Dr Liam Maloney (@liamtmaloney) is an Associate Lecturer in Music & Sound Recording at the University of York. Liam is interested in music, society, disco, and what streaming is doing to our listening habits. When he has a minute to spare he also makes ambient music.

Jenn and Liam decided not to use any robot related images. Title image “soundwaves” by seth m (CC BY-NC-ND 2.0)

What does AI look like?

A grid of photos of a tree in different seasons, overlayed by a grid of white rectangles rotating in different angles

A version of this post was previously published on the BBC R&D blog by Tristan Ferne, Henry Cooke and David Man

We have noticed that news stories or press releases about AI are often illustrated with stock photos of shiny gendered robots, glowing blue brains or the Terminator. We don’t think that these images actually represent the technologies of AI and ML that are in use and being developed. Indeed, we think these are unhelpful stereotypes; they set unrealistic expectations, hinder wider understanding of the technology and potentially sow fear. Ultimately this affects public understanding and critical discourse around this increasingly influential technology. We are working towards better, less clichéd, more accurate and more representative images and media for AI.

Try going to your search engine of choice and search for images of AI. What do you get?

A screenshot of a Google image search for "Artificial intelligence" showing a wall of blueish images depicting humanoid robots and glowing blue brains

What are the issues?

The problems with stock images of AI has been discussed and analysed a number of times already and there are some great articles and papers about it that describe the issues better than we can. The Is Seeing Believing? project asks how we can evolve the visual language of AI. The Real Scandal of AI also identifies issues with stock photos. The AI Myths project, amongst other topics, includes a feature on how shiny robots are often used to represent AI.

Going a bit deeper, this article explores how researchers have illustrated AI over the decades, this paper discusses how AI is often portrayed as white “in colour, ethnicity, or both” and this paper investigates the “AI Creation” meme that features a human hand and a machine hand nearly touching. Wider issues with the portrayal and perception of AI have also been frequently studied, as by the Royal Society here.

The style of the existing images is often influenced by science fiction and there are many visual cliches of technology, such as 0s and 1s or circuit boards. The colour blue is predominant – it seems to be representing technology, but blue can also be seen as representing male-ness. The frequent representation of brains associate these images with human intelligence, although much AI and ML in use today is far removed from human intelligence. Robots occur frequently, but AI applications are very often nothing to do with robots or embodied systems. The robots are often white or they’re sexualised female representations. We also often see “evil” robots from popular culture, like the Terminator.

What is AI?

From reviewing the research literature and by interviewing AI engineers and developers we have identified some common themes which we think are important in describing AI and ML and that could help when thinking about imagery.

A grid of icons related to the 10 themes
  • AI is all based on maths, statistics and probabilities
  • AI is about finding patterns and connections in data
  • AI works at a very large scale, manipulating almost unimaginable amounts of data
  • AI is often very complex and opaque and it’s hard to explain how it works. It’s even hard for the experts and practitioners to understand exactly what’s going on inside these systems
  • Most AI systems in use today only really know about one thing, it is “narrow” intelligence
  • AI works quite differently to the human brain, in some ways it is an alien non-human intelligence
  • AI systems are artificial and constructed and coded by humans
  • AI is a sociotechnical system; it is combinations of computers and humans, creating, selecting and processing the data
  • AI is quite invisible and often hidden
  • AI is increasingly common, becoming pervasive, and affects almost all of us in so many areas. It can be powerful when connected to systems of power and affects individuals, society and the world

We would like to see more images that realistically portray the technology and point towards its strengths, weaknesses, context and applications. Maybe they could…

  • Represent a wider range of humans and human cultures than ‘caucasian businessperson’ or ‘humanoid robot’
  • Represent the human, social and environmental impacts of AI systems
  • Reflect the realistically messy, complex, repetitive and statistical nature of AI systems
  • Accurately reflect the capabilities of the technology: generally applied to specific tasks and are not of human-level intelligence
  • Show realistic applications of AI
  • Avoid monolithic or unknowable representations of AI systems
  • Avoid using electronic representations of human brains, or robots

Towards better images

In creating new stock photos and imagery we need to consider what makes a good stock photo. Why do people use them and how? Is the image representing a particular part of the technology or is it trying to tell a wider story? What emotional response should the viewers have when looking at it? Does it help them understand the technology and is it an accurate representation

Consider the visual style; a diagram, a cartoon or a photo each brings different attributes and will communicate ideas in different ways. Imagery is often used to draw attention so it may be important to create something that has impact and is recognisable. A lot of existing stock photos of AI may be misrepresentative and unhelpful, but they are distinctive and impactful and you know them when you see them.

Some of the themes we’ve seen develop from our work include:

  • Putting humans front and centre, and showing AI as a helper, a tool or something to be harnessed.
  • Showing the human involvement in AI; in coding the systems or creating the training data.
  • Positively reinforcing what AI can do, rather than showing the negative and dangerous aspects.
  • Showing the input and outputs and how human knowledge is translated into data.
  • Making the invisible visible.
  • AI getting things wrong

Some of the interesting metaphors used include sieves and filters (of data), friendly ghosts, training circus animals, social animals, like bees or ants with emergent behaviours, child-like learning or the past predicting the future.

A grid of photos of a tree in different seasons, overlayed by a grid of white rectangles rotating in different angles
A new image representing datasets, creating order and digitisation

This is just a starting point and there is much more thinking to be done, sketches to be drawn, ideas to be harnessed, definitions agreed on and metaphors minted.

A coalition of partners are working on this, including BBC R&D, We and AI, and several independent researchers and academics including Creative Technologist Alexa Steinbrück, AI Researcher Buse Çetin, Research Software Engineer Yadira Sanchez Benitez, Merve Hickok and Angela Kim. Ultimately we aim to create a collection of better stock photos for AI; we’re starting to look for artists to commission and we’re looking for more partners to work with. Please get in touch if you’re interested in working with us.

Icon credits
Complexity by SBTS from the Noun Project
Octopus by Atif Arshad from the Noun Project
pattern by Eliricon from the Noun Project
watch world by corpus delicti from the Noun Project
sts by Nithinan Tatah from the Noun Project
narrowing by andriwidodo from the Noun Project
Error 404 by Aneeque Ahmed from the Noun Project
box icon by Fithratul Hafizd from the Noun Project
Ghost by Pelin Kahraman from the Noun Project
stack by Alex Fuller from the Noun Project
Math by Ralf Schmitzer from the Noun Project
chip by Chintuza from the Noun Project