Cover image credit: Marcin Wilkowski / Better Images of AI / CC BY 4.0
Claims about the productivity and efficiency gains from generative AI can be appealing to non-profit organisations, like ours, which have no core funding and rely completely on volunteers. Yet, at Better Images of AI, productivity and efficiency are not – and should not be – prioritised over other values like human creativity, care, learning, intention, empathy, connection, respect, equity, accessibility, and sustainability – all of which have brought us together as a community.
We and AI (the non-profit organisation that we sit cosily within) have played a significant role in challenging AI hype and offering a counter-narrative to extractive AI becoming inevitable in our lives (see resources here and here). We and AI’s work has prompted us to question and reflect on whether specific use cases for generative AI align with our organisational values.
At present, Better Images of AI does not accept or support the use of generative AI to create images for our library, to aid with the writing, ideation, and editing of our blog posts, or for generating descriptions and alt text for our image cards. We operate on a default assumption that for work produced within, and for, Better Images of AI, you should not use generative AI. If our community and partners have ideas for specific use cases where generative AI could offer benefits in a way that our community of care and collaboration cannot, we can openly discuss whether this use case for generative AI may be appropriate if it also aligns with our community values and objectives.
We have adopted our stance based on the reasoning outlined in detail below. These are not absolutes, or necessarily ‘anti-AI’, but at the moment, this approach reflects our prioritisation of practices which centre community values like care, intention, empathy, respect, equity, and sustainability – values which we do not see reflected in current AI development or practices.
The use of generative AI is also counterproductive to the purposes of our library and community, which not only aim to improve the visual representation of AI but also support creators, researchers, and individuals wanting to understand and learn about AI through imagery. Automating tasks, some of which may sometimes seem mundane or administrative, may speed up processes, but in turn, takes away from the time we spend attending to details and thinking intentionally, which can undermine opportunities for us to develop critical thinking skills about AI.
We acknowledge that generative AI has been used by us in the past, for instance, when we were under the impression that Adobe Firefly was trained using consented materials (we later found out that it is not and revised our policies). However, in developing this approach, we’ve been able to learn from our creators and discussed how to embed our community values into our practices, which has ultimately led us to our current position. It is important to be honest, and we hope that in sharing this knowledge, we can be transparent about how – and why – we got here.
Additionally, increasingly, we find ourselves in spaces where ‘AI-enabled’ productivity and efficiency in writing and art are prioritised and rewarded over the content of the work itself, with many being forced to ‘leverage AI’ in projects where it is simply unhelpful or useless – or worse, actively detrimental. We are holding space for practices which actively divest from unnecessary automation and exploitation, in favour of slower, community-focused, reciprocal alternatives which support our values and focus on the enjoyment that many individuals derive from creating, reflecting, editing, and writing.
We welcome any feedback on our approach to generative AI and hope that this policy is inclusive of all members of our community and partners, while also aligning with the values at the heart of Better Images of AI, which have been informed by We and AI’s research. This blog post serves as a living page, where we hope to continuously develop/clarify/iterate our approach based on community feedback. Some of the points raised in this approach, for instance, relating to ‘AI art’ and the use of artists’ work for training data, are being discussed actively by individuals – you may wish to follow and engage with their work (see here, here, here, here, and here as some examples).
Our approach is split into three main contexts for the uses of generative AI in accordance with Better Images of AI:
- Image submissions;
- Blog posts; and
- Image cards (descriptions and alt text
For each use case or context, we outline reasons for our approach. However, for uses relating to our blog or images, we also challenge the motivations and reasons why you might want to use generative AI or assume that it is helpful. In these cases, we offer alternative non-generative AI approaches that better align with our values based on resources or existing practices that have organically, and sometimes accidentally, emerged within our community. We hope to build more resources along these lines.
As outlined in our Submission Handbook, AI-generated artworks are only eligible for submission to the library, if all of the following 3 criteria are met:
- The image generator used to create the image: (i) uses only consented works in its training data, (ii) compensates artists whose works have been used in its training data, (iii) labels all images as AI-generated.
- Original artwork by the submitting artist is used as the visual prompt and style.
- The way the image generator has been used in the process is disclosed and described within the submission form.
In practice, no generative AI image generators (that we are aware of) meet all three criteria. Therefore, images generated by models, including, but not limited to, DALLE-E, Midjourney, Stable Diffusion and Adobe Firefly are not accepted in our library. This may change, and if any AI image generators do comply with our criteria, we’d love to know. Techniques that use AI, which leave the original image intact and are not image generators, such as those found in digital editing platforms (e.g., background remove/eraser or basic filters), are permitted if they only ‘enhance’ the original image instead of transforming it (see our Submission Handbook for further explanation of how we’re thinking about the boundaries here).
Alternative to using generative AI for images?
One reason you might consider using generative AI to create images is if you feel you do not have the artistic skill or ability to create an aesthetic, compelling visual.
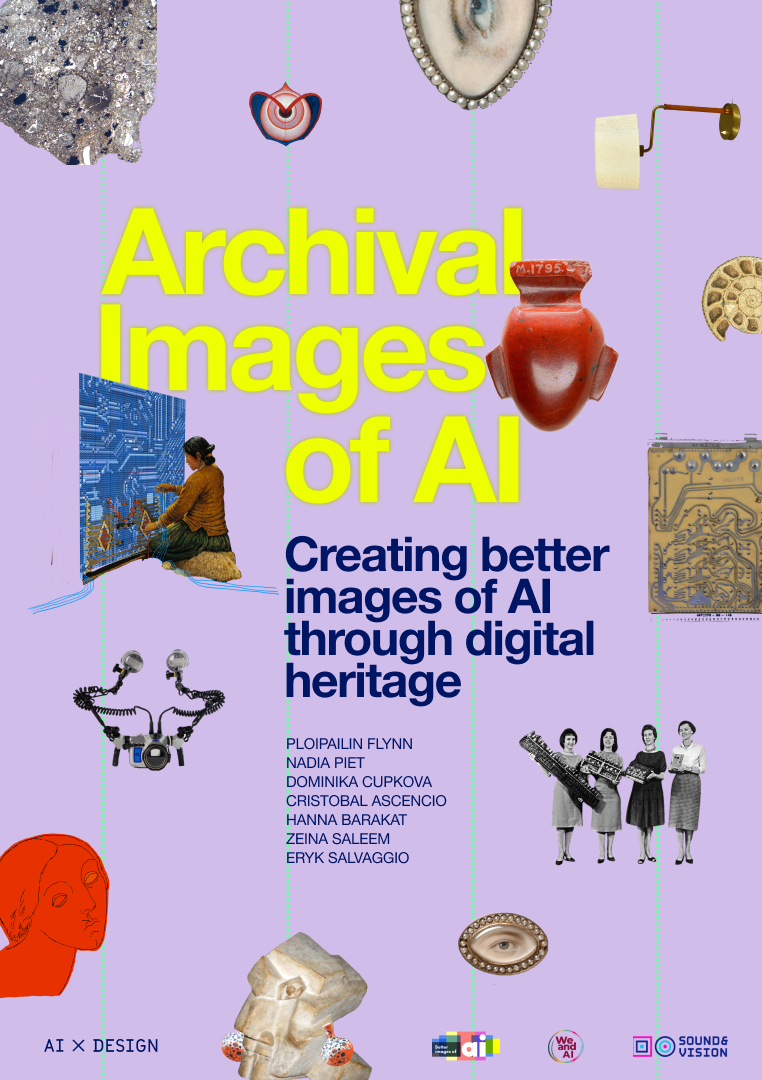
Non-generative AI alternative approach: In 2024, we released our Archival Images of AI Playbook, which provides a resource for anyone to create visuals of AI, even if you do not feel you are artistic, using collage and remixing techniques with archival materials. The Playbook not only provides tools and tips on how to remix and collage, but it also shows how using archival images can offer a more informative approach to developing meaningful visual narratives about AI. Digital heritage collections are filled with rich stories and unique textures, which can be used to create images of AI which re-imagine how we represent AI without relying on dystopian or alienating images.
Generative AI visual outputs often reinforce biases reflected in our inequitable society. Using digital heritage collections offers a more reflective approach to challenge existing narratives and can prompt us to explore and understand how they are relevant to current AI developments and practices.
Furthermore, archival images can expose past histories from marginalised communities, which can allow us to understand how systems of oppression are embedded in the context of AI. However, it can also introduce alternative understandings and approaches to AI – showing us how the current practices are not universal, or inevitable, and alternatives have existed in the past or in different geographies.
The Playbook also includes a list of public domain resources (an additional list is in our Submission Handbook too), which enable creators to explore how images outside of copyright protection can be used to create visuals for submission into our library. Although an ongoing legal question in courts around the world, generative AI text-to-image models can infringe copyright through the use of the input data to train models alongside the resulting output images.
There are numerous ethical and moral objections to using generative AI models for these reasons too, including the use of creators’ work without permission, consent or remuneration to train lucrative, proprietary models. Using public domain images, such as those found within digital heritage collections, can therefore offer a more legally compliant and ethical approach.
While we want to hold space for all creators who wish to improve the visual representations of AI, we believe we can only enable the use of AI in this process if it has been developed in ways that respect creative communities (this requires consented training data, disclosure, and remuneration). We are also deeply concerned about the environmental impact of generative AI supply chains and therefore endorse human-created artworks which do not have the same detrimental impact on our ecosystems.
In terms of content for our blog, we’re opposed to the use of AI for writing, ideation, research, grammar for many of the same reasons as we are for generating images, such as mass non-consensual use of authors’ work, biases and plagiarism, environmental factors, exploitation, as well as cognitive decline and integrity. We understand that common digital tools might have embedded AI-based features that are triggered without consent. We discourage collaborators from using these tools, for example, by disabling the AI overview on Google by adding ‘-ai’ to the end of your searches, or just by using alternative web browsers.
Alternative to using generative AI for images?
We understand that some people may use AI in the process of writing for other important reasons, such as for translation purposes. We do not wish to exclude these individuals from contributing to our blog and sharing their work with our community.
Non-generative AI alternative approach: However, instead of relying on generative AI, our community of volunteers are a nifty bunch, and we often find ways in which we can support you. For example, this blog post features an interview with an artist in her native language (Spanish) with one of our multilingual volunteers who translated the post into English. Additionally, Zoya, who manages the day-to-day running of the library, is always happy to help write up ideas, edit content, or connect you with a volunteer or two who might be able to support you (and they can also benefit from the exchange too by learning from you!).
We’re not incentivised or structured to benefit from fast, predictable, polished outputs. Instead, we value (often slower) options which can forge new human relations and offer mutual learning opportunities (even if we sometimes miss out a semi-colon, whoops!). If you’d like to use generative AI in some way to write a post for our blog, we’d love it if you can get in touch first and explain why you’re planning to use generative AI so we can learn more, understand, and see if we can help you.
Image descriptions: Since our creators do not use generative AI to create images for our library, we also believe that we should take the same consideration, time, and respect to write descriptions and alt text for the images. The process of doing so can enable us to explore the plurality of stories told by each image, while also learning and engaging with the creators’ intentions and understanding/experiences of AI.
Where we are uncertain about creative choices made or parts of the image, we can engage with the artist to learn about the image process and creation. This has the benefit of connecting our artist community with our volunteers, allowing for human connection and learning opportunities.
We have found that AI-generated image descriptions do not effectively communicate the artist’s process, and so cannot prompt us to critically think about what is represented in an image. Writing image descriptions is also a learning opportunity for volunteers, particularly new ones, who want to learn more about how AI can be visually communicated in more accurate and representative ways. Contextual elements of images, such as those informed by an artist’s own experience or understanding of AI, can be replaced or lost by using AI-generated descriptions.
In addition, material processes involved in creating the images can be lost. We encourage creators to detail any specific choices, materials, and processes taken to visualise AI, showing how all representations of AI come from somewhere, influenced by worldviews, contexts, and geographies. Our community blog also develops these descriptions to explore in more depth the human stories, challenges, intentions, research, and organisations behind images (see here, here, and here, for example).
Alt text: For alt text, we also believe that preserving human-generated text increases the accessibility of our library for people who are blind or have low vision. AI-generated alt text descriptions of images may not communicate the specific choices an artist made or parts of an image necessary to understand the representation of AI portrayed in a certain image. This is particularly relevant for images which incorporate visual metaphors, whereby a literal description may not offer the same visual experience that other users are exposed to when using our library.
Being aware of how the image is presented and the context in which it sits can give people who are blind or have low vision a better experience using our library, which supports our purpose to increase public understanding of AI. Furthermore, we are cautious of uncritical uses of AI being used to ‘increase’ accessibility in a guise to minimise costs needed to invest in changing the ways the world is designed, which exclude individuals (e.g., people with disabilities), which cannot be simply overcome by technological approaches.
Finally, as with writing descriptions, the process of writing alt text can be helpful for our volunteers to learn more about the visual communication of AI. Being able to describe images about AI often involves us undertaking research to understand the contents of the images and describe them in a way that communicates the same information from the description of an image as someone who relies on the visual experience.
While we do not currently have a resource that can help and guide creators or volunteers to write alt-text descriptions, we hope to be able to develop one in the near future, which is specific to our library and visualising AI.
We have been reflecting upon the uses of generative AI for different purposes in Better Images of AI. However, when generative AI use cases are presented to us, we continuously come to the same question:
“What can generative AI provide to Better Images of AI, aside from efficiency or productivity, that a community of care and collaboration cannot offer?”
As explored above, we have found that generative AI do not surpass the collaboration of our own community that we have developed around our values of care, learning, intention, empathy, human connection, respect, equity, accessibility, and sustainability – even if our work might be slower and not as ‘polished’.
But we genuinely welcome other people’s responses, which critique, build upon, or support our approach to generative AI in the Better Images of AI library. We exist to improve the visual representation of AI, and as part of this, we have thought about whether generative AI can play a useful role in supporting our mission. At present, we think that generative AI, as it is currently built and developed, does not.
Resources that inspired our approach
Below is a list of resources that influenced our thinking and approach. We welcome any suggestions for additional readings to add:
- ‘I found AI-versions of my art and that’s not ok’ – Instagram post, @hanna.k.l
- Resisting AI: An Anti-Fascist Approach to Artificial Intelligence – book, Dan McQuillan
- ‘Dear Robot, Make Art’ – Instagram post, @amymariestad
- A non-exhaustive collection of worth-reading books on topics strongly related to Critical AI – resource, Dagmar Monett
- Feeding the Machine: The Hidden Human Labour Powering AI – book, James Muldoon, Mark Graham, Callum Cant
- The AI Resist List – project, DAIR, We and AI, and Refugee Law Lab
- Resisting, Refusing, Reclaiming, Reimagining: Charting Challenges to Narratives of AI Inevitability – community research, Duarte and others
- Superbloom: How Technologies of Connection Tear Us Apart – book, Nicholas Carr
- Please Use AI – poem, Shawn Smucker
- We Reject the Use of Generative AI for Reflexive Qualitative Research – paper, Tanisha Jowsey, Virginia Braun, Victoria Clarke, Deborah Lupton and Michelle Fine
- Engaged and Responsible Scholarship: Why Qualitative Researchers Should Not Embrace GenAI – paper, Duc Cuong Nguyen and Catherine Welch
- Another Science is Possible: A Manifesto for Slow Science – book, Isabelle Stengers
- Measuring Up: Evaluating Claims about AI and Productivity in the UK Public Sector – report, Ada Lovelace
- ‘We started seeing people with six fingers’ – Dublin pub bans AI posters to support independent artists’ – poster, The Thomas House
- Say Yes, Do No – project, Dylan Orchard
- On the (im)possibility of sustainable artificial intelligence – paper, Rainer Rehak
- To be human is to live with friction. That’s something AI boosters will never understand – news article, Alexander Hurst (The Guardian)
- Attributing and situating knowledge cannot be left to language models – paper, Roxana Radu and Luc Rocher
- Alt Text as Poetry – project, Bojana Coklyat and Finnegan Shannon
- The human cost of automation bias – blog post, Tania Duarte
- Humans are Biased. Generative AI is Even Worse – news post, Bloomberg
- Technocolonialism: When Technology for Good is Harmful – Mirca Madianou